Downloads · 30 days
42
12% of all-time downloads
zwcf5200/Ornith-1.0-35B-Vision
Ornith-1.0-35B-Vision is a image-text-to-text model from zwcf5200. Use it for the image-text-to-text task on the model card, and read the license before you ship it in a product. It is set up for mlx. The card lists the license as apache-2.0.
Ornith-1.0-35B-Vision is an experimental vision-enabled MLX derivative of deepreinforce-ai/Ornith-1.0-35B, intended for fast local inference on Apple Silicon.
Downloads · 30 days
42
12% of all-time downloads
All-time downloads
340
Public
Parameters
34.3B
20.4 GB on disk
Likes
1
Public
Click a slice to open those files.
.safetensors20.4 GB · 100%
How the weights are stored.
U3234.7B · 99%
From the Hugging Face model README
Ornith-1.0-35B-Vision is an experimental vision-enabled MLX derivative of deepreinforce-ai/Ornith-1.0-35B, intended for fast local inference on Apple Silicon.
It combines the affine-quantized Ornith language body from wang-yang/Ornith-1.0-35B-MTPLX with the source-BF16 Qwen3.5-compatible vision tower and processor metadata from Shiftedx/ornith-1.0-35b-mxfp4-vision-mtplx. The MTP sidecar and all MTP index entries were deliberately removed: this repository is a standard autoregressive VLM and does not require MTP-specific loader patches.
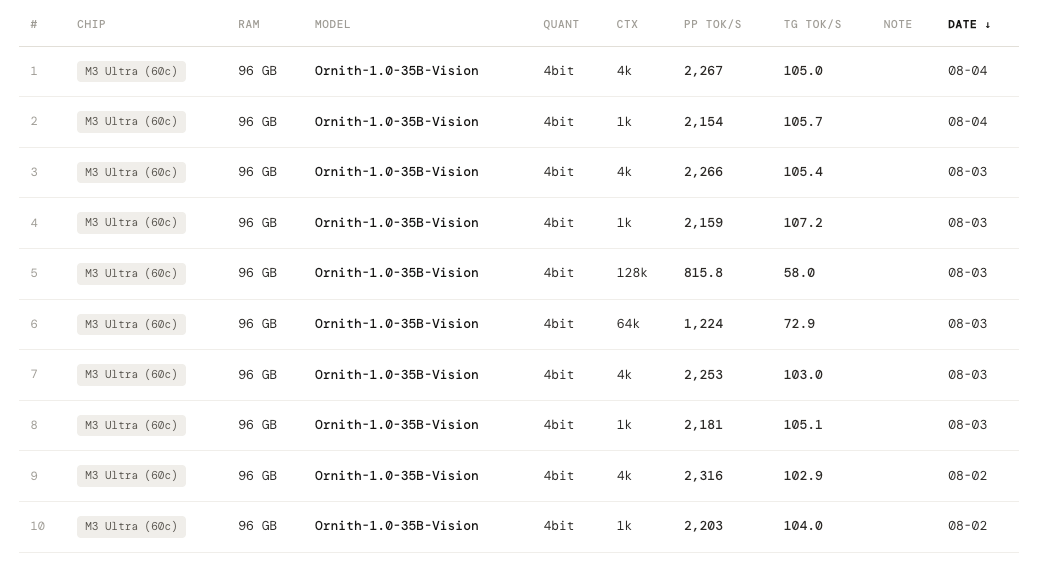
mtp.safetensors; mtp_num_hidden_layers=0Among the 35B-class MLX models evaluated locally by the uploader, this model delivered the highest measured single-request decode speed while retaining vision support. This is a same-machine observation, not a universal cross-hardware ranking.
The following measurements were produced with oMLX on an Apple M3 Ultra with 96 GiB unified
memory, running macOS 26.5.2.
Prompt processing (pp) and text generation (tg) use synthetic token lengths; image
encoding time is not represented by these text-only throughput cases.
| Test | TTFT | TPOT | pp TPS | tg TPS | End-to-end | Throughput | Peak memory |
|---|---|---|---|---|---|---|---|
| pp1024 / tg128 | 464.8 ms | 9.73 ms/tok | 2,202.9 tok/s | 103.6 tok/s | 1.709 s | 674.0 tok/s | 19.35 GB |
| pp4096 / tg128 | 1,769.1 ms | 9.83 ms/tok | 2,315.3 tok/s | 102.5 tok/s | 3.030 s | 1,394.0 tok/s | 20.07 GB |
| Batch | Aggregate tg TPS | Speedup | Aggregate pp TPS | pp TPS/request | Mean TTFT | End-to-end |
|---|---|---|---|---|---|---|
| 1x | 103.6 tok/s | 1.00x | 2,202.9 tok/s | 2,202.9 tok/s | 464.8 ms | 1.709 s |
| 2x | 192.7 tok/s | 1.86x | 1,755.3 tok/s | 877.6 tok/s | 1,166.7 ms | 2.495 s |
| 4x | 288.3 tok/s | 2.78x | 1,761.9 tok/s | 440.5 tok/s | 2,196.5 ms | 4.101 s |
Results are local point measurements. Runtime version, OS version, thermals, cache state, prompt structure and concurrent workloads can materially affect performance.
All runs below used thinking off. These are sampled oMLX evaluations rather than complete official benchmark submissions.
| Benchmark | Score | Correct / evaluated | Full dataset | Time |
|---|---|---|---|---|
| MMLU | 83.0% | 83 / 100 | 14,042 | 52.6 s |
| CMMLU | 82.0% | 82 / 100 | 11,582 | 27.3 s |
| TruthfulQA | 90.0% | 90 / 100 | 817 | 25.4 s |
| HumanEval | 93.0% | 93 / 100 | 164 | 124.2 s |
| MBPP | 86.0% | 86 / 100 | 500 | 71.0 s |
| LiveCodeBench | 40.0% | 12 / 30 | 1,055 | 234.1 s |
The smaller samples, especially the 30-problem LiveCodeBench run, have substantial sampling uncertainty. Scores should only be compared with runs using the same harness, sample IDs, random seed, decoding settings and execution environment. These tests do not measure visual reasoning quality.
Install a recent MLX-VLM build compatible with Qwen3.5 MoE VLM checkpoints, then run:
python -m mlx_vlm.generate \
  --model zwcf5200/Ornith-1.0-35B-Vision \
  --image image.jpg \
  --prompt "Describe this image." \
  --max-tokens 256
The model can also be served by a compatible oMLX release and accessed through its
OpenAI-compatible Chat Completions API using image_url content parts.
The uploader found the following conservative profile more reliable for Hermes-style tool use:
{
  "enable_thinking": false,
  "temperature": 0.4,
  "top_p": 0.9,
  "top_k": 20,
  "min_p": 0.0,
  "repetition_penalty": 1.0,
  "presence_penalty": 0.0,
  "max_tokens": 4096,
  "max_tool_result_tokens": 2048
}
For agent harnesses, use bounded output/tool-turn budgets and reject or deduplicate malformed
or repeated tool calls. Do not use </tool_call> itself as a stop string because removing the
closing marker can prevent the server from parsing a valid call.
0deepreinforce-ai/Ornith-1.0-35B (MIT)wang-yang/Ornith-1.0-35B-MTPLX; its MTP sidecar is not includedShiftedx/ornith-1.0-35b-mxfp4-vision-mtplxReview all upstream model cards and licenses before redistribution or production use. The language lineage includes MIT-licensed Ornith weights, while the vision/Qwen components are subject to Apache-2.0 terms.