
Downloads · 30 days
712
1% of all-time downloads
zai-org/GLM-4.1V-9B-Base
GLM-4.1V-9B-Base is a image-text-to-text model from zai-org. Use it for the image-text-to-text task on the model card, and read the license before you ship it in a product. It is set up for transformers. The card lists the license as mit.
<div align="center" <img src=https://raw.githubusercontent.com/zai-org/GLM-4.1V-Thinking/99c5eb6563236f0ff43605d91d107544da9863b2/resources/logo.svg width="40%"/ </div <p align="center" 📖 View the GLM-4.1V-9B-Thinkin…
Downloads · 30 days
712
1% of all-time downloads
All-time downloads
55.4K
Public
Parameters
10.3B
20.6 GB on disk
Likes
68
Public
Click a slice to open those files.
.safetensors20.6 GB · 100%
From the Hugging Face model README
Vision-Language Models (VLMs) have become foundational components of intelligent systems. As real-world AI tasks grow increasingly complex, VLMs must evolve beyond basic multimodal perception to enhance their reasoning capabilities in complex tasks. This involves improving accuracy, comprehensiveness, and intelligence, enabling applications such as complex problem solving, long-context understanding, and multimodal agents.
Based on the GLM-4-9B-0414 foundation model, we present the new open-source VLM model GLM-4.1V-9B-Thinking, designed to explore the upper limits of reasoning in vision-language models. By introducing a "thinking paradigm" and leveraging reinforcement learning, the model significantly enhances its capabilities. It achieves state-of-the-art performance among 10B-parameter VLMs, matching or even surpassing the 72B-parameter Qwen-2.5-VL-72B on 18 benchmark tasks. We are also open-sourcing the base model GLM-4.1V-9B-Base to support further research into the boundaries of VLM capabilities.
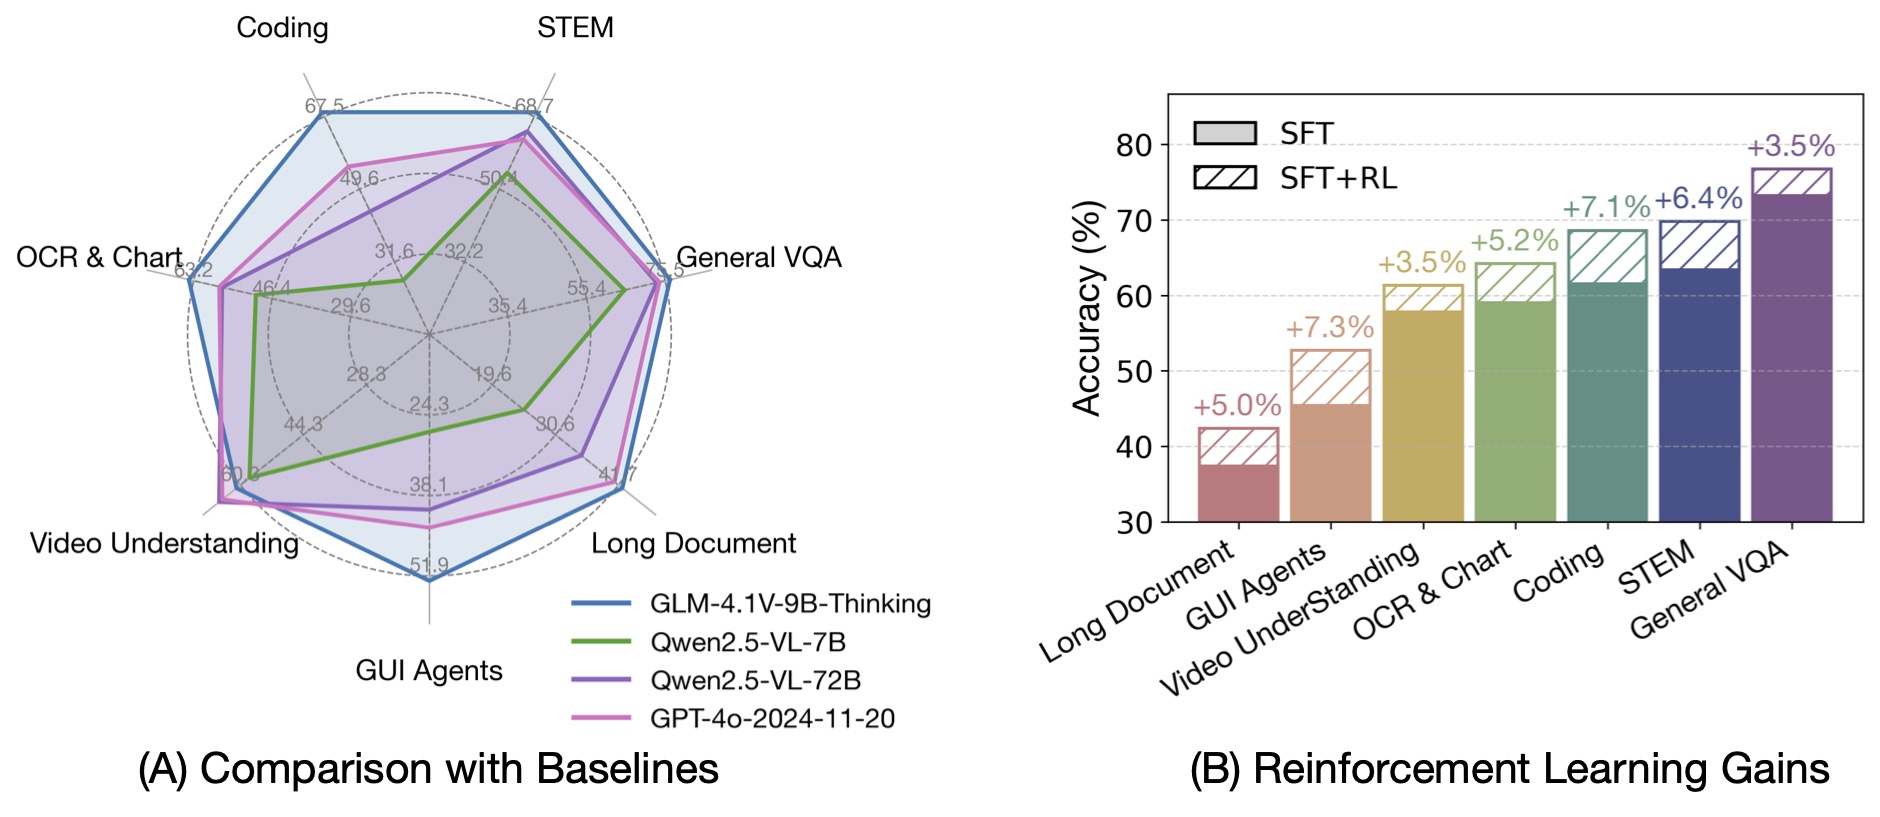
Compared to the previous generation models CogVLM2 and the GLM-4V series, GLM-4.1V-Thinking offers the following improvements:
By incorporating the Chain-of-Thought reasoning paradigm, GLM-4.1V-9B-Thinking significantly improves answer accuracy, richness, and interpretability. It comprehensively surpasses traditional non-reasoning visual models. Out of 28 benchmark tasks, it achieved the best performance among 10B-level models on 23 tasks, and even outperformed the 72B-parameter Qwen-2.5-VL-72B on 18 tasks.
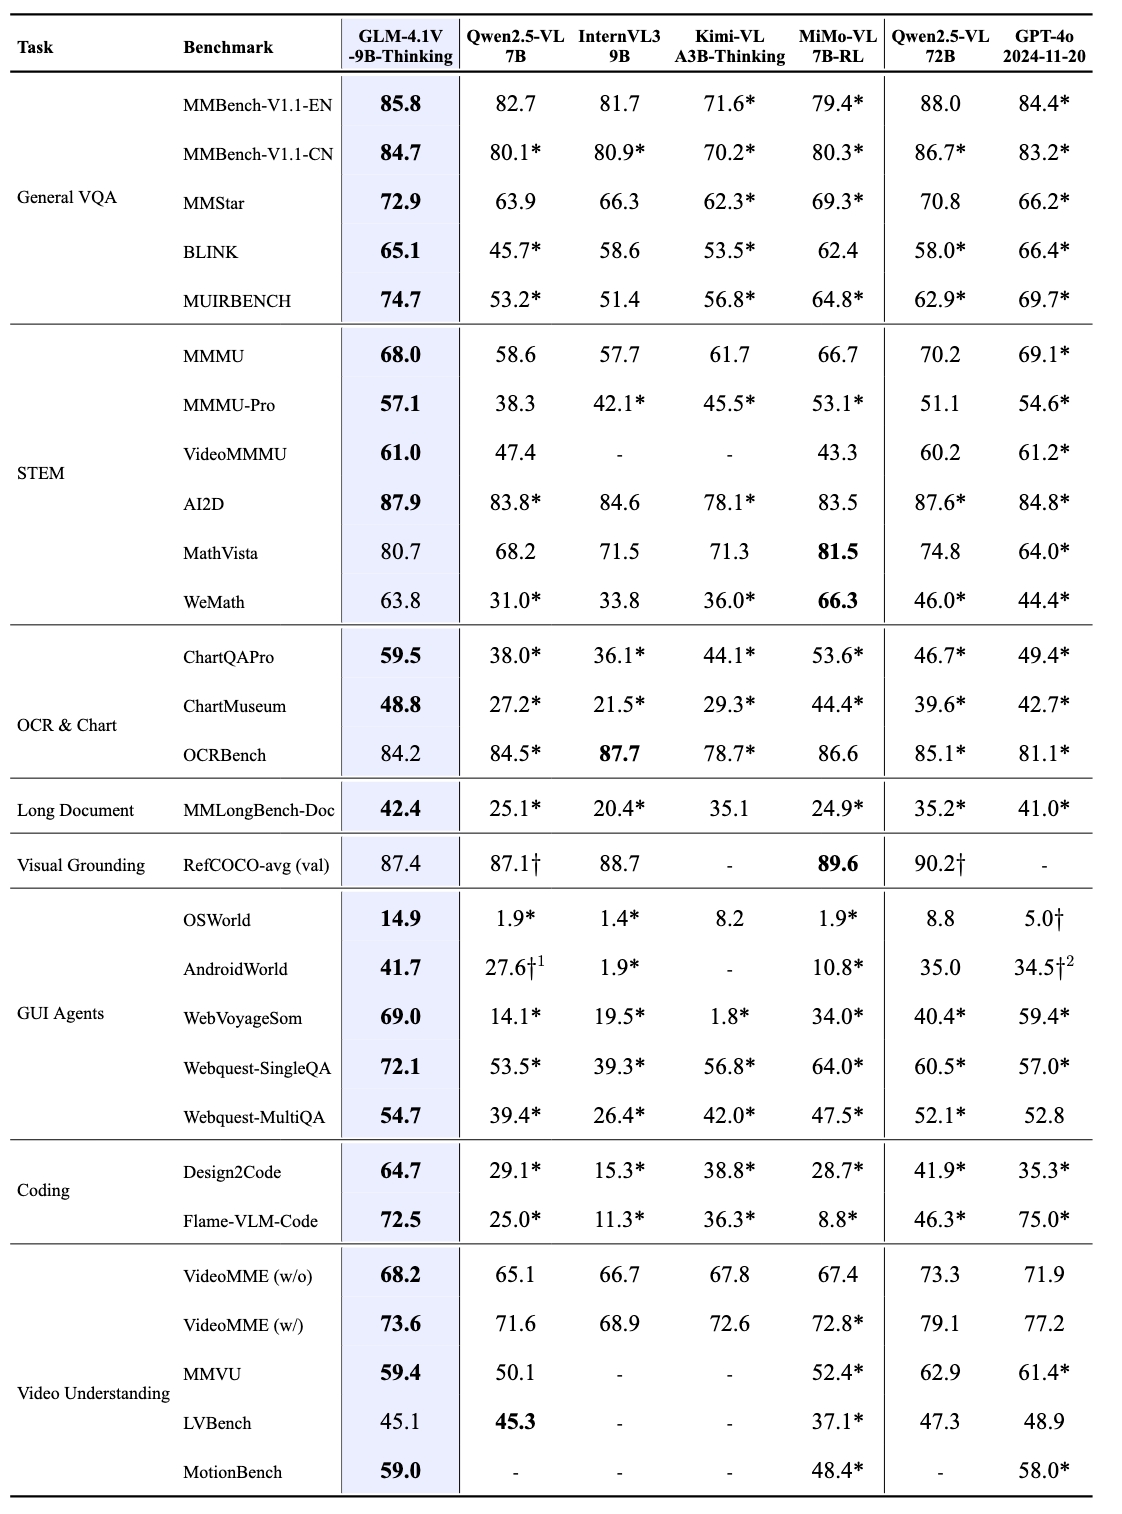
For video reasoning, web demo deployment, and more code, please check our GitHub.