Downloads · 30 days
149
4% of all-time downloads
yuanzhoulvpi/vit-gpt2-image-chinese-captioning
vit-gpt2-image-chinese-captioning is a image-text-to-text model from yuanzhoulvpi. Use it for the image-text-to-text task on the model card, and read the license before you ship it in a product. It is set up for transformers. The card lists the license as mit.
Downloads · 30 days
149
4% of all-time downloads
All-time downloads
4.1K
Public
Parameters
242M
3.5 GB on disk
Likes
6
Public
Click a slice to open those files.
.pt1.7 GB · 49%
How the weights are stored.
F32217M · 90%
From the Hugging Face model README
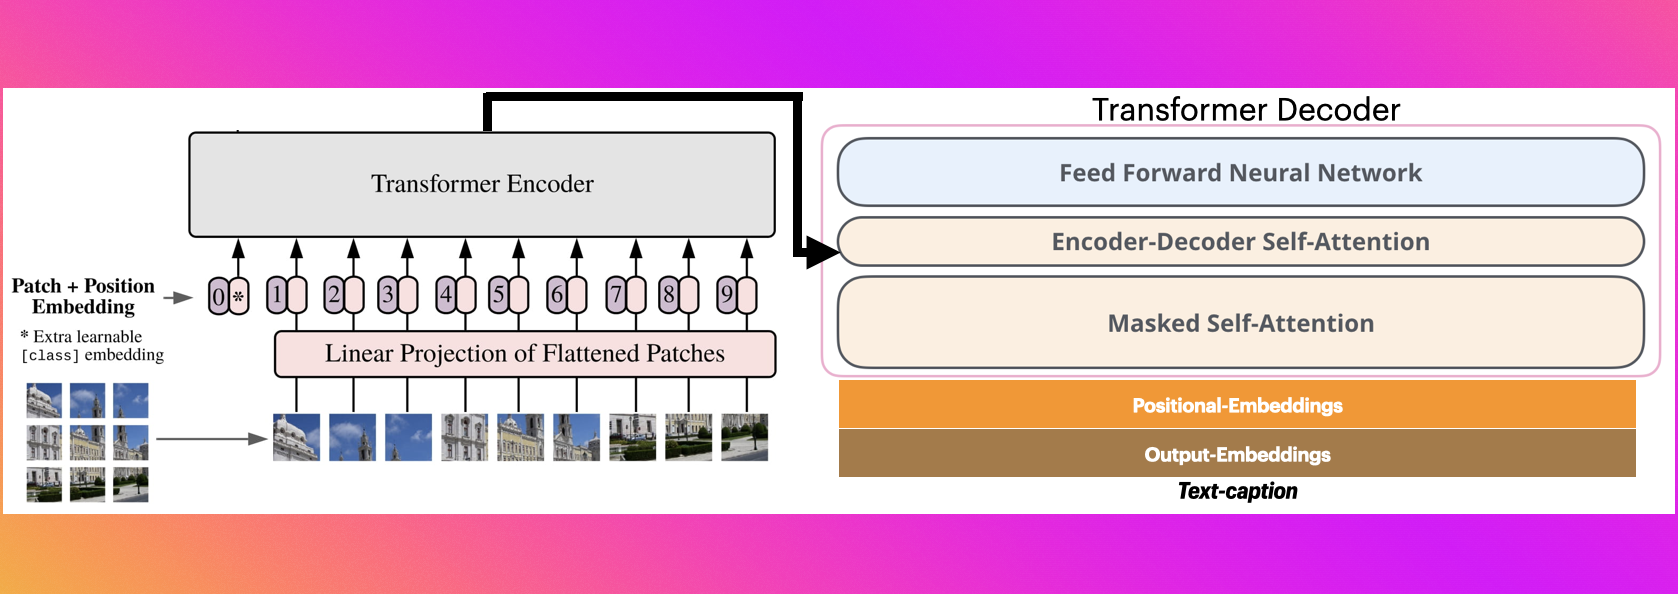
google/vit-base-patch16-224, gpt2使用的是yuanzhoulvpi/gpt2_chinesehttps://github.com/yuanzhoulvpi2017/zero_nlp/tree/main/vit-gpt2-image-chinese-captioning
from transformers import (VisionEncoderDecoderModel,
                          AutoTokenizer,ViTImageProcessor)
import torch
from PIL import Image
vision_encoder_decoder_model_name_or_path = "yuanzhoulvpi/vit-gpt2-image-chinese-captioning"#"vit-gpt2-image-chinese-captioning/checkpoint-3200"

processor = ViTImageProcessor.from_pretrained(vision_encoder_decoder_model_name_or_path)
tokenizer = AutoTokenizer.from_pretrained(vision_encoder_decoder_model_name_or_path)
model = VisionEncoderDecoderModel.from_pretrained(vision_encoder_decoder_model_name_or_path)
device = torch.device("cuda" if torch.cuda.is_available() else "cpu")
model.to(device)
max_length = 16
num_beams = 4
gen_kwargs = {"max_length": max_length, "num_beams": num_beams}


def predict_step(image_paths):
    images = []
    for image_path in image_paths:
        i_image = Image.open(image_path)
        if i_image.mode != "RGB":
            i_image = i_image.convert(mode="RGB")

        images.append(i_image)

    pixel_values = processor(images=images, return_tensors="pt").pixel_values
    pixel_values = pixel_values.to(device)

    output_ids = model.generate(pixel_values, **gen_kwargs)

    preds = tokenizer.batch_decode(output_ids, skip_special_tokens=True)
    preds = [pred.strip() for pred in preds]
    return preds


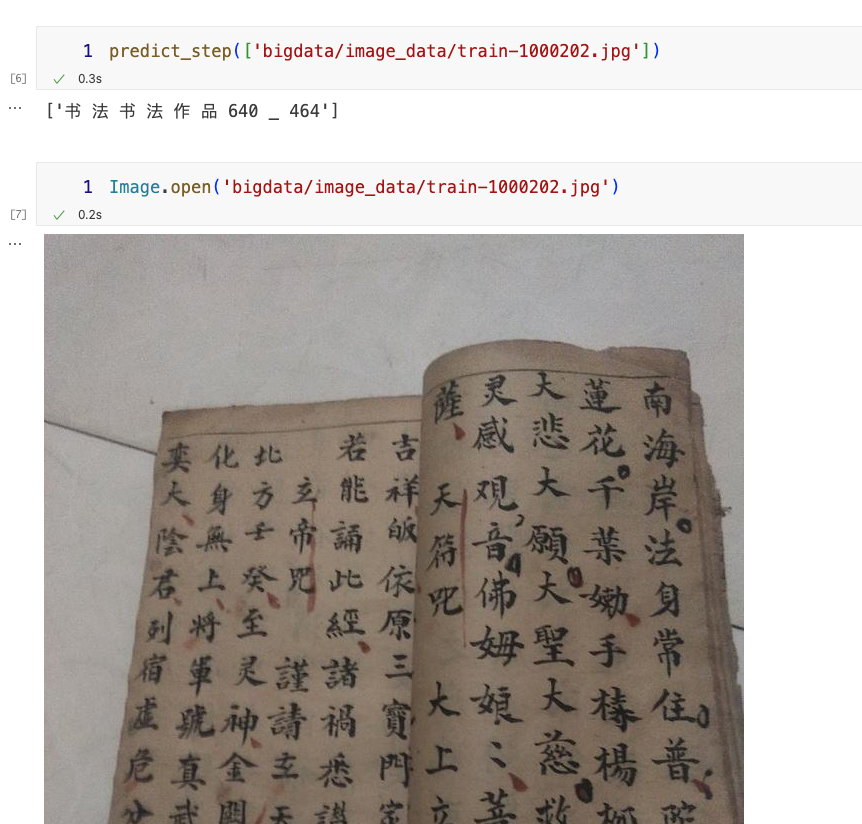
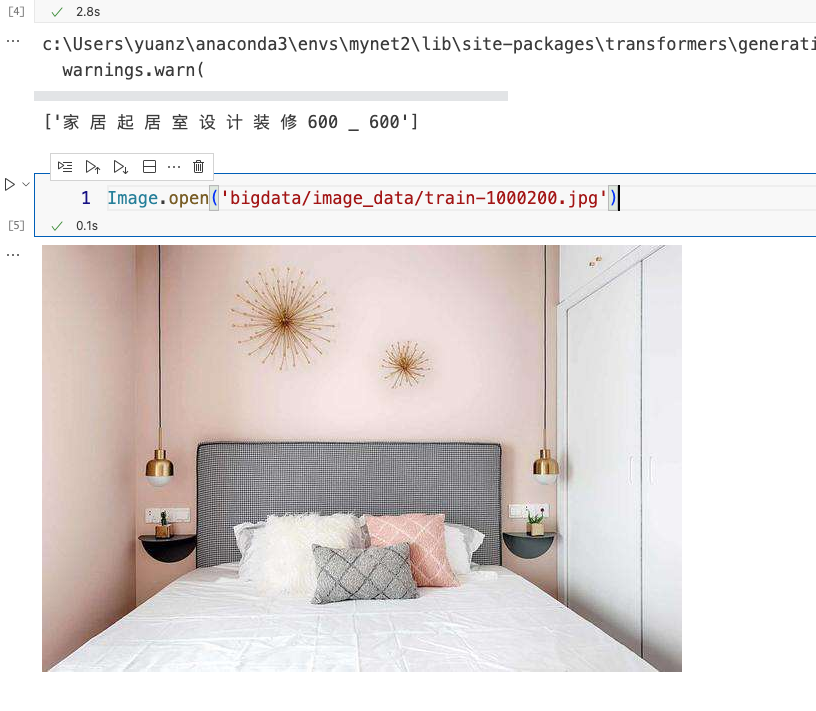
predict_step(['bigdata/image_data/train-1000200.jpg'])