
Downloads · 30 days
145
1% of all-time downloads
yhavinga/t5-base-dutch
t5-base-dutch is a machine learning model from yhavinga. Use it for the machine learning task on the model card, and read the license before you ship it in a product. It is set up for transformers. The card lists the license as apache-2.0.
Created by Yeb Havinga & Dat Nguyen during the Hugging Face community week, organized by HuggingFace and TPU usage sponsored by Google, for the project Pre-train T5 from scratch in Dutch.
Downloads · 30 days
145
1% of all-time downloads
All-time downloads
18.4K
Public
Parameters
223M
9.2 GB on disk
Likes
7
Public
Click a slice to open those files.
.h5892 MB · 24%
From the Hugging Face model README
Created by Yeb Havinga & Dat Nguyen during the Hugging Face community week, organized by HuggingFace and TPU usage sponsored by Google, for the project Pre-train T5 from scratch in Dutch. See also the fine-tuned t5-base-dutch-demo model, and the demo application Netherformer 📰, that are based on this model.
5 jan 2022: Model updated. Evaluation accuracy increased from 0.64 to 0.70.
11 jan 2022: See also yhavinga/t5-v1.1-base-dutch-cased with eval acc 0.78
This t5 model has 222M parameters.
It was pre-trained with masked language modeling (denoise token span corruption) objective on the dataset
mc4_nl_cleaned config full for 1 epoch(s) and a duration of 2d9h,
with a sequence length of 512, batch size 128 and 527500 total steps (35B tokens).
Pre-training evaluation loss and accuracy are 1,38 and 0,70.
Refer to the evaluation section below for a comparison of the pre-trained models on summarization and translation.
Please refer to the original T5 papers and Scale Efficiently papers for more information about the T5 architecture and configs, though it must be noted that this model (t5-base-dutch) is unrelated to these projects and not an 'official' checkpoint.
The model uses a cased SentencePiece tokenizer configured with the Nmt, NFKC, Replace multi-space to single-space normalizers
and has 32003 tokens.
It was trained on Dutch mc4 with scripts from the Huggingface Transformers Flax examples.
See ./raw/main/tokenizer.json for details.
All models listed below are pre-trained on cleaned Dutch mC4, which is the original mC4, except
The Dutch and English models are pre-trained on a 50/50% mix of Dutch mC4 and English C4.
The translation models are fine-tuned on CCMatrix.
Three types of Dutch T5 models have been trained (blog).
t5-base-dutch is the only model with an original T5 config.
The other model types t5-v1.1 and t5-eff have gated-relu instead of relu as activation function,
and trained with a drop-out of 0.0 unless training would diverge (t5-v1.1-large-dutch-cased).
The T5-eff models are models that differ in their number of layers. The table will list
the several dimensions of these models. Not all t5-eff models are efficient, the best example being the inefficient
t5-xl-4L-dutch-english-cased.
| t5-base-dutch | t5-v1.1-base-dutch-uncased | t5-v1.1-base-dutch-cased | t5-v1.1-large-dutch-cased | t5-v1_1-base-dutch-english-cased | t5-v1_1-base-dutch-english-cased-1024 | t5-small-24L-dutch-english | t5-xl-4L-dutch-english-cased | t5-base-36L-dutch-english-cased | t5-eff-xl-8l-dutch-english-cased | t5-eff-large-8l-dutch-english-cased | |
|---|---|---|---|---|---|---|---|---|---|---|---|
| type | t5 | t5-v1.1 | t5-v1.1 | t5-v1.1 | t5-v1.1 | t5-v1.1 | t5 eff | t5 eff | t5 eff | t5 eff | t5 eff |
| d_model | 768 | 768 | 768 | 1024 | 768 | 768 | 512 | 2048 | 768 | 1024 | 1024 |
| d_ff | 3072 | 2048 | 2048 | 2816 | 2048 | 2048 | 1920 | 5120 | 2560 | 16384 | 4096 |
| num_heads | 12 | 12 | 12 | 16 | 12 | 12 | 8 | 32 | 12 | 32 | 16 |
| d_kv | 64 | 64 | 64 | 64 | 64 | 64 | 64 | 64 | 64 | 128 | 64 |
| num_layers | 12 | 12 | 12 | 24 | 12 | 12 | 24 | 4 | 36 | 8 | 8 |
| num parameters | 223M | 248M | 248M | 783M | 248M | 248M | 250M | 585M | 729M | 1241M | 335M |
| feed_forward_proj | relu | gated-gelu | gated-gelu | gated-gelu | gated-gelu | gated-gelu | gated-gelu | gated-gelu | gated-gelu | gated-gelu | gated-gelu |
| dropout | 0.1 | 0.0 | 0.0 | 0.1 | 0.0 | 0.0 | 0.0 | 0.1 | 0.0 | 0.0 | 0.0 |
| dataset | mc4_nl_cleaned | mc4_nl_cleaned full | mc4_nl_cleaned full | mc4_nl_cleaned | mc4_nl_cleaned small_en_nl | mc4_nl_cleaned large_en_nl | mc4_nl_cleaned large_en_nl | mc4_nl_cleaned large_en_nl | mc4_nl_cleaned large_en_nl | mc4_nl_cleaned large_en_nl | mc4_nl_cleaned large_en_nl |
| tr. seq len | 512 | 1024 | 1024 | 512 | 512 | 1024 | 512 | 512 | 512 | 512 | 512 |
| batch size | 128 | 64 | 64 | 64 | 128 | 64 | 128 | 512 | 512 | 64 | 128 |
| total steps | 527500 | 1014525 | 1210154 | 1120k/2427498 | 2839630 | 1520k/3397024 | 851852 | 212963 | 212963 | 538k/1703705 | 851850 |
| epochs | 1 | 2 | 2 | 2 | 10 | 4 | 1 | 1 | 1 | 1 | 1 |
| duration | 2d9h | 5d5h | 6d6h | 8d13h | 11d18h | 9d1h | 4d10h | 6d1h | 17d15h | 4d 19h | 3d 23h |
| optimizer | adafactor | adafactor | adafactor | adafactor | adafactor | adafactor | adafactor | adafactor | adafactor | adafactor | adafactor |
| lr | 0.005 | 0.005 | 0.005 | 0.005 | 0.005 | 0.005 | 0.005 | 0.005 | 0.009 | 0.005 | 0.005 |
| warmup | 10000.0 | 10000.0 | 10000.0 | 10000.0 | 10000.0 | 5000.0 | 20000.0 | 2500.0 | 1000.0 | 1500.0 | 1500.0 |
| eval loss | 1,38 | 1,20 | 0,96 | 1,07 | 1,11 | 1,13 | 1,18 | 1,27 | 1,05 | 1,3019 | 1,15 |
| eval acc | 0,70 | 0,73 | 0,78 | 0,76 | 0,75 | 0,74 | 0,74 | 0,72 | 0,76 | 0,71 | 0,74 |
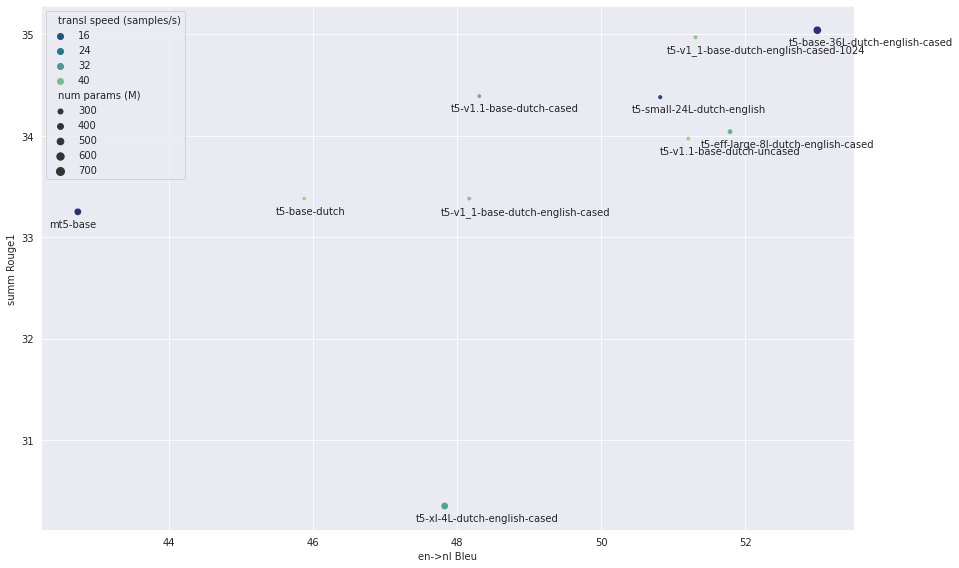
Most models from the list above have been fine-tuned for summarization and translation. The figure below shows the evaluation scores, where the x-axis shows the translation Bleu score (higher is better) and y-axis the summarization Rouge1 translation score (higher is better). Point size is proportional to the model size. Models with faster inference speed are green, slower inference speed is plotted as bleu.
Evaluation was run on fine-tuned models trained with the following settings:
| Summarization | Translation | |
|---|---|---|
| Dataset | CNN Dailymail NL | CCMatrix en -> nl |
| #train samples | 50K | 50K |
| Optimizer | Adam | Adam |
| learning rate | 0.001 | 0.0005 |
| source length | 1024 | 128 |
| target length | 142 | 128 |
| label smoothing | 0.05 | 0.1 |
| #eval samples | 1000 | 1000 |
Note that the amount of training data is limited to a fraction of the total dataset sizes, therefore the scores below can only be used to compare the 'transfer-learning' strength. The fine-tuned checkpoints for this evaluation are not saved, since they were trained for comparison of pre-trained models only.
The numbers for summarization are the Rouge scores on 1000 documents from the test split.
| t5-base-dutch | t5-v1.1-base-dutch-uncased | t5-v1.1-base-dutch-cased | t5-v1_1-base-dutch-english-cased | t5-v1_1-base-dutch-english-cased-1024 | t5-small-24L-dutch-english | t5-xl-4L-dutch-english-cased | t5-base-36L-dutch-english-cased | t5-eff-large-8l-dutch-english-cased | mt5-base | |
|---|---|---|---|---|---|---|---|---|---|---|
| rouge1 | 33.38 | 33.97 | 34.39 | 33.38 | 34.97 | 34.38 | 30.35 | 35.04 | 34.04 | 33.25 |
| rouge2 | 13.32 | 13.85 | 13.98 | 13.47 | 14.01 | 13.89 | 11.57 | 14.23 | 13.76 | 12.74 |
| rougeL | 24.22 | 24.72 | 25.1 | 24.34 | 24.99 | 25.25 | 22.69 | 25.05 | 24.75 | 23.5 |
| rougeLsum | 30.23 | 30.9 | 31.44 | 30.51 | 32.01 | 31.38 | 27.5 | 32.12 | 31.12 | 30.15 |
| samples_per_second | 3.18 | 3.02 | 2.99 | 3.22 | 2.97 | 1.57 | 2.8 | 0.61 | 3.27 | 1.22 |
The models below have been evaluated for English to Dutch translation. Note that the first four models are pre-trained on Dutch only. That they still perform adequate is probably because the translation direction is English to Dutch. The numbers reported are the Bleu scores on 1000 documents from the test split.
| t5-base-dutch | t5-v1.1-base-dutch-uncased | t5-v1.1-base-dutch-cased | t5-v1.1-large-dutch-cased | t5-v1_1-base-dutch-english-cased | t5-v1_1-base-dutch-english-cased-1024 | t5-small-24L-dutch-english | t5-xl-4L-dutch-english-cased | t5-base-36L-dutch-english-cased | t5-eff-large-8l-dutch-english-cased | mt5-base | |
|---|---|---|---|---|---|---|---|---|---|---|---|
| precision_ng1 | 74.17 | 78.09 | 77.08 | 72.12 | 77.19 | 78.76 | 78.59 | 77.3 | 79.75 | 78.88 | 73.47 |
| precision_ng2 | 52.42 | 57.52 | 55.31 | 48.7 | 55.39 | 58.01 | 57.83 | 55.27 | 59.89 | 58.27 | 50.12 |
| precision_ng3 | 39.55 | 45.2 | 42.54 | 35.54 | 42.25 | 45.13 | 45.02 | 42.06 | 47.4 | 45.95 | 36.59 |
| precision_ng4 | 30.23 | 36.04 | 33.26 | 26.27 | 32.74 | 35.72 | 35.41 | 32.61 | 38.1 | 36.91 | 27.26 |
| bp | 0.99 | 0.98 | 0.97 | 0.98 | 0.98 | 0.98 | 0.98 | 0.97 | 0.98 | 0.98 | 0.98 |
| score | 45.88 | 51.21 | 48.31 | 41.59 | 48.17 | 51.31 | 50.82 | 47.83 | 53 | 51.79 | 42.74 |
| samples_per_second | 45.19 | 45.05 | 38.67 | 10.12 | 42.19 | 42.61 | 12.85 | 33.74 | 9.07 | 37.86 | 9.03 |
The models t5-small-24L-dutch-english and t5-base-36L-dutch-english have been fine-tuned for both language
directions on the first 25M samples from CCMatrix, giving a total of 50M training samples.
Evaluation is performed on out-of-sample CCMatrix and also on Tatoeba and Opus Books.
The _bp columns list the brevity penalty. The avg_bleu score is the bleu score
averaged over all three evaluation datasets. The best scores displayed in bold for both translation directions.
| t5-base-36L-ccmatrix-multi | t5-base-36L-ccmatrix-multi | t5-small-24L-ccmatrix-multi | t5-small-24L-ccmatrix-multi | |
|---|---|---|---|---|
| source_lang | en | nl | en | nl |
| target_lang | nl | en | nl | en |
| source_prefix | translate English to Dutch: | translate Dutch to English: | translate English to Dutch: | translate Dutch to English: |
| ccmatrix_bleu | 56.8 | 62.8 | 57.4 | 63.1 |
| tatoeba_bleu | 46.6 | 52.8 | 46.4 | 51.7 |
| opus_books_bleu | 13.5 | 24.9 | 12.9 | 23.4 |
| ccmatrix_bp | 0.95 | 0.96 | 0.95 | 0.96 |
| tatoeba_bp | 0.97 | 0.94 | 0.98 | 0.94 |
| opus_books_bp | 0.8 | 0.94 | 0.77 | 0.89 |
| avg_bleu | 38.96 | 46.86 | 38.92 | 46.06 |
| max_source_length | 128 | 128 | 128 | 128 |
| max_target_length | 128 | 128 | 128 | 128 |
| adam_beta1 | 0.9 | 0.9 | 0.9 | 0.9 |
| adam_beta2 | 0.997 | 0.997 | 0.997 | 0.997 |
| weight_decay | 0.05 | 0.05 | 0.002 | 0.002 |
| lr | 5e-05 | 5e-05 | 0.0005 | 0.0005 |
| label_smoothing_factor | 0.15 | 0.15 | 0.1 | 0.1 |
| train_batch_size | 128 | 128 | 128 | 128 |
| warmup_steps | 2000 | 2000 | 2000 | 2000 |
| total steps | 390625 | 390625 | 390625 | 390625 |
| duration | 4d 5h | 4d 5h | 3d 2h | 3d 2h |
| num parameters | 729M | 729M | 250M | 250M |
This project would not have been possible without compute generously provided by Google through the TPU Research Cloud. The HuggingFace 🤗 ecosystem was instrumental in all parts of the training. Weights & Biases made it possible to keep track of many training sessions and orchestrate hyper-parameter sweeps with insightful visualizations. The following repositories where helpful in setting up the TPU-VM, and getting an idea what sensible hyper-parameters are for training gpt2 from scratch:
Created by Yeb Havinga