
Downloads · 30 days
17
2% of all-time downloads
webpolis/zenos-gpt-j-6B-instruct-4bit
zenos-gpt-j-6B-instruct-4bit is a text generation model from webpolis. Use it when you need the model to write or continue text. It is set up for transformers.
- Name: zenos-gpt-j-6B-instruct-4bit - Datasets Used: Alpaca Spanish, Evol Instruct - Architecture: GPT-J - Model Size: 6 Billion parameters - Precision: 4 bits
Downloads · 30 days
17
2% of all-time downloads
All-time downloads
748
Public
Parameters
6.2B
22.1 GB on disk
Likes
1
Public
Click a slice to open those files.
.bin7.1 GB · 66%
How the weights are stored.
U85.8B · 93%
From the Hugging Face model README
Zenos GPT-J 6B Instruct 4-bit is a Spanish Instruction capable model based on the GPT-J architecture with 6 billion parameters. It has been fine-tuned on the Alpaca Spanish and Evol Instruct datasets, making it particularly suitable for natural language understanding and generation tasks in Spanish.
An experimental Twitter (X) bot is available at https://twitter.com/ZenosBot which makes comments on news published in media outlets from Argentina.
The latest development version of Transformers, which includes serialization of 4 bits models.
Since this is a compressed version (4 bits), it can fit into ~7GB of VRAM.
You can use this model for various natural language processing tasks such as text generation, summarization, and more. Below is an example of how to use it in Python with the Transformers library:
from transformers import AutoTokenizer, AutoModelForCausalLM, GenerationConfig

# Load the tokenizer and model
tokenizer = AutoTokenizer.from_pretrained("webpolis/zenos-gpt-j-6B-instruct-4bit")
model = AutoModelForCausalLM.from_pretrained(
    "webpolis/zenos-gpt-j-6B-instruct-4bit",
    use_safetensors=True
)

user_msg = '''Escribe un poema breve utilizando los siguientes conceptos:

Bienestar, Corriente, Iluminación, Sed'''

# Generate text; watch out the padding between [INST] ... [/INST]
prompt = f'[INST] {user_msg} [/INST]'

inputs = tokenizer(prompt, return_tensors="pt")
input_ids = inputs["input_ids"].to(model.device)
attention_mask = inputs["attention_mask"].to(model.device)

generation_config = GenerationConfig(
    temperature=0.2,
    top_p=0.8,
    top_k=40,
    num_beams=1,
    repetition_penalty=1.3,
    do_sample=True
)

with torch.no_grad():
    generation_output = model.generate(
        input_ids=input_ids,
        pad_token_id=tokenizer.eos_token_id,
        attention_mask=attention_mask,
        generation_config=generation_config,
        return_dict_in_generate=True,
        output_scores=False,
        max_new_tokens=512,
        early_stopping=True
    )

s = generation_output.sequences[0]
output = tokenizer.decode(s)
start_txt = output.find('[/INST]') + len('[/INST]')
end_txt = output.find("<|endoftext|>", start_txt)
answer = output[start_txt:end_txt]

print(answer)
Currently, the HuggingFace's Inference Tool UI doesn't properly load the model. However, you can use it with regular Python code as shown above once you meet the requirements.
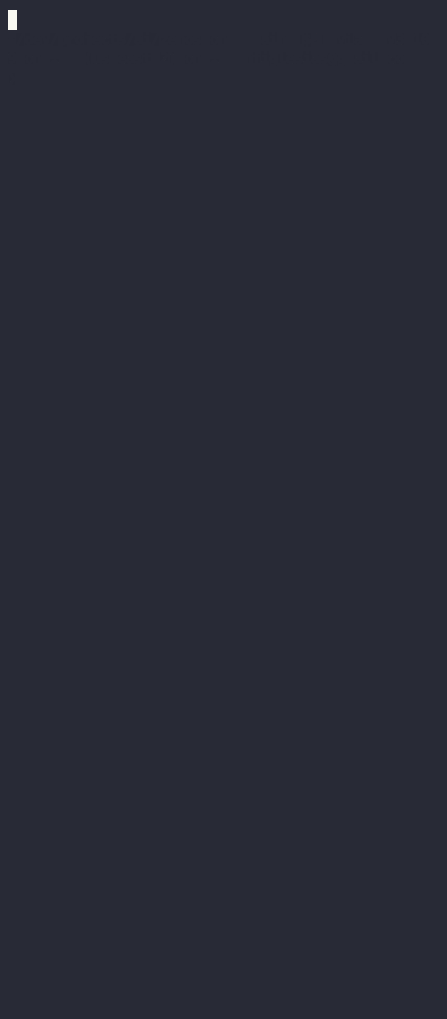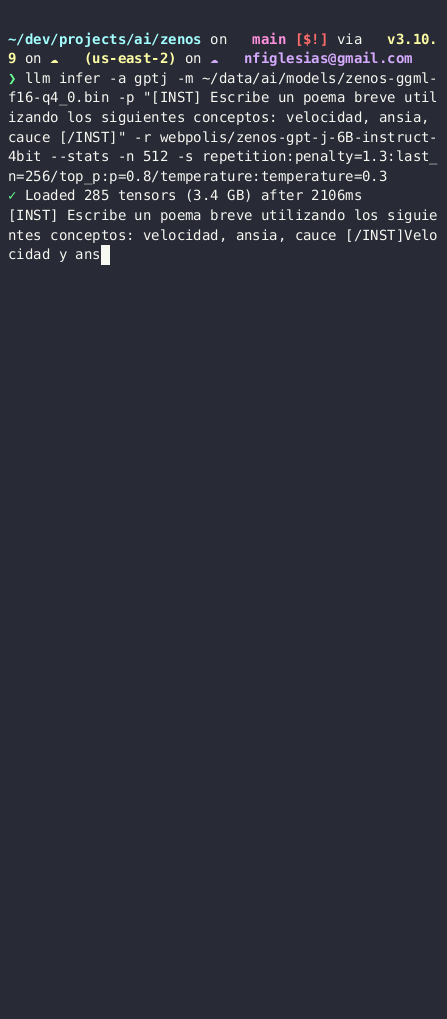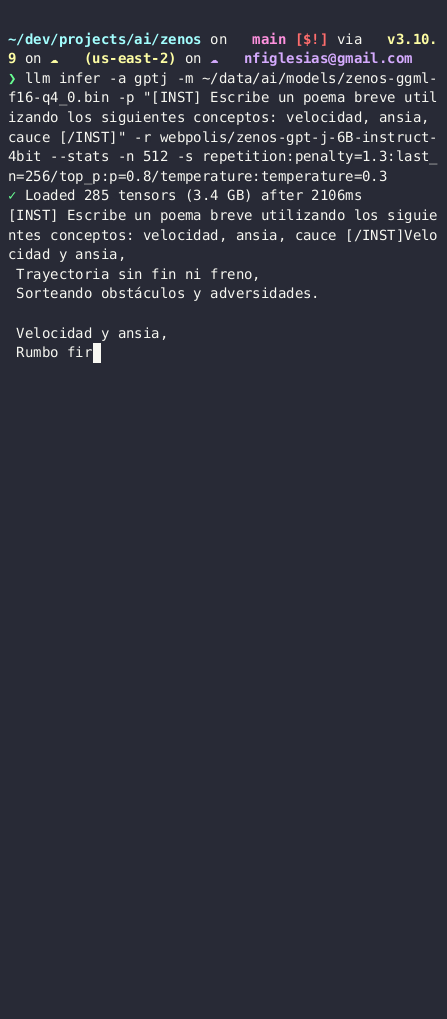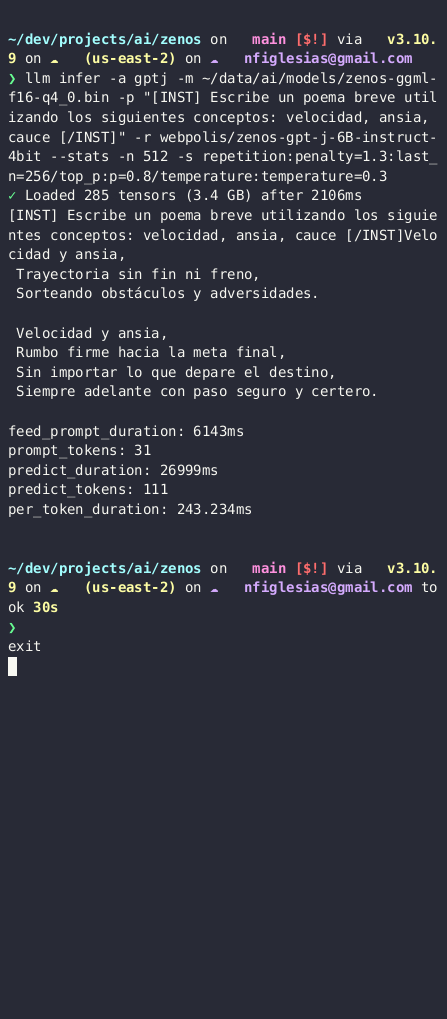
Best performance can be achieved downloading the GGML 4 bits model and doing inference using the rustformers' llm tool.
For optimal performance:
In my Core i7 laptop it goes around 250ms per token:
This model was developed by Nicolás Iglesias using the Hugging Face Transformers library.
Copyright 2023 Nicolás Iglesias
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this software except in compliance with the License. You may obtain a copy of the License at
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the specific language governing permissions and limitations under the License.