
Downloads · 30 days
41
10% of all-time downloads
upwitu/qwen3-4b-sft-all
qwen3-4b-sft-all is a text generation model from upwitu. Use it when you need the model to write or continue text. It is set up for transformers. The card lists the license as apache-2.0.
Downloads · 30 days
41
10% of all-time downloads
All-time downloads
418
Public
Parameters
4B
8.1 GB on disk
Likes
0
Public
Click a slice to open those files.
.safetensors8 GB · 100%
From the Hugging Face model README
This model contains the full 16-bit (bfloat16) merged weights of Qwen3-4B-Instruct fine-tuned on the multi-task CAR-Bench Winner Dataset. The training trajectories synthesize safety invariants and execution patterns from the top three winning architectures of the IJCAI 2026 CAR-Bench competition:
AUT-POL:001), Confirmation Gate (AUT-POL:002), Actuator Boundary Gates (AUT-POL:007/008).[Context Audit], [Policy Check], [Tool Selection & Provenance], [Execution Plan]), and 2-step ID Provenance (AUT-POL:018).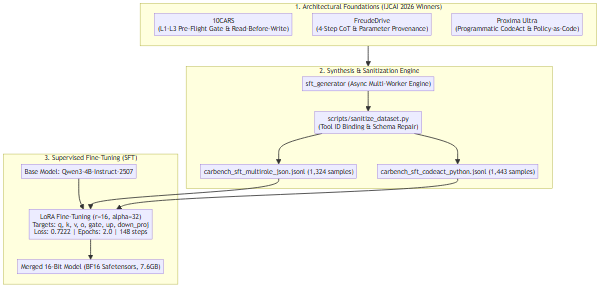
flowchart TD
    subgraph Papers["1. Architectural Foundations (IJCAI 2026 Winners)"]
        P1["10CARS<br/>(L1-L3 Pre-Flight Gate & Read-Before-Write)"]
        P2["FreudeDrive<br/>(4-Step CoT & Parameter Provenance)"]
        P3["Proxima Ultra<br/>(Programmatic CodeAct & Policy-as-Code)"]
    end

    subgraph DataGen["2. Synthesis & Sanitization Engine"]
        GEN["sft_generator (Async Multi-Worker Engine)"]
        SAN["scripts/sanitize_dataset.py<br/>(Tool ID Binding & Schema Repair)"]
        D1["carbench_sft_multirole_json.jsonl (1,324 samples)"]
        D2["carbench_sft_codeact_python.jsonl (1,443 samples)"]
        GEN --> SAN
        SAN --> D1
        SAN --> D2
    end

    subgraph Training["3. Supervised Fine-Tuning (SFT)"]
        BASE["Base Model: Qwen3-4B-Instruct-2507"]
        LORA["LoRA Fine-Tuning (r=16, alpha=32)<br/>Targets: q, k, v, o, gate, up, down_proj<br/>Loss: 0.7222 | Epochs: 2.0 | 148 steps"]
        MERGE["Merged 16-Bit Model (BF16 Safetensors, 7.6GB)"]
        BASE --> LORA --> MERGE
    end

    Papers --> DataGen
    D1 --> LORA
    D2 --> LORA
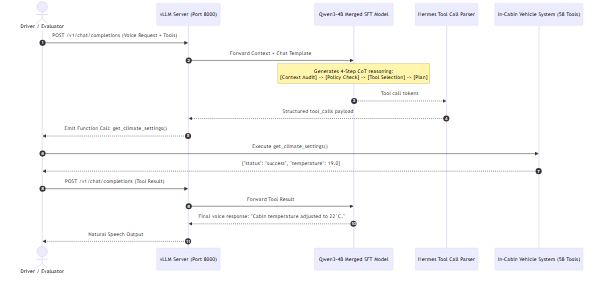
sequenceDiagram
    autonumber
    actor Driver as Driver / Evaluator
    participant vLLM as vLLM Server (Port 8000)
    participant Model as Qwen3-4B Merged SFT Model
    participant Parser as Hermes Tool Call Parser
    participant Vehicle as In-Cabin Vehicle System (58 Tools)

    Driver->>vLLM: POST /v1/chat/completions (Voice Request + Tools)
    vLLM->>Model: Forward Context + Chat Template
    Note over Model: Generates 4-Step CoT reasoning:<br/>[Context Audit] -> [Policy Check] -> [Tool Selection] -> [Plan]
    Model-->>Parser: Tool call tokens
    Parser-->>vLLM: Structured tool_calls payload
    vLLM-->>Driver: Emit Function Call: get_climate_settings()
    Driver->>Vehicle: Execute get_climate_settings()
    Vehicle-->>Driver: {"status": "success", "temperature": 19.0}
    Driver->>vLLM: POST /v1/chat/completions (Tool Result)
    vLLM->>Model: Forward Tool Result
    Model-->>vLLM: Final voice response: "Cabin temperature adjusted to 22°C."
    vLLM-->>Driver: Natural Speech Output
Run the merged model locally with the official vLLM OpenAI-compatible server:
vllm serve upwitu/qwen3-4b-sft-all \
    --port 8000 \
    --dtype bfloat16 \
    --max-model-len 8192 \
    --gpu-memory-utilization 0.90 \
    --tool-call-parser hermes
import torch
from transformers import AutoModelForCausalLM, AutoTokenizer

model_id = "upwitu/qwen3-4b-sft-all"

tokenizer = AutoTokenizer.from_pretrained(model_id)
model = AutoModelForCausalLM.from_pretrained(
    model_id,
    torch_dtype=torch.bfloat16,
    device_map="auto"
)

messages = [
    {"role": "system", "content": "You are a professional in-cabin autonomous vehicle AI assistant. Follow 10CARS safety rules: inspect before mutating, ask confirmation for safety-critical operations, and respect operational limits."},
    {"role": "user", "content": "Set cabin temperature to 23°C."}
]

prompt = tokenizer.apply_chat_template(messages, tokenize=False, add_generation_prompt=True)
inputs = tokenizer(prompt, return_tensors="pt").to(model.device)

outputs = model.generate(**inputs, max_new_tokens=512, temperature=0.2)
response = tokenizer.decode(outputs[0][inputs.input_ids.shape[1]:], skip_special_tokens=True)
print(response)
Mô hình chứa toàn bộ trọng số 16-bit hợp nhất (bfloat16) của Qwen3-4B-Instruct được tinh chỉnh SFT trên tập dữ liệu CAR-Bench Winner Dataset. Dữ liệu huấn luyện chắt lọc các quy tắc an toàn và mô thức điều phối từ ba đội tuyển vô địch cuộc thi CAR-Bench (IJCAI 2026):
AUT-POL:001), cổng xác nhận (AUT-POL:002), giới hạn tham số vận hành (AUT-POL:007/008).Context Audit $\to$ Policy Check $\to$ Tool Selection & Provenance $\to$ Execution Plan), xác thực nguồn gốc ID 2 bước (AUT-POL:018).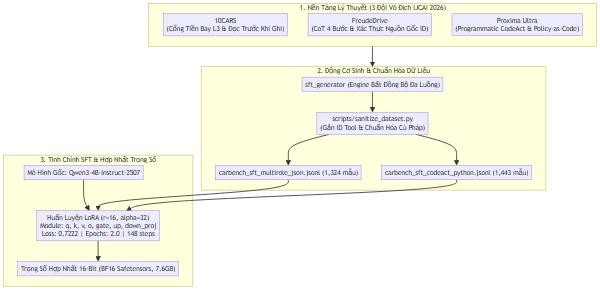
flowchart TD
    subgraph NenTang["1. Nền Tảng Lý Thuyết (3 Đội Vô Địch IJCAI 2026)"]
        P1["10CARS<br/>(Cổng Tiền Bay L3 & Đọc Trước Khi Ghi)"]
        P2["FreudeDrive<br/>(CoT 4 Bước & Xác Thực Nguồn Gốc ID)"]
        P3["Proxima Ultra<br/>(Programmatic CodeAct & Policy-as-Code)"]
    end

    subgraph SinhDuLieu["2. Động Cơ Sinh & Chuẩn Hóa Dữ Liệu"]
        GEN["sft_generator (Engine Bất Đồng Bộ Đa Luồng)"]
        SAN["scripts/sanitize_dataset.py<br/>(Gắn ID Tool & Chuẩn Hóa Cú Pháp)"]
        D1["carbench_sft_multirole_json.jsonl (1,324 mẫu)"]
        D2["carbench_sft_codeact_python.jsonl (1,443 mẫu)"]
        GEN --> SAN
        SAN --> D1
        SAN --> D2
    end

    subgraph HuanLuyen["3. Tinh Chỉnh SFT & Hợp Nhất Trọng Số"]
        BASE["Mô Hình Gốc: Qwen3-4B-Instruct-2507"]
        LORA["Huấn Luyện LoRA (r=16, alpha=32)<br/>Module: q, k, v, o, gate, up, down_proj<br/>Loss: 0.7222 | Epochs: 2.0 | 148 steps"]
        MERGE["Trọng Số Hợp Nhất 16-Bit (BF16 Safetensors, 7.6GB)"]
        BASE --> LORA --> MERGE
    end

    NenTang --> SinhDuLieu
    D1 --> LORA
    D2 --> LORA
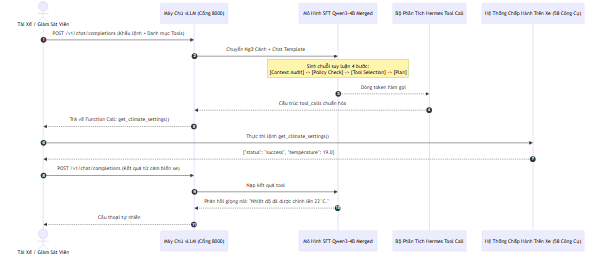
sequenceDiagram
    autonumber
    actor TaiXe as Tài Xế / Giám Sát Viên
    participant vLLM as Máy Chủ vLLM (Cổng 8000)
    participant MoHinh as Mô Hình SFT Qwen3-4B Merged
    participant Parser as Bộ Phân Tích Hermes Tool Call
    participant Xe as Hệ Thống Chấp Hành Trên Xe (58 Công Cụ)

    TaiXe->>vLLM: POST /v1/chat/completions (Khẩu lệnh + Danh mục Tools)
    vLLM->>MoHinh: Chuyển Ngữ Cảnh + Chat Template
    Note over MoHinh: Sinh chuỗi suy luận 4 bước:<br/>[Context Audit] -> [Policy Check] -> [Tool Selection] -> [Plan]
    MoHinh-->>Parser: Dòng token hàm gọi
    Parser-->>vLLM: Cấu trúc tool_calls chuẩn hóa
    vLLM-->>TaiXe: Trả về Function Call: get_climate_settings()
    TaiXe->>Xe: Thực thi lệnh get_climate_settings()
    Xe-->>TaiXe: {"status": "success", "temperature": 19.0}
    TaiXe->>vLLM: POST /v1/chat/completions (Kết quả từ cảm biến xe)
    vLLM->>MoHinh: Nạp kết quả tool
    MoHinh-->>vLLM: Phản hồi giọng nói: "Nhiệt độ đã được chỉnh lên 22°C."
    vLLM-->>TaiXe: Câu thoại tự nhiên