
Downloads · 30 days
14.1K
32% of all-time downloads
typhoon-ai/typhoon-whisper-turbo
typhoon-whisper-turbo is a automatic speech recognition model from typhoon-ai. Use it when you need speech turned into text. It is set up for transformers. The card lists the license as mit.
Typhoon Whisper Turbo is a state-of-the-art Thai Automatic Speech Recognition (ASR) model fine-tuned on the OpenAI Whisper Large v3 Turbo architecture. It is engineered to deliver a balance of high accuracy and low la…
Downloads · 30 days
14.1K
32% of all-time downloads
All-time downloads
44.4K
Public
Parameters
809M
1.6 GB on disk
Likes
7
Public
Click a slice to open those files.
.safetensors1.6 GB · 100%
From the Hugging Face model README
Typhoon Whisper Turbo is a state-of-the-art Thai Automatic Speech Recognition (ASR) model fine-tuned on the OpenAI Whisper Large v3 Turbo architecture. It is engineered to deliver a balance of high accuracy and low latency for offline transcription, significantly outperforming standard Whisper models in throughput while maintaining robust performance on Thai speech.
The model was presented in the paper Typhoon ASR Real-time: FastConformer-Transducer for Thai Automatic Speech Recognition.
By using this model, you agree to the OpenTyphoon Terms and Conditions and acknowledge the Privacy Notice: https://opentyphoon.ai/tac · https://opentyphoon.ai/privacy
The model was trained on approximately 11,000 hours of Thai audio, curated and normalized using the SCB 10X Typhoon data pipeline to ensure consistent handling of Thai numbers, repetition markers, and context-dependent ambiguities.
Typhoon Whisper Turbo achieves competitive performance against large-scale offline models on Thai speech recognition tasks.
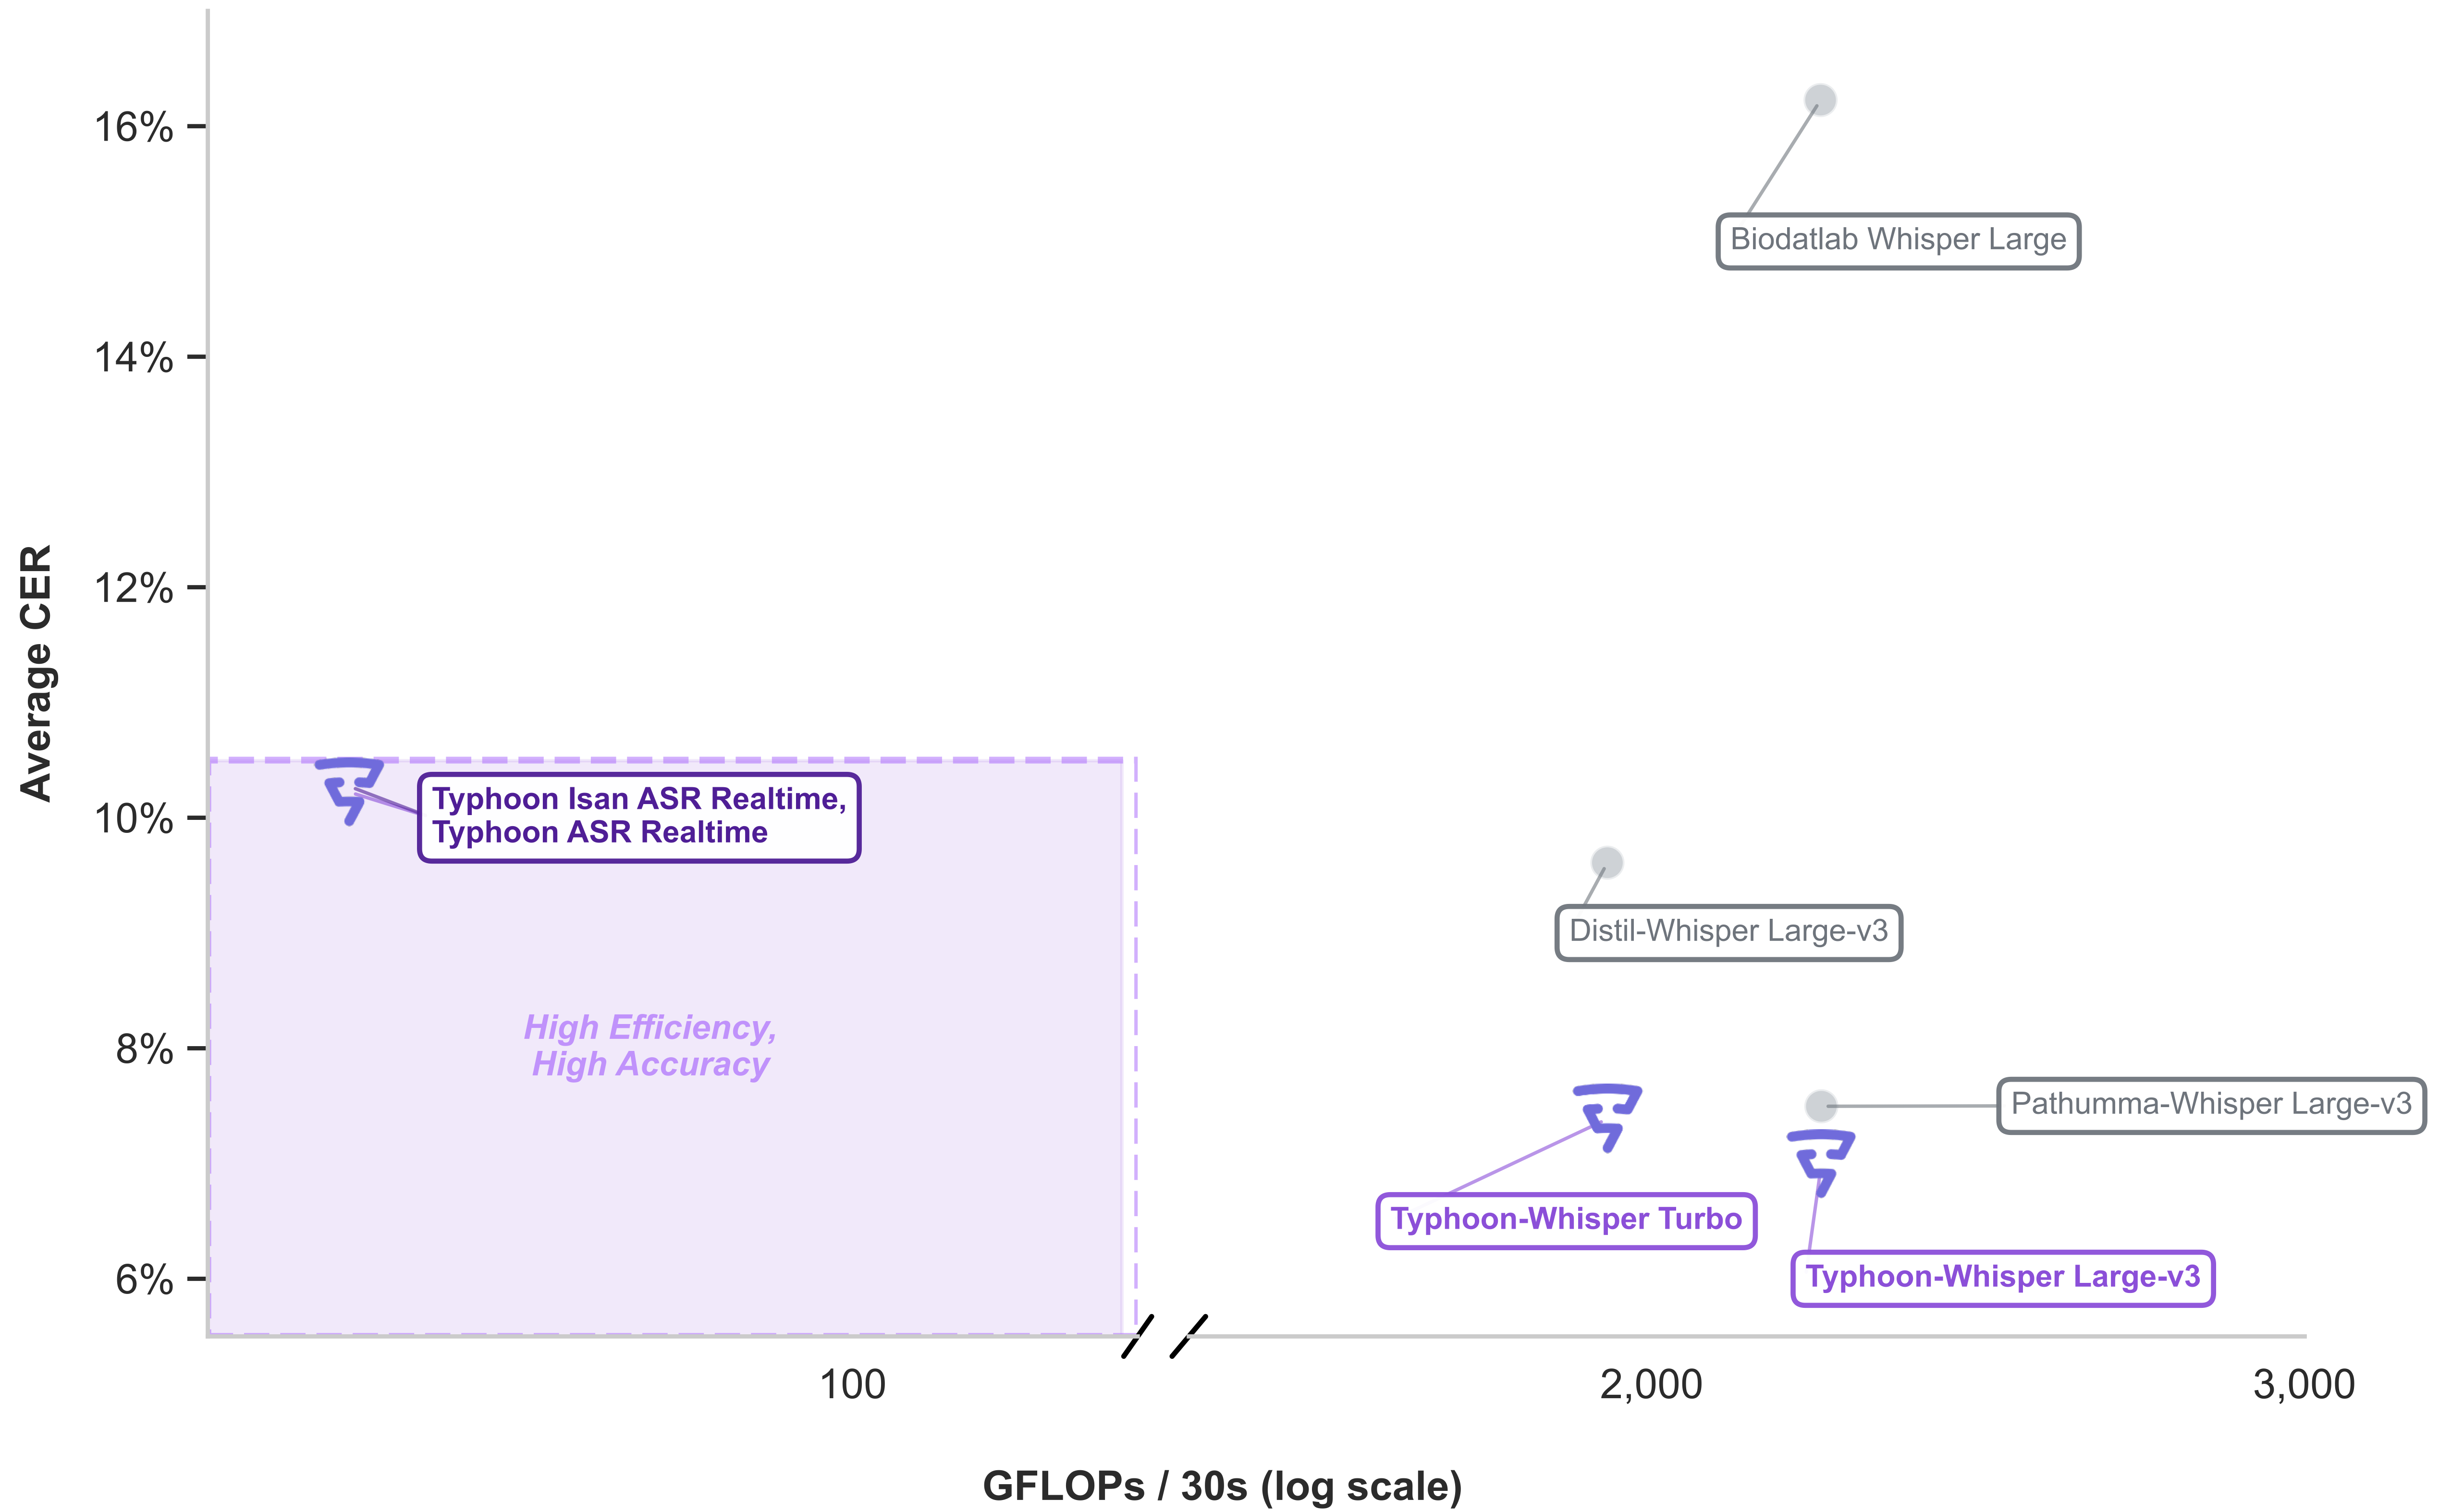
Note: Lower CER (Character Error Rate) is better. Results on Gigaspeech2 (Clean/Academic), TVSpeech (Noisy/In-the-wild), and Google Fleurs (Thai) testset.
You can use this model directly with the Hugging Face transformers library.
pip install transformers torch accelerate
import torch
from transformers import AutoModelForSpeechSeq2Seq, AutoProcessor, pipeline

device = "cuda:0" if torch.cuda.is_available() else "cpu"
torch_dtype = torch.bfloat16 if torch.cuda.is_available() else torch.float32

model_id = "scb10x/typhoon-whisper-turbo"

model = AutoModelForSpeechSeq2Seq.from_pretrained(
    model_id, torch_dtype=torch_dtype, low_cpu_mem_usage=True, use_safetensors=True
)
model.to(device)

processor = AutoProcessor.from_pretrained(model_id)

pipe = pipeline(
    "automatic-speech-recognition",
    model=model,
    tokenizer=processor.tokenizer,
    feature_extractor=processor.feature_extractor,
    max_new_tokens=448,
    chunk_length_s=30,
    batch_size=16,
    return_timestamps=True,
    torch_dtype=torch_dtype,
    device=device,
)

# Transcribe
result = pipe("path_to_audio.wav", generate_kwargs={"language": "thai"})
print(result["text"])
The model was trained on approximately 11,000 hours of Thai audio data, including:
All data was normalized using the Typhoon data pipeline to ensure:
Typhoon Whisper Turbo is based on OpenAI Whisper Large v3 Turbo, achieving performance comparable to state-of-the-art models while being significantly more efficient:
This model is released under the MIT License, inherited from OpenAI Whisper.
If you use this model in your research or application, please cite our technical report:

@misc{warit2026typhoonasrr,
      title={Typhoon ASR Real-time: FastConformer-Transducer for Thai Automatic Speech Recognition},
      author={Warit Sirichotedumrong and Adisai Na-Thalang and Potsawee Manakul and Pittawat Taveekitworachai and Sittipong Sripaisarnmongkol and Kunat Pipatanakul},
      year={2026},
      eprint={2601.13044},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2601.13044},
}
For questions or feedback, please visit our website or open an issue on the model's repository.
Developed by: Typhoon Team, SCB 10X
Model Card Version: 1.0
Last Updated: January 2026