
Downloads · 30 days
72
3% of all-time downloads
tuwonga/takeON
takeON is a text-to-image model from tuwonga. Use it when you need an image from a text prompt. It is set up for diffusers. The card lists the license as creativeml-openrail-m.
This is a fine-tuned Stable Diffusion model (based on v1.5) trained on screenshots from 80s music video Take on me (from A-HA band). Use the token takeON in your prompts to use the style.
Downloads · 30 days
72
3% of all-time downloads
All-time downloads
2.1K
Public
Repo size
9.7 GB
Likes
16
Public
Click a slice to open those files.
.bin5.5 GB · 56%
From the Hugging Face model README
This is a fine-tuned Stable Diffusion model (based on v1.5) trained on screenshots from 80s music video Take on me (from A-HA band). Use the token takeON in your prompts to use the style.
Download the ckpt file from "files and versions" tab into the stable diffusion models folder of your web-ui of choice.
--
Characters and scenes rendered with this model:
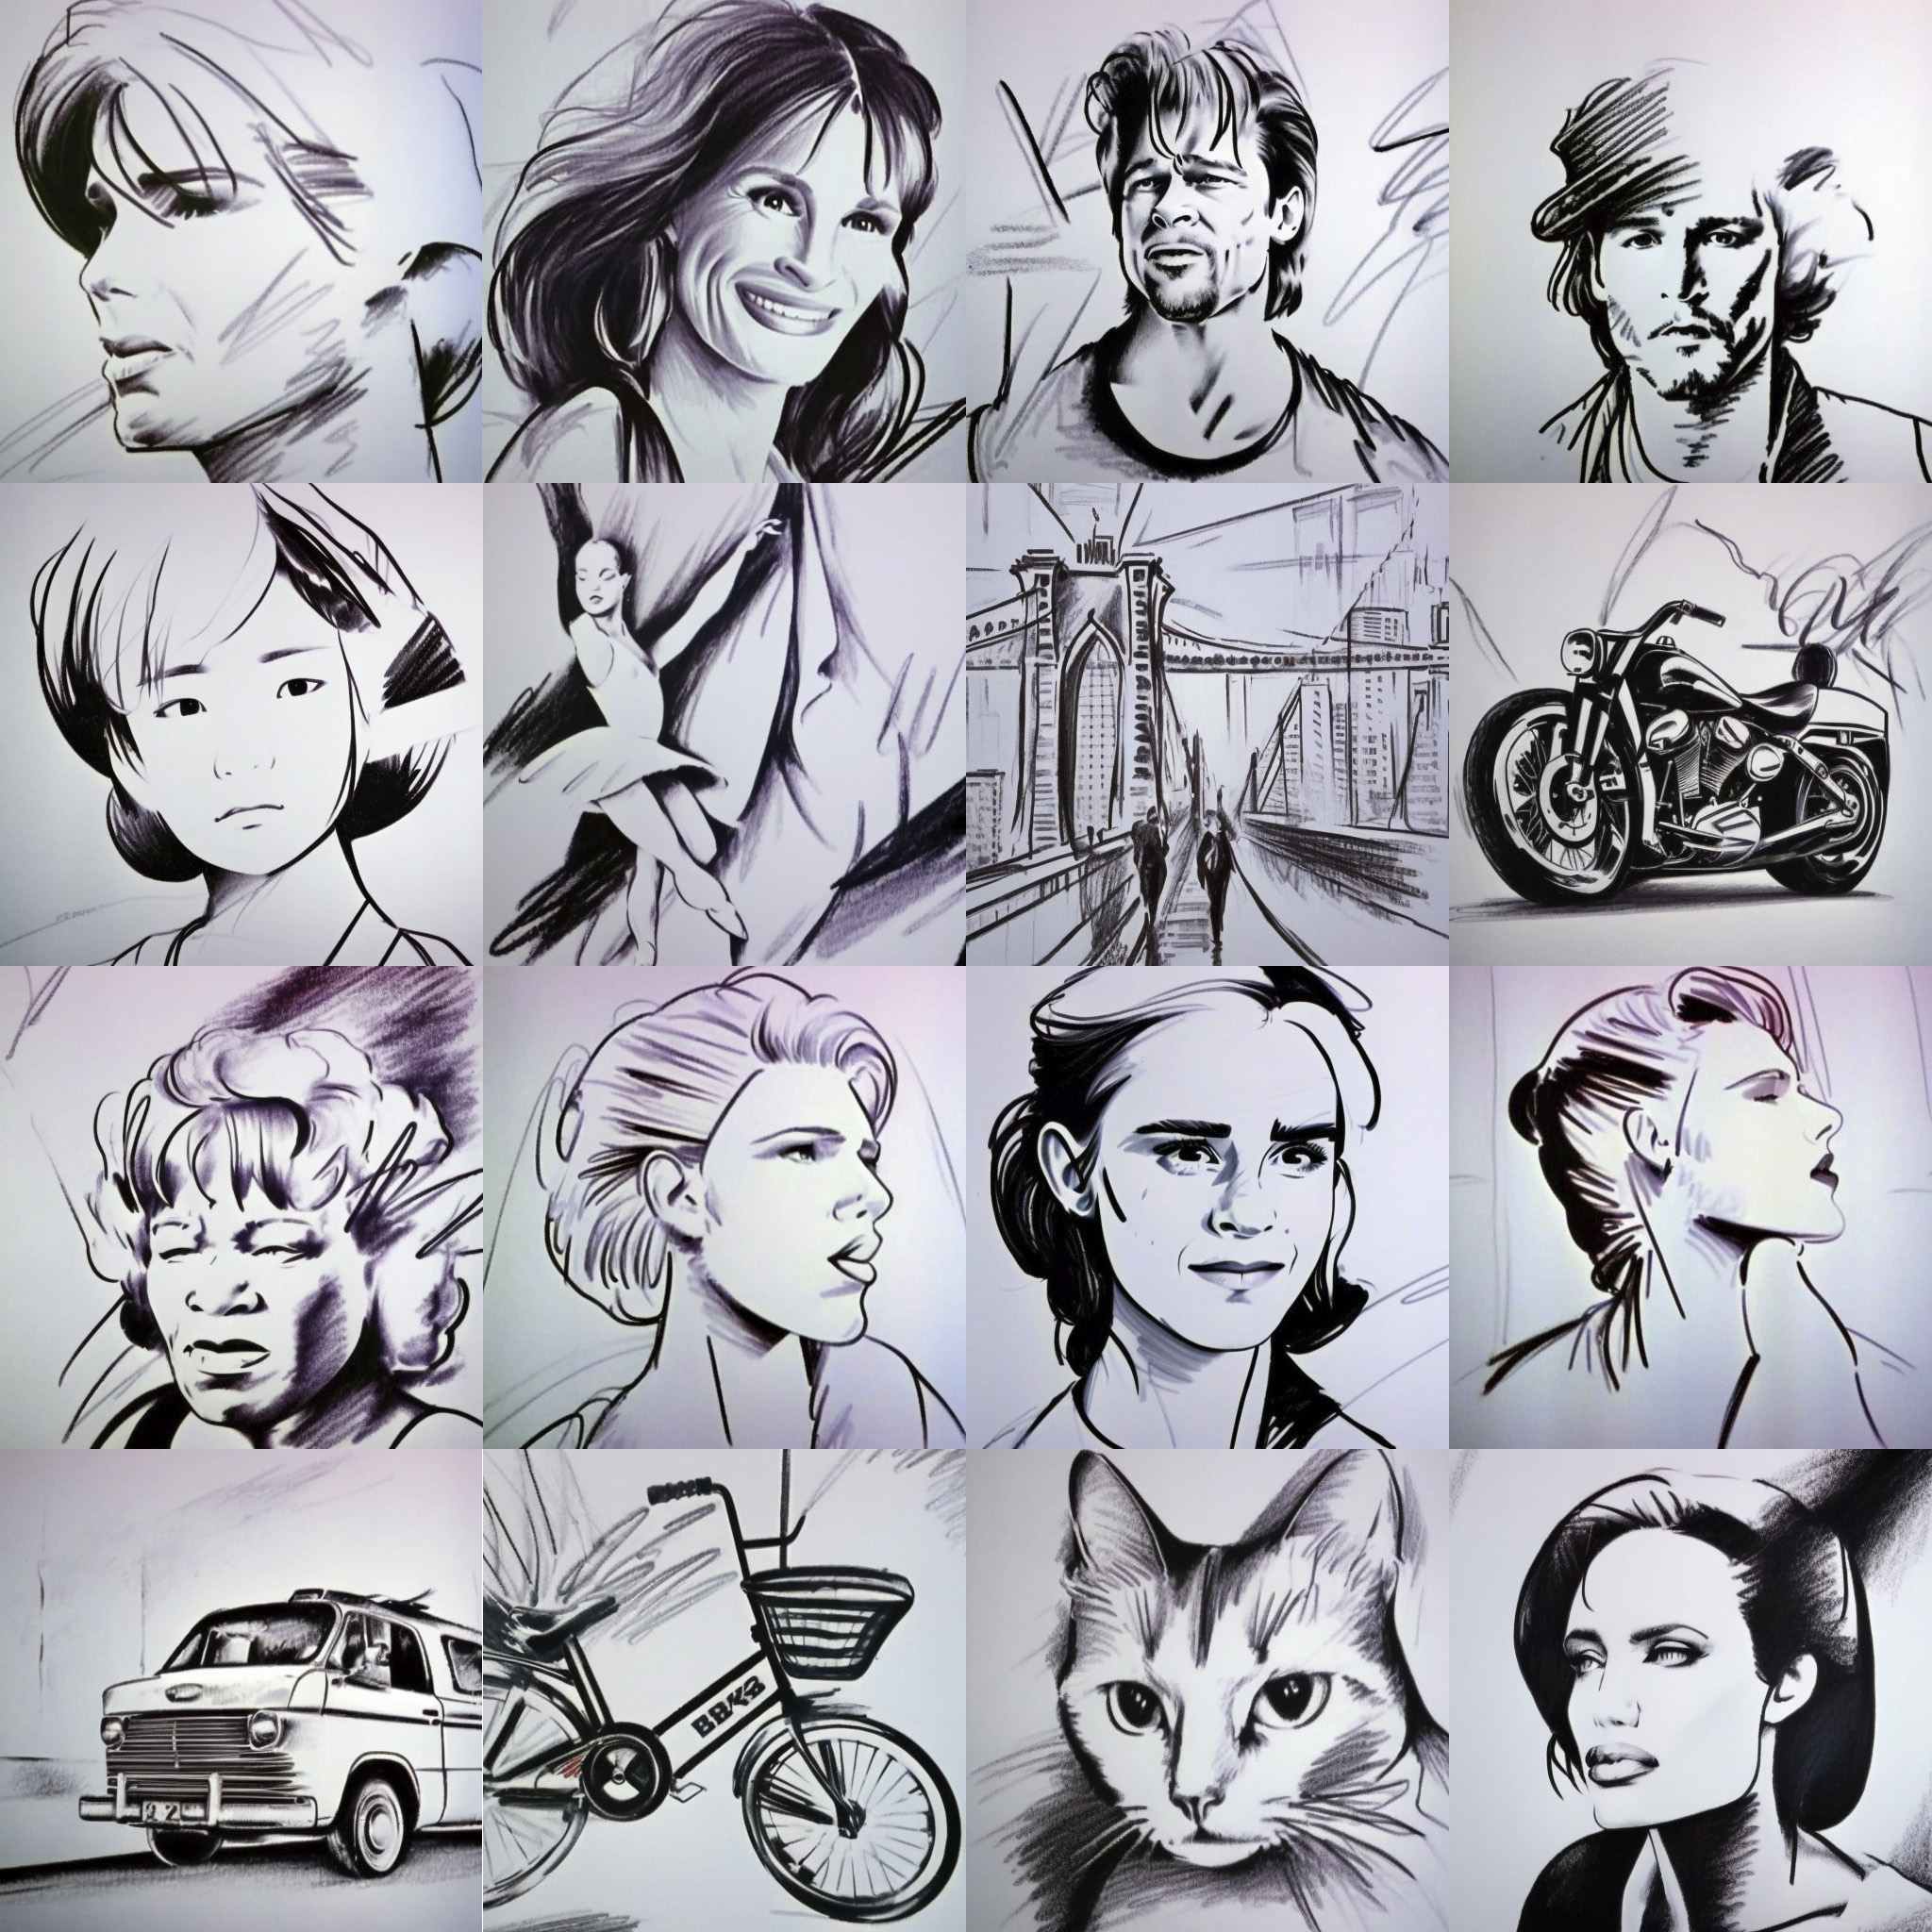
prompt and settings used: [person/scene] in takeON style | Steps: 25, Sampler: Euler, CFG scale: 7.5
--
Note: The model works better on characters than landscape/scenes
--
This model was trained with Dreambooth training by TheLastBen, using 64 images at 6400 steps with 25% of text encoder.
--
This model is open access and available to all, with a CreativeML OpenRAIL-M license further specifying rights and usage. The CreativeML OpenRAIL License specifies: