
Downloads · 30 days
0
0% of all-time downloads
thingthatis/sdxl-instructpix2pix-768
sdxl-instructpix2pix-768 is a text-to-image model from thingthatis. Use it when you need an image from a text prompt. It is set up for diffusers. The card lists the license as openrail++.
Instruction fine-tuning of Stable Diffusion XL (SDXL) à la InstructPix2Pix. Some results below:
Downloads · 30 days
0
0% of all-time downloads
All-time downloads
20
Public
Parameters
2.6B
12.2 GB on disk
Likes
0
Public
Click a slice to open those files.
.safetensors12.2 GB · 97%
From the Hugging Face model README
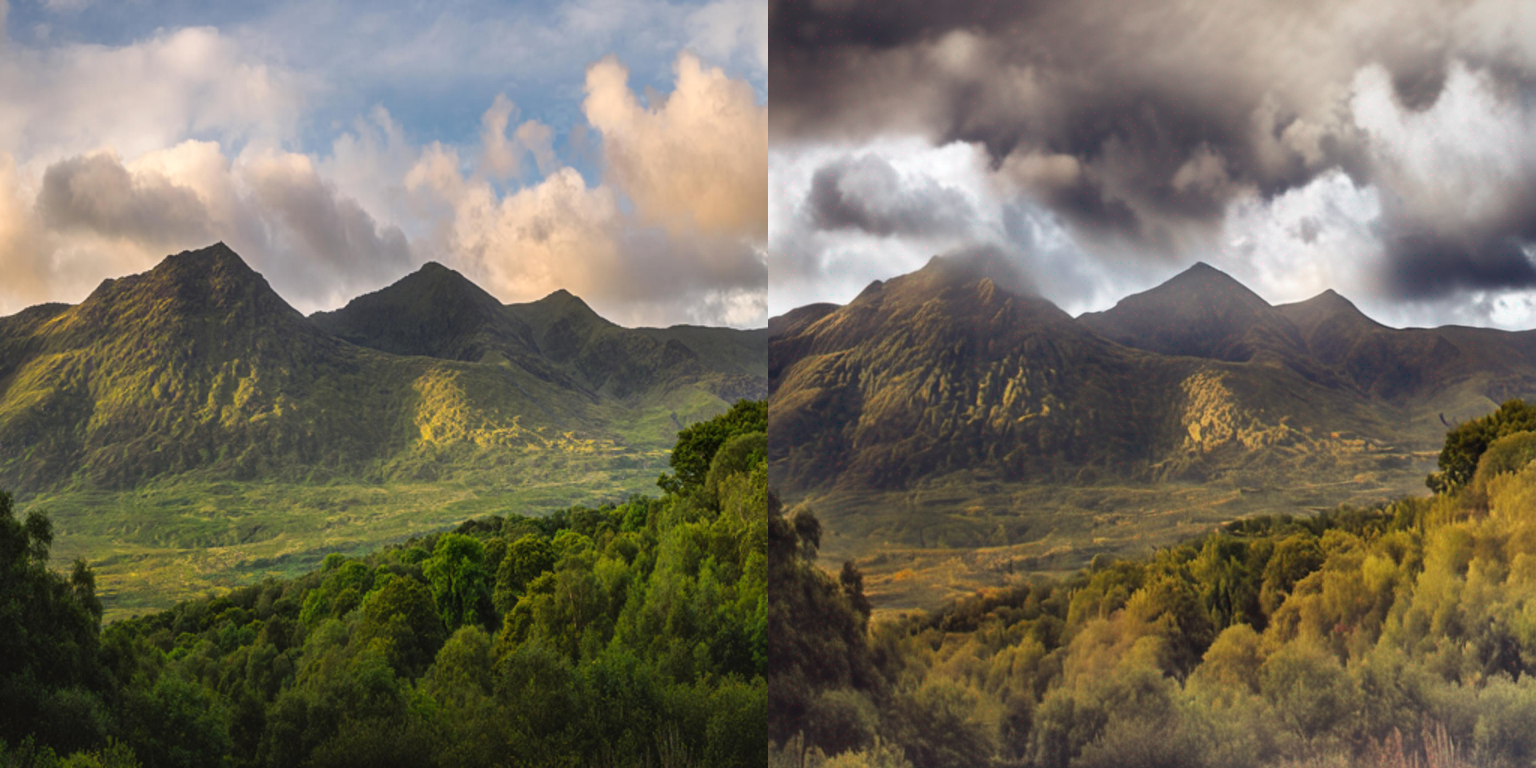
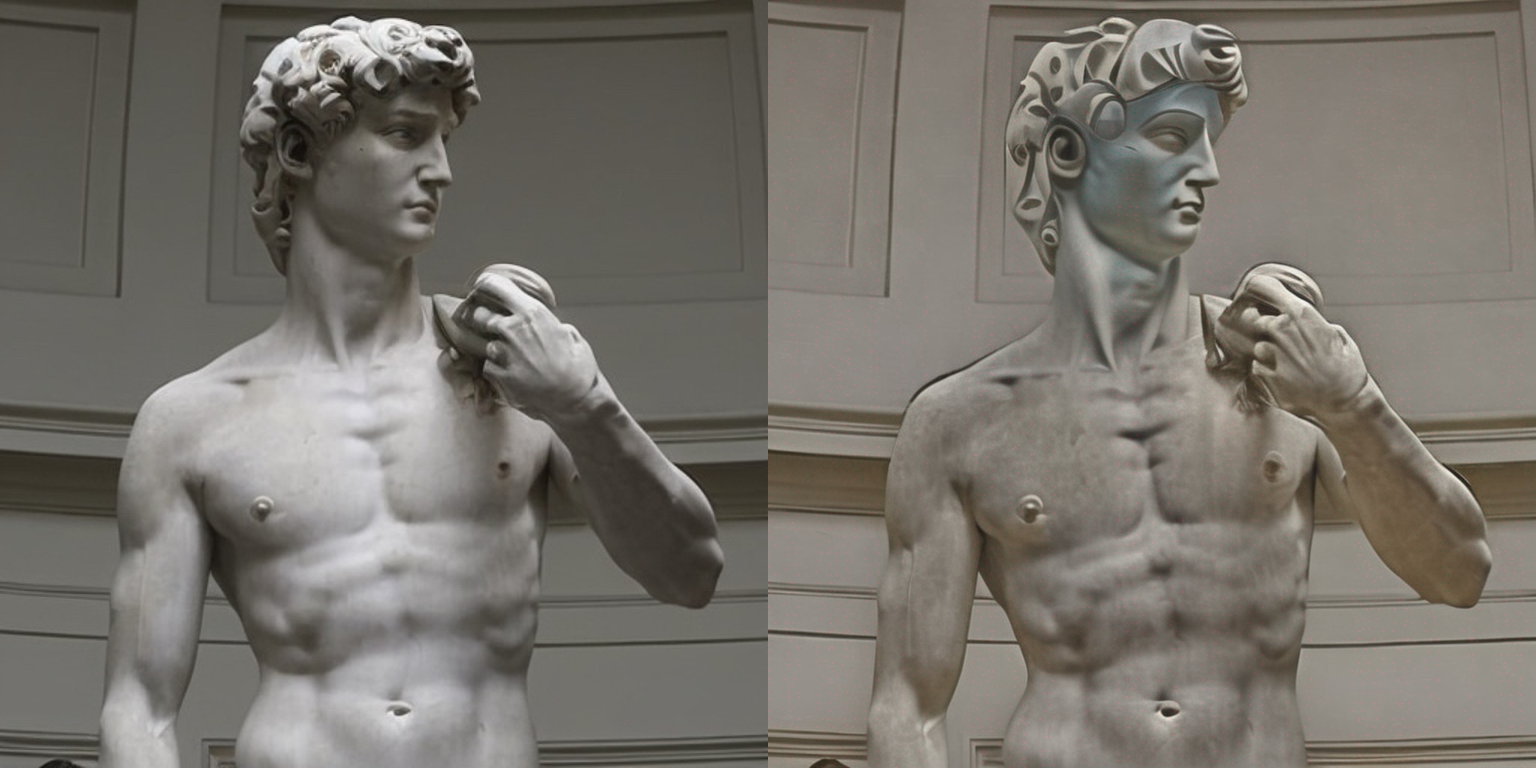
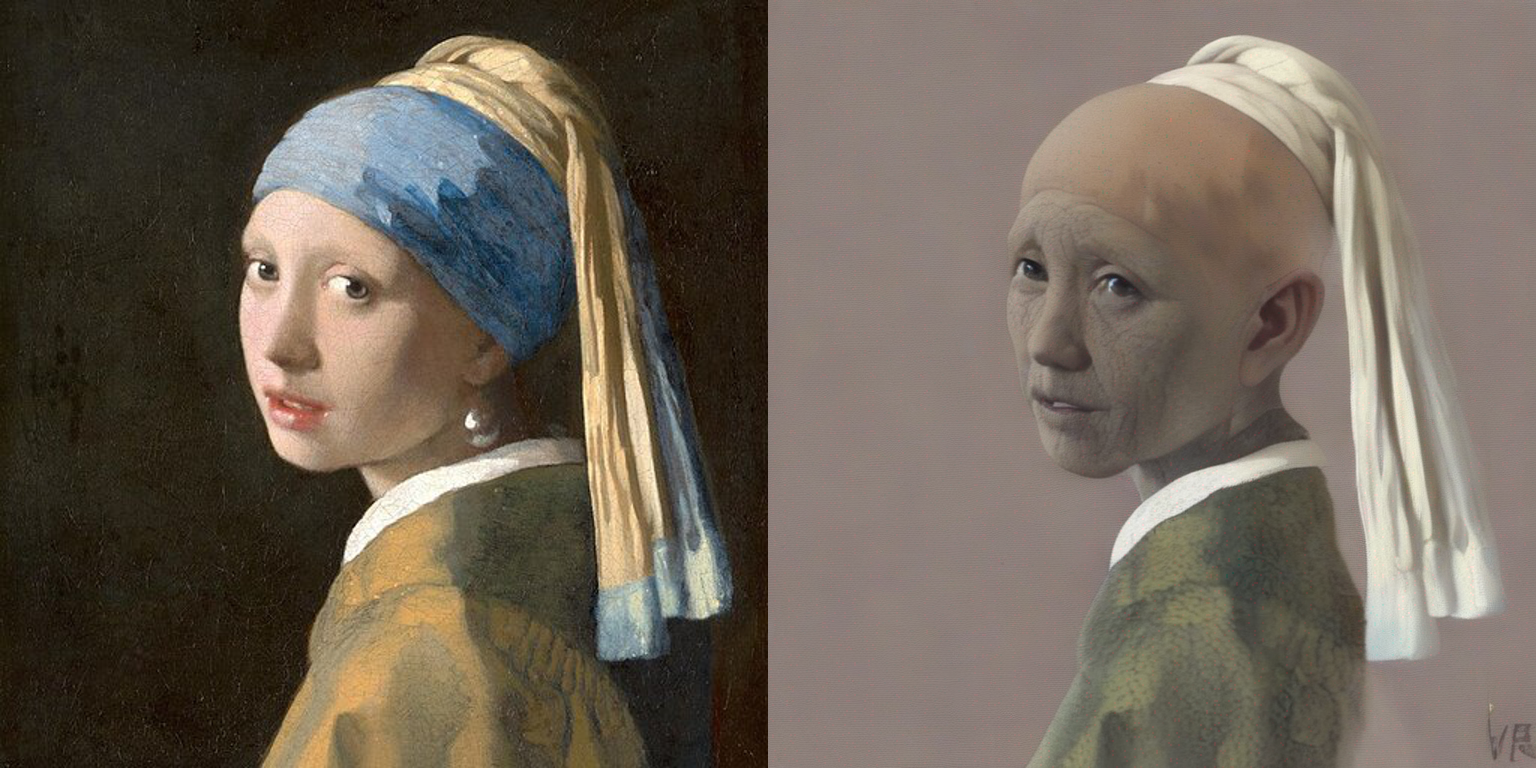
Instruction fine-tuning of Stable Diffusion XL (SDXL) à la InstructPix2Pix. Some results below:
Edit instruction: "Turn sky into a cloudy one"
Edit instruction: "Make it a picasso painting"
Edit instruction: "make the person older"
Make sure to install the libraries first:
pip install accelerate transformers
pip install git+https://github.com/huggingface/diffusers
import torch
from diffusers import StableDiffusionXLInstructPix2PixPipeline
from diffusers.utils import load_image

resolution = 768
image = load_image(
    "https://hf.co/datasets/diffusers/diffusers-images-docs/resolve/main/mountain.png"
).resize((resolution, resolution))
edit_instruction = "Turn sky into a cloudy one"

pipe = StableDiffusionXLInstructPix2PixPipeline.from_pretrained(
    "diffusers/sdxl-instructpix2pix-768", torch_dtype=torch.float16
).to("cuda")

edited_image = pipe(
    prompt=edit_instruction,
    image=image,
    height=resolution,
    width=resolution,
    guidance_scale=3.0,
    image_guidance_scale=1.5,
    num_inference_steps=30,
).images[0]
edited_image.save("edited_image.png")
To know more, refer to the documentation.
🚨 Note that this checkpoint is experimental in nature and there's a lot of room for improvements. Please use the "Discussions" tab of this repository to open issues and discuss. 🚨
We fine-tuned SDXL using the InstructPix2Pix training methodology for 15000 steps using a fixed learning rate of 5e-6 on an image resolution of 768x768.
Our training scripts and other utilities can be found here and they were built on top of our official training script.
Our training logs are available on Weights and Biases here. Refer to this link for details on all the hyperparameters.
We used this dataset: timbrooks/instructpix2pix-clip-filtered.
one 8xA100 machine
Data parallel with a single gpu batch size of 8 for a total batch size of 32.
FP16