
Downloads · 30 days
8.8K
5% of all-time downloads
tenyx/Llama3-TenyxChat-70B
Llama3-TenyxChat-70B is a text generation model from tenyx. Use it when you need the model to write or continue text. It is set up for transformers. The card lists the license as llama3.
Introducing Llama-3-TenyxChat-70B, part of our TenyxChat series trained to function as useful assistants through preference tuning, using Tenyx's advanced fine-tuning technology (VentureBeat article). Our model is tra…
Downloads · 30 days
8.8K
5% of all-time downloads
All-time downloads
192K
Public
Parameters
70.6B
141 GB on disk
Likes
64
Public
Click a slice to open those files.
.safetensors141 GB · 100%
From the Hugging Face model README
Introducing Llama-3-TenyxChat-70B, part of our TenyxChat series trained to function as useful assistants through preference tuning, using Tenyx's advanced fine-tuning technology (VentureBeat article). Our model is trained using the Direct Preference Optimization (DPO) framework on the open-source AI feedback dataset UltraFeedback.
We fine-tune Llama3-70B with our proprietary approach which shows an increase in MT-Bench*, without a drop in performance of the model on other benchmarks. Our approach aims to mitigate forgetting in LLMs in a computationally efficient manner, thereby enabling continual fine-tuning capabilities without altering the pre-trained output distribution. Llama-3-TenyxChat-70B was trained using eight A100s (80GB) for fifteen hours, with a training setup obtained from HuggingFaceH4 (GitHub).
*The MT-Bench evaluation we perform follows the latest eval upgrade as PR'd here. This PR upgrades the evaluation from GPT-4-0613 to GPT-4-preview-0125 (latest version) as well as corrects and improves the quality of the reference answers for a subset of questions. These changes are required to correct the erroneous rating during previous evaluation.
Model Developers Tenyx Research
Our model uses the same chat template as Llama3-70B.
import torch
from transformers import pipeline

pipe = pipeline("text-generation", model="tenyx/Llama3-TenyxChat-70B", torch_dtype=torch.bfloat16, device_map="auto")

messages = [
    {"role": "system", "content": "You are a friendly chatbot who always responds in the style of a pirate."},
    {"role": "user", "content": "Hi. I would like to make a hotel booking."},
]

prompt = pipe.tokenizer.apply_chat_template(messages, tokenize=False, add_generation_prompt=True)
outputs = pipe(prompt, max_new_tokens=512, do_sample=False)
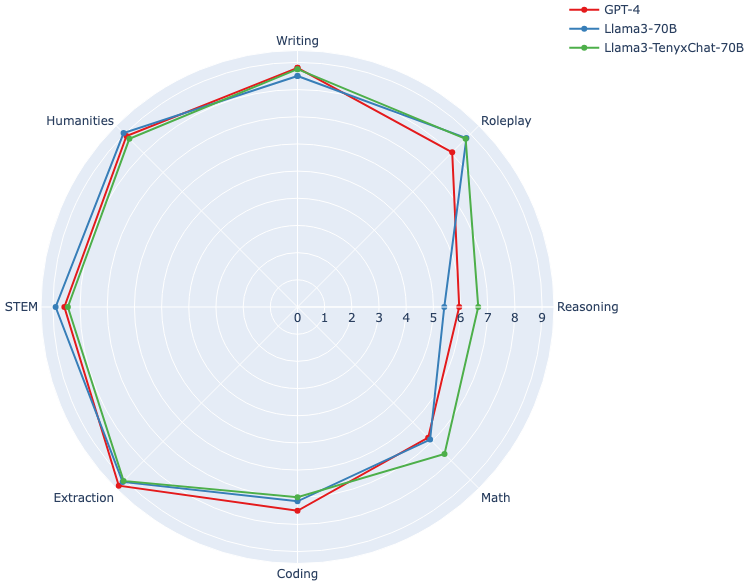
At the time of release (April 2024), Llama3-TenyxChat-70B is the highest-ranked open source model on the MT-Bench evaluation available for download.
MT-Bench is a benchmark made up of 80 high-quality multi-turn questions. These questions fall into eight categories: Writing, Roleplay, Reasoning, Math, Coding, Extraction, STEM, and Humanities. The chat models are rated using GPT-4-preview-0125 on a scale of 1 to 10, with higher values corresponding to better responses.
| Model-name | GPT4-preview-0125 MT Bench | Chat Arena Elo |
|---|---|---|
| GPT-4-1106 | 8.79 | 1251 |
| Claude 3 Opus (20240229) | 8.57 | 1247 |
| Llama3-TenyxChat-70B | 8.15 | NA |
| Llama3-70B-Instruct | 7.96 | 1207 |
| Claude 3 Sonnet (20240229) | 7.82 | 1190 |
| GPT-4-0314 | 7.96 | 1185 |
| Mixtral | 7.38 | 1114 |
| gpt-3.5-turbo-0613 | 7.37 | 1113 |
| Yi-34B | 6.46 | 1099 |
| gpt-3.5-turbo-0125 | 7.52 | 1096 |
| Llama 2 70B | 6.01 | 1082 |
| NV-Llama2-70B-SteerLM-Chat | 6.57 | 1076 |
Arena-Hard is an evaluation tool for instruction-tuned LLMs containing 500 challenging user queries. They prompt GPT-4-1106-preview as judge to compare the models' responses against a baseline model (default: GPT-4-0314).
| Model-name | Score | |
|---|---|---|
| gpt-4-0125-preview | 78.0 | 95% CI: (-1.8, 2.2) |
| claude-3-opus-20240229 | 60.4 | 95% CI: (-2.6, 2.1) |
| gpt-4-0314 | 50.0 | 95% CI: (0.0, 0.0) |
| tenyx/Llama3-TenyxChat-70B | 49.0 | 95% CI: (-3.0, 2.4) |
| meta-llama/Meta-Llama-3-70B-In | 47.3 | 95% CI: (-1.7, 2.6) |
| claude-3-sonnet-20240229 | 46.8 | 95% CI: (-2.7, 2.3) |
| claude-3-haiku-20240307 | 41.5 | 95% CI: (-2.4, 2.5) |
| gpt-4-0613 | 37.9 | 95% CI: (-2.1, 2.2) |
| mistral-large-2402 | 37.7 | 95% CI: (-2.9, 2.8) |
| Qwen1.5-72B-Chat | 36.1 | 95% CI: (-2.1, 2.4) |
| command-r-plus | 33.1 | 95% CI: (-2.0, 1.9) |
We now present our results on the Eleuther AI Language Model Evaluation Harness used for benchmarking Open LLM Leaderboard on Hugging Face.
The task involves evaluation on 6 key benchmarks across reasoning and knowledge with different few-shot settings. Read more details about the benchmark at the leaderboard page.
| Model-name | Average | ARC | HellaSwag | MMLU | TruthfulQA | Winogrande | GSM8K |
|---|---|---|---|---|---|---|---|
| Llama3-TenyxChat-70B | 79.43 | 72.53 | 86.11 | 79.95 | 62.93 | 83.82 | 91.21 |
| Llama3-70B-Instruct | 77.88 | 71.42 | 85.69 | 80.06 | 61.81 | 82.87 | 85.44 |
*The results reported are from local evaluation of our model. tenyx/Llama3-TenyxChat-70B is submitted and will be reflected in the leaderboard once evaluation succeeds.
Note: While the Open LLM Leaderboard shows other performant Llama-3 fine-tuned models, we observe that these models typically regress in performance and struggle in a multi-turn chat setting, such as the MT-Bench. We present the below comparison with a Llama3 finetune from the leaderboard.
| Model | First Turn | Second Turn | Average |
|---|---|---|---|
| tenyx/Llama3-TenyxChat-70B | 8.12 | 8.18 | 8.15 |
| meta-llama/Llama3-TenyxChat-70B | 8.05 | 7.87 | 7.96 |
| MaziyarPanahi/Llama-3-70B-Instruct-DPO-v0.4 | 8.05 | 7.82 | 7.93 |
Llama3-TenyxChat-70B, like other language models, has its own set of limitations. We haven’t fine-tuned the model explicitly to align with human safety preferences. Therefore, it is capable of producing undesirable outputs, particularly when adversarially prompted. From our observation, the model still tends to struggle with tasks that involve reasoning and math questions. In some instances, it might generate verbose or extraneous content.
Llama3-TenyxChat-70B is distributed under the Meta Llama 3 Community License.
If you use Llama3-TenyxChat-70B for your research, cite us as
@misc{tenyxchat2024,
      title={TenyxChat: Language Model Alignment using Tenyx Fine-tuning},
      author={Tenyx},
      year={2024},
}