
Downloads · 30 days
13
3% of all-time downloads
tensorhydra/qwen3-8b-aimo3-tir
qwen3-8b-aimo3-tir is a text generation model from tensorhydra. Use it when you need the model to write or continue text. It is set up for transformers. The card lists the license as other.
A LoRA fine-tuned version of Qwen-8B trained for tool-integrated reasoning on the AIMO3 competition dataset (generated by GPT-OSS-120B). The LoRA adapters have been merged into the base model and saved in SafeTensors…
Downloads · 30 days
13
3% of all-time downloads
All-time downloads
513
Public
Parameters
8.2B
16.4 GB on disk
Likes
0
Public
Click a slice to open those files.
.safetensors16.4 GB · 100%
From the Hugging Face model README
A LoRA fine-tuned version of Qwen-8B trained for tool-integrated reasoning on the AIMO3 competition dataset (generated by GPT-OSS-120B). The LoRA adapters have been merged into the base model and saved in SafeTensors format for straightforward deployment.
| Property | Details |
|---|---|
| Base Model | Qwen-8B |
| Fine-tuning Method | LoRA (merged) |
| Format | SafeTensors (BF16) |
| Parameters | ~8B |
| Disk Size | ~16GB |
| Max Context | 8192 tokens |
| Hyperparameter | Value |
|---|---|
| Rank (r) | 16 |
| Alpha | 32 |
| Dropout | 0.05 |
| Bias | none |
| Target Modules | q_proj, k_proj, v_proj, o_proj, gate_proj, up_proj, down_proj |
| Hyperparameter | Value |
|---|---|
| Precision | BFloat16 (no quantization) |
| Epochs | 2 |
| Steps | 8750 (~1 epoch) |
| Per-device Batch Size | 2 |
| Gradient Accumulation Steps | 8 (effective batch: 16) |
| Learning Rate | 2e-4 |
| LR Scheduler | Cosine with warmup |
| Warmup Ratio | 0.03 |
| Weight Decay | 0.01 |
| Max Gradient Norm | 1.0 |
| Max Sequence Length | 8192 |
| Optimizer | AdamW (Fused) |
Supported column names:
problem, question, input, promptsolution, answer, output, response, completionTraining uses a ChatML-style format:
<|im_start|>user
{prompt}<|im_end|>
<|im_start|>assistant
{response}<|im_end|>
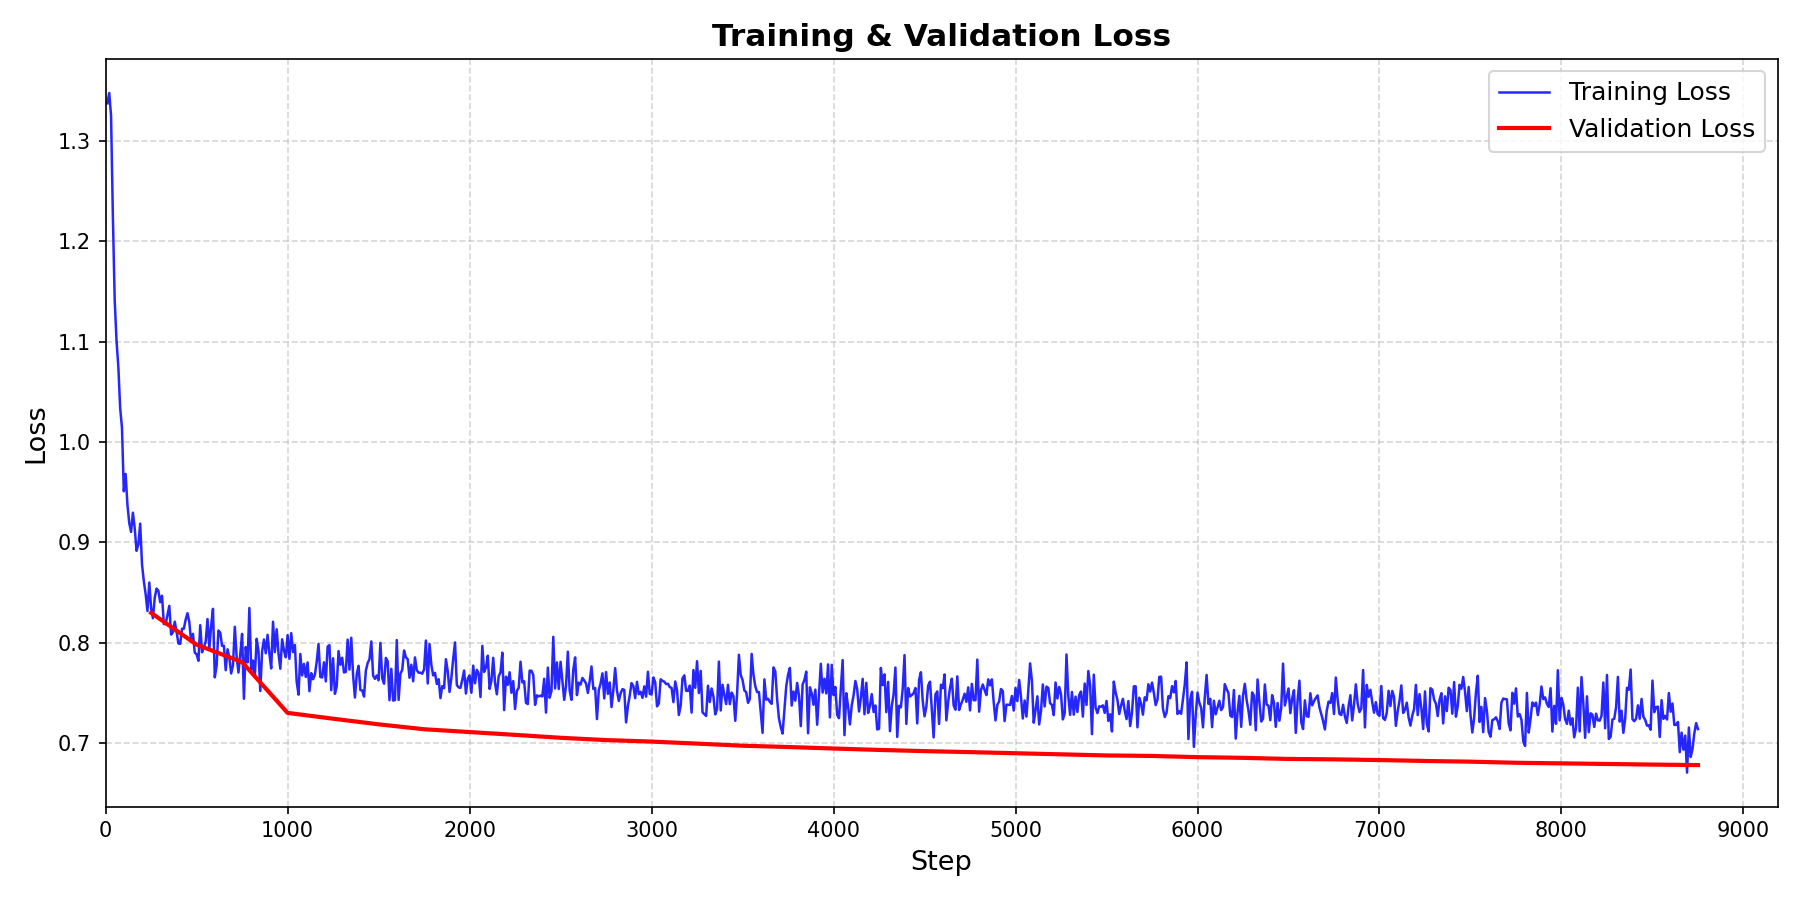
The model is trained for 8750 steps (~ 1 epoch) before stopping. Below are the train and validation loss curves for the entire training session.
Since the LoRA adapters are already merged, PEFT is not required:
from transformers import AutoModelForCausalLM, AutoTokenizer
import torch

model = AutoModelForCausalLM.from_pretrained(
    "tensorhydra/qwen-8b-aimo3-reasoning",
    trust_remote_code=True,
    torch_dtype=torch.bfloat16,
    device_map="auto"
)

tokenizer = AutoTokenizer.from_pretrained(
    "tensorhydra/qwen-8b-aimo3-reasoning",
    trust_remote_code=True
)
prompt = "Solve this problem: What is 2 + 2?"

formatted_prompt = f"user\n{prompt}\nassistant\n"

inputs = tokenizer(formatted_prompt, return_tensors="pt").to(model.device)
outputs = model.generate(
    **inputs,
    max_new_tokens=512,
    temperature=0.7,
    top_p=0.9,
    do_sample=True
)

response = tokenizer.decode(outputs[0], skip_special_tokens=False)
print(response)
prompts = [
    "Solve: 15 + 27 = ?",
    "What is the derivative of x^2?",
    "Calculate the area of a circle with radius 5"
]

formatted_prompts = [
    f"user\n{p}\nassistant\n"
    for p in prompts
]

inputs = tokenizer(formatted_prompts, return_tensors="pt", padding=True).to(model.device)
outputs = model.generate(**inputs, max_new_tokens=512, temperature=0.7, do_sample=True)

for response in tokenizer.batch_decode(outputs, skip_special_tokens=False):
    print(response)
    print("-" * 80)
# 8-bit (~8GB VRAM)
model = AutoModelForCausalLM.from_pretrained(
    "tensorhydra/qwen-8b-aimo3-reasoning",
    load_in_8bit=True,
    device_map="auto"
)

# 4-bit (~4GB VRAM)
model = AutoModelForCausalLM.from_pretrained(
    "tensorhydra/qwen-8b-aimo3-reasoning",
    load_in_4bit=True,
    device_map="auto"
)
| Mode | VRAM |
|---|---|
| BF16 (full) | ~16GB |
| 8-bit quantized | ~8GB |
| 4-bit quantized | ~4GB |
model/
├── config.json
├── generation_config.json
├── model.safetensors.index.json
├── model-00001-of-0000X.safetensors
├── ...
├── tokenizer_config.json
├── tokenizer.json
└── special_tokens_map.json
@misc{qwen-lora-aimo3,
  title   = {Qwen-8B LoRA Fine-tuned for Tool-Integrated Reasoning},
  author  = {tensorhydra},
  year    = {2025},
  howpublished = {Kaggle Model Hub},
  note    = {Merged LoRA model in SafeTensors format}
}
This model inherits the license of the base Qwen-8B model. Please refer to the Qwen license terms before use.