
Downloads · 30 days
105
15% of all-time downloads
team-data-ktzh/span-marker-ktzh-stazh
span-marker-ktzh-stazh is a token classification model from team-data-ktzh. Use it when you need labels on individual words, such as names. It is set up for span-marker. The card lists the license as mit.
This is a SpanMarker model that is based on the GELECTRA Large variant of the SpanMarker for GermEval 2014 NER and further fine-tuned on meeting notes from the cantonal council, resolutions of the governing council an…
Downloads · 30 days
105
15% of all-time downloads
All-time downloads
696
Public
Parameters
335M
1.3 GB on disk
Likes
0
Public
Click a slice to open those files.
.safetensors1.3 GB · 100%
From the Hugging Face model README
This is a SpanMarker model that is based on the GELECTRA Large variant of the SpanMarker for GermEval 2014 NER and further fine-tuned on meeting notes from the cantonal council, resolutions of the governing council and law text from the corpus juris of the Canton of Zurich. The documents span the 19th and 20th century, covering both historical language with varying degrees of standardization and contemporary language. Distinguished are PERson, LOCation, ORGanisation, as well as derivations of Named Entities (tag suffix -deriv).
The ORGanisation class has been extended to encompass institutions that have been deemed to be reasonably unambiguous in isolation or by virtue of their usage in the training data. Purely abstract/prototypical uses of institutions are generally out of scope (the model does not perform concept classification), can however occasionally arise.
The fine-tuned model can be used like:
from span_marker import SpanMarkerModel

# Download from the 🤗 Hub
model = SpanMarkerModel.from_pretrained("team-data-ktzh/span-marker-ktzh-stazh")

# Run inference
entities = model.predict("Hans Meier aus Dielsdorf vertritt im Kantonsrat die FDP.")
| Label | Examples |
|---|---|
| PER | Hans Müller |
| LOC | Zürich |
| ORG | SBB, Swissair, Kantonsrat, Bundesgericht |
| PERderiv | Müllersche |
| LOCderiv | zürcherische |
| ORGderiv | bundesgerichtlicher |
Evaluation relies on SpanMarker's internal evaluation code, which is based on seqeval.
| Label | P | R | F1 |
|---|---|---|---|
| PER | 0.97 | 0.97 | 0.97 |
| LOC | 0.95 | 0.96 | 0.96 |
| ORG | 0.92 | 0.95 | 0.93 |
| PERderiv | 0.40 | 0.30 | 0.33 |
| LOCderiv | 0.86 | 0.85 | 0.85 |
| ORGderiv | 0.73 | 0.76 | 0.74 |
| Fold | Precision | Recall | F1 | Accuracy |
|---|---|---|---|---|
| 0 | 0.927 | 0.952 | 0.939 | 0.992 |
| 1 | 0.942 | 0.957 | 0.949 | 0.993 |
| 2 | 0.938 | 0.946 | 0.942 | 0.992 |
| 3 | 0.921 | 0.951 | 0.936 | 0.992 |
| 4 | 0.945 | 0.949 | 0.947 | 0.993 |
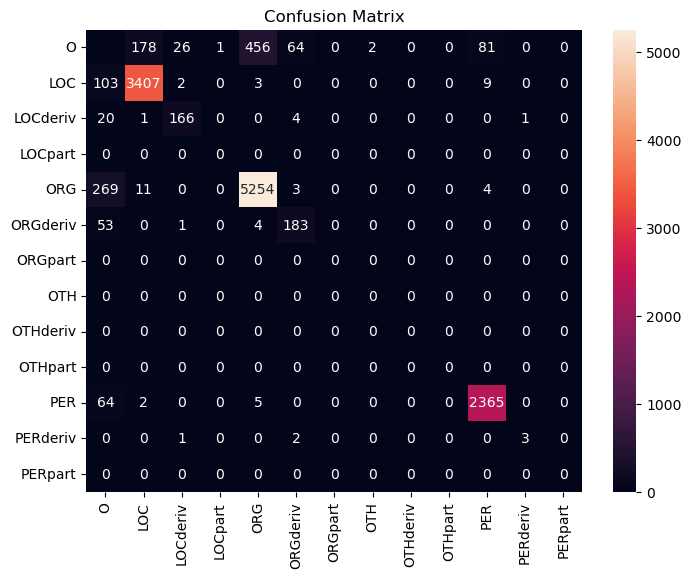
(Note that the confusion matrix also lists other labels from the GermEval 2014 dataset which are ignored in the context of this model.)
Please note that this is released strictly as a task-bound model for the purpose of annotating historical and future documents from the collections it was trained on, as well as the official gazette of the Canton of Zurich. No claims of generalization are made outside of the specific use case it was developed for. The training data was annotated according to a specific but informal annotation scheme and the bias of the original model has been retained where it was found not to interfere with the use case. Be mindful of idiosyncrasies when applying to other documents.
The original XML documents of the training set can be found here. The annotations may be freely modified to tailor the model to an alternative use case. Note that a modified TEI Publisher and this Jupyter notebook are required to generate a Huggingface Dataset.
The training data was sampled from the following collections from the data catalog of the Canton of Zurich, curated by the Staatsarchiv des Kantons Zürich (state archives of the Canton of Zurich):
This work builds upon:
@software{Aarsen_SpanMarker,
    author = {Aarsen, Tom},
    license = {Apache-2.0},
    title = {{SpanMarker for Named Entity Recognition}},
    url = {https://github.com/tomaarsen/SpanMarkerNER}
}

@article{aarsenspanmarker,
  title={SpanMarker for Named Entity Recognition},
  author={Aarsen, Tom and del Prado Martin, Fermin Moscoso and Suero, Daniel Vila and Oosterhuis, Harrie}
}

@inproceedings{ye-etal-2022-packed,
    title = "Packed Levitated Marker for Entity and Relation Extraction",
    author = "Ye, Deming  and
      Lin, Yankai  and
      Li, Peng  and
      Sun, Maosong",
    editor = "Muresan, Smaranda  and
      Nakov, Preslav  and
      Villavicencio, Aline",
    booktitle = "Proceedings of the 60th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers)",
    month = may,
    year = "2022",
    address = "Dublin, Ireland",
    publisher = "Association for Computational Linguistics",
    url = "https://aclanthology.org/2022.acl-long.337",
    doi = "10.18653/v1/2022.acl-long.337",
    pages = "4904--4917"}",
}

@misc{chan2020germans,
  author = {Chan, Branden and Schweter, Stefan and Möller, Timo},
  description = {German's Next Language Model},
  keywords = {bert gbert languagemodel lm},
  title = {German's Next Language Model},
  url = {http://arxiv.org/abs/2010.10906},
  year = 2020
}

@inproceedings{benikova-etal-2014-nosta,
    title = {NoSta-D Named Entity Annotation for German: Guidelines and Dataset},
    author = {Benikova, Darina  and
      Biemann, Chris  and
      Reznicek, Marc},
    booktitle = {Proceedings of the Ninth International Conference on Language Resources and Evaluation ({LREC}'14)},
    month = {may},
    year = {2014},
    address = {Reykjavik, Iceland},
    publisher = {European Language Resources Association (ELRA)},
    url = {http://www.lrec-conf.org/proceedings/lrec2014/pdf/276_Paper.pdf},
    pages = {2524--2531},
}