
Downloads · 30 days
48
0% of all-time downloads
showlab/show-1-base
show-1-base is a text-to-video model from showlab. Use it when you need video from a text prompt. It is set up for diffusers. The card lists the license as cc-by-nc-4.0.
Pixel-based VDMs can generate motion accurately aligned with the textual prompt but typically demand expensive computational costs in terms of time and GPU memory, especially when generating high-resolution videos. La…
Downloads · 30 days
48
0% of all-time downloads
All-time downloads
16.3K
Public
Repo size
45 GB
Likes
15
Public
Click a slice to open those files.
.bin22.5 GB · 100%
From the Hugging Face model README
Pixel-based VDMs can generate motion accurately aligned with the textual prompt but typically demand expensive computational costs in terms of time and GPU memory, especially when generating high-resolution videos. Latent-based VDMs are more resource-efficient because they work in a reduced-dimension latent space. But it is challenging for such small latent space (e.g., 64×40 for 256×160 videos) to cover rich yet necessary visual semantic details as described by the textual prompt.
To marry the strength and alleviate the weakness of pixel-based and latent-based VDMs, we introduce Show-1, an efficient text-to-video model that generates videos of not only decent video-text alignment but also high visual quality.
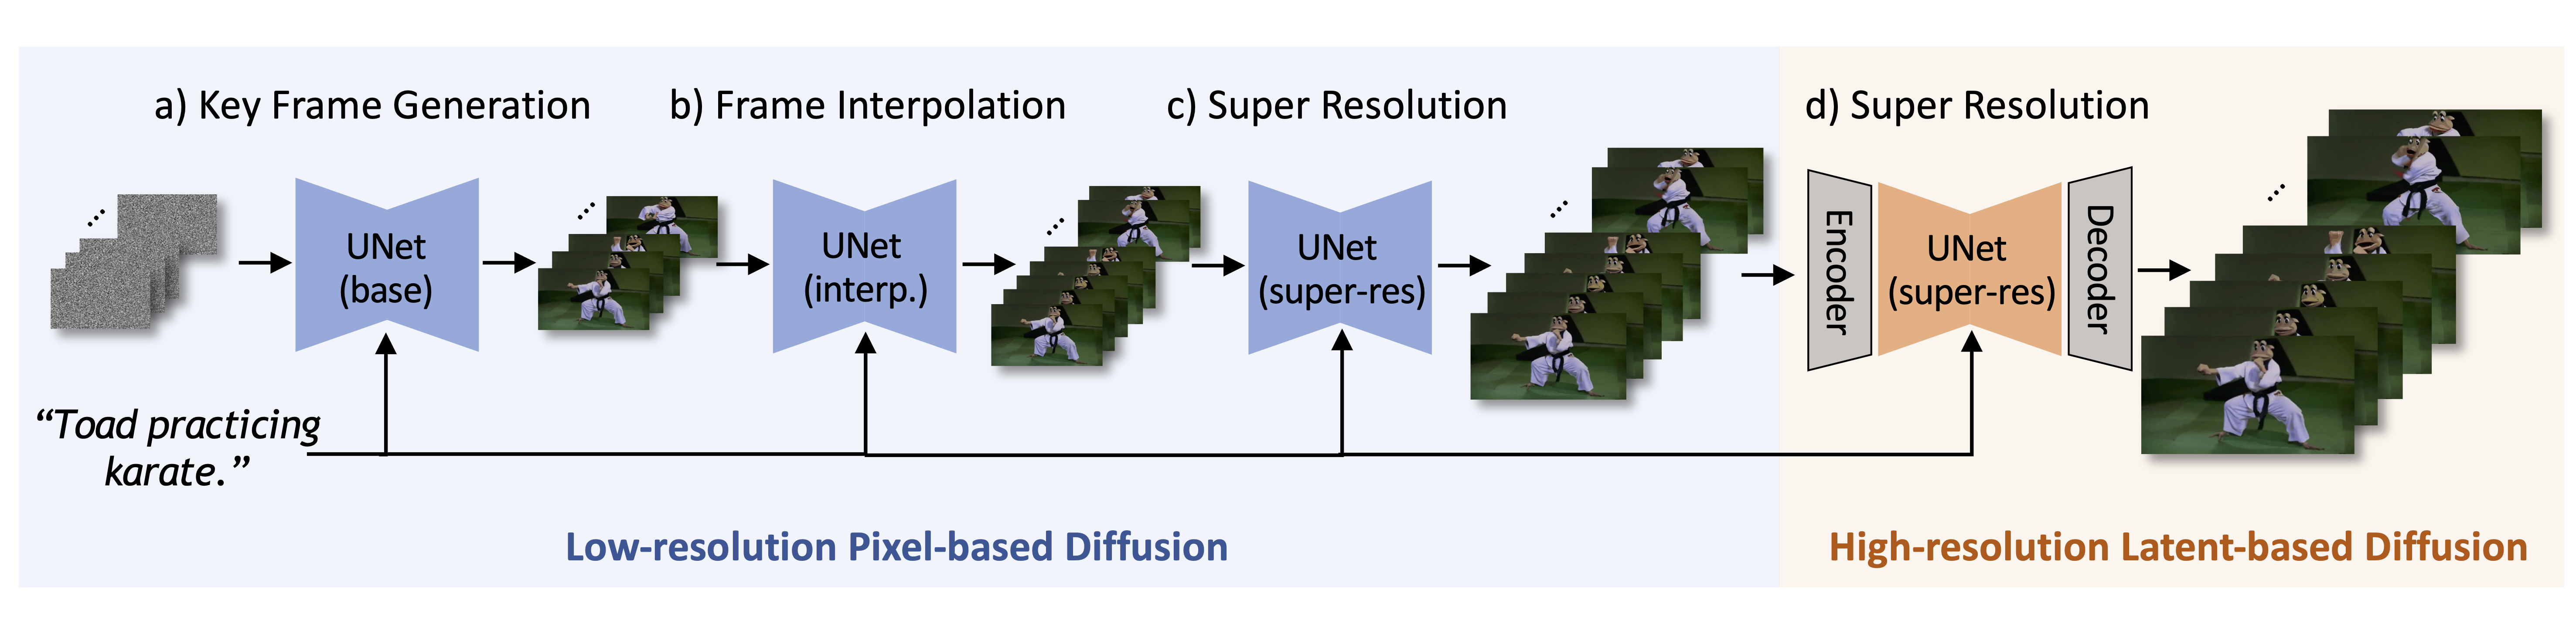
This is the base model of Show-1 that generates videos with 8 keyframes at a resolution of 64x40. The model is finetuned from DeepFloyd/IF-I-L-v1.0 on the WebVid-10M and InternVid dataset.
Clone the GitHub repository and install the requirements:
git clone https://github.com/showlab/Show-1.git
pip install -r requirements.txt
Run the following command to generate a video from a text prompt. By default, this will automatically download all the model weights from huggingface.
python run_inference.py
You can also download the weights manually and change the pretrained_model_path in run_inference.py to run the inference.
git lfs install

# base
git clone https://huggingface.co/showlab/show-1-base
# interp
git clone https://huggingface.co/showlab/show-1-interpolation
# sr1
git clone https://huggingface.co/showlab/show-1-sr1
# sr2
git clone https://huggingface.co/showlab/show-1-sr2
If you make use of our work, please cite our paper.
@misc{zhang2023show1,
    title={Show-1: Marrying Pixel and Latent Diffusion Models for Text-to-Video Generation},
    author={David Junhao Zhang and Jay Zhangjie Wu and Jia-Wei Liu and Rui Zhao and Lingmin Ran and Yuchao Gu and Difei Gao and Mike Zheng Shou},
    year={2023},
    eprint={2309.15818},
    archivePrefix={arXiv},
    primaryClass={cs.CV}
}
This model card is maintained by David Junhao Zhang and Jay Zhangjie Wu. For any questions, please feel free to contact us or open an issue in the repository.