
Downloads · 30 days
56
1% of all-time downloads
serdarakyol/interpress-turkish-news-classification
interpress-turkish-news-classification is a text classification model from serdarakyol. Use it when you need a label for a piece of text. It is set up for transformers.
The dataset downloaded from interpress. This dataset is real world data. Actually there are 273K data but I filtered them and used 108K data for this model. For more information about dataset please visit this link
Downloads · 30 days
56
1% of all-time downloads
All-time downloads
9.5K
Public
Repo size
1.8 GB
Likes
12
Public
Click a slice to open those files.
.h5443 MB · 33%
From the Hugging Face model README
The dataset downloaded from interpress. This dataset is real world data. Actually there are 273K data but I filtered them and used 108K data for this model. For more information about dataset please visit this link
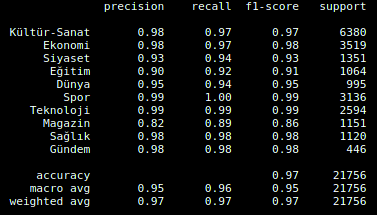
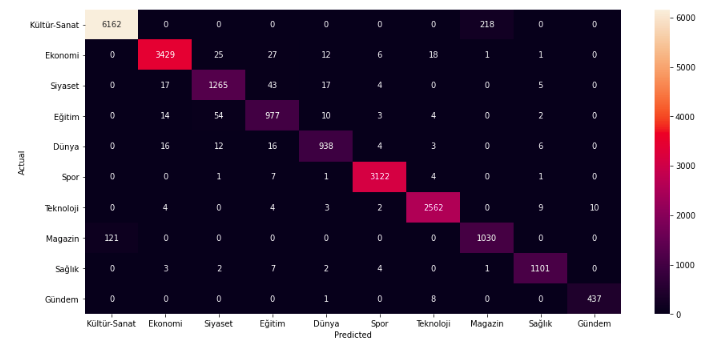
Model accuracy on train data and validation data is %97. The data split as %80 train and %20 validation. The results as shown as below
pip install transformers or pip install transformers==4.3.3
from transformers import AutoTokenizer, AutoModelForSequenceClassification

tokenizer = AutoTokenizer.from_pretrained("serdarakyol/interpress-turkish-news-classification")
model = AutoModelForSequenceClassification.from_pretrained("serdarakyol/interpress-turkish-news-classification")
import torch

if torch.cuda.is_available():
    device = torch.device("cuda")
    model = model.cuda()
    print('There are %d GPU(s) available.' % torch.cuda.device_count())
    print('GPU name is:', torch.cuda.get_device_name(0))
else:
    print('No GPU available, using the CPU instead.')
    device = torch.device("cpu")
import numpy as np

def prediction(news):
    news=[news]
    indices=tokenizer.batch_encode_plus(
    news,
    max_length=512,
    add_special_tokens=True,
    return_attention_mask=True,
    padding='max_length',
    truncation=True,
    return_tensors='pt')

    inputs = indices["input_ids"].clone().detach().to(device)
    masks = indices["attention_mask"].clone().detach().to(device)

    with torch.no_grad():
        output = model(inputs, token_type_ids=None,attention_mask=masks)

    logits = output[0]
    logits = logits.detach().cpu().numpy()
    pred = np.argmax(logits,axis=1)[0]
    return pred
news = r"ABD'den Prens Selman'a yaptırım yok Beyaz Saray Sözcüsü Psaki, Muhammed bin Selman'a yaptırım uygulamamanın \"doğru karar\" olduğunu savundu. Psaki, \"Tarihimizde, Demokrat ve Cumhuriyetçi başkanların yönetimlerinde diplomatik ilişki içinde olduğumuz ülkelerin liderlerine yönelik yaptırım getirilmemiştir\" dedi."
You can find the news in this link (news date: 02/03/2021)
labels = {
    0 : "Culture-Art",
    1 : "Economy",
    2 : "Politics",
    3 : "Education",
    4 : "World",
    5 : "Sport",
    6 : "Technology",
    7 : "Magazine",
    8 : "Health",
    9 : "Agenda"
}
pred = prediction(news)
print(labels[pred])
# > World
pip install transformers or pip install transformers==4.3.3

import tensorflow as tf
from transformers import BertTokenizer, TFBertForSequenceClassification
import numpy as np

tokenizer = BertTokenizer.from_pretrained('serdarakyol/interpress-turkish-news-classification')
model = TFBertForSequenceClassification.from_pretrained("serdarakyol/interpress-turkish-news-classification")

inputs = tokenizer(news, return_tensors="tf")
inputs["labels"] = tf.reshape(tf.constant(1), (-1, 1)) # Batch size 1

outputs = model(inputs)
loss = outputs.loss
logits = outputs.logits
pred = np.argmax(logits,axis=1)[0]
labels[pred]
# > World
Thanks to @yavuzkomecoglu for contributes
If you have any question, please, don't hesitate to contact with me

