
Downloads · 30 days
166
0% of all-time downloads
philschmid/flan-t5-xxl-sharded-fp16
flan-t5-xxl-sharded-fp16 is a machine learning model from philschmid. Use it for the machine learning task on the model card, and read the license before you ship it in a product. It is set up for transformers. The card lists the license as apache-2.0.
This is a fork of google/flan-t5-xxl implementing a custom handler.py as an example for how to use t5-11b with inference-endpoints on a single NVIDIA A10G.
Downloads · 30 days
166
0% of all-time downloads
All-time downloads
346K
Public
Repo size
45.1 GB
Likes
56
Public
Click a slice to open those files.
.bin22.5 GB · 100%
From the Hugging Face model README
This is a fork of google/flan-t5-xxl implementing a custom
handler.pyas an example for how to use t5-11b with inference-endpoints on a single NVIDIA A10G.
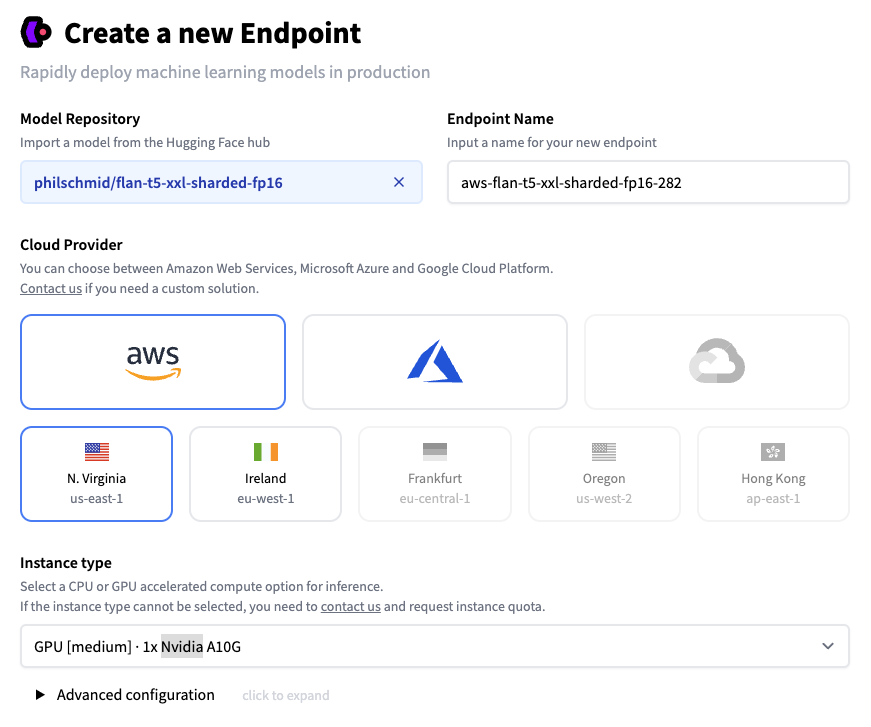
You can deploy the flan-t5-xxl with a 1-click. Since we are using the "quantized" version, we can switch our instance type to "GPU [medium] · 1x Nvidia A10G".
If you already know T5, FLAN-T5 is just better at everything. For the same number of parameters, these models have been fine-tuned on more than 1000 additional tasks covering also more languages. As mentioned in the first few lines of the abstract :
Flan-PaLM 540B achieves state-of-the-art performance on several benchmarks, such as 75.2% on five-shot MMLU. We also publicly release Flan-T5 checkpoints,1 which achieve strong few-shot performance even compared to much larger models, such as PaLM 62B. Overall, instruction finetuning is a general method for improving the performance and usability of pretrained language models.
Disclaimer: Content from this model card has been written by the Hugging Face team, and parts of it were copy pasted from the T5 model card.