
Downloads · 30 days
103
9% of all-time downloads
nota-ai/ERGO-7B
ERGO-7B is a image-text-to-text model from nota-ai. Use it for the image-text-to-text task on the model card, and read the license before you ship it in a product. It is set up for transformers. The card lists the license as apache-2.0.
<p align="center" <a href="https://arxiv.org/abs/2509.21991" <img src="https://img.shields.io/badge/arXiv-paper-red"</a <a href="https://github.com/nota-github/ERGO.git" <img src="https://img.shields.io/badge/github-c…
Downloads · 30 days
103
9% of all-time downloads
All-time downloads
1.1K
Public
Parameters
8.3B
16.6 GB on disk
Likes
15
Public
Click a slice to open those files.
.safetensors16.6 GB · 100%
From the Hugging Face model README
ERGO (Efficient Reasoning & Guided Observation) is a large vision–language model trained with reinforcement learning on efficiency objectives, focusing on task-relevant regions to enhance accuracy and achieve up to a 3× speedup in inference.
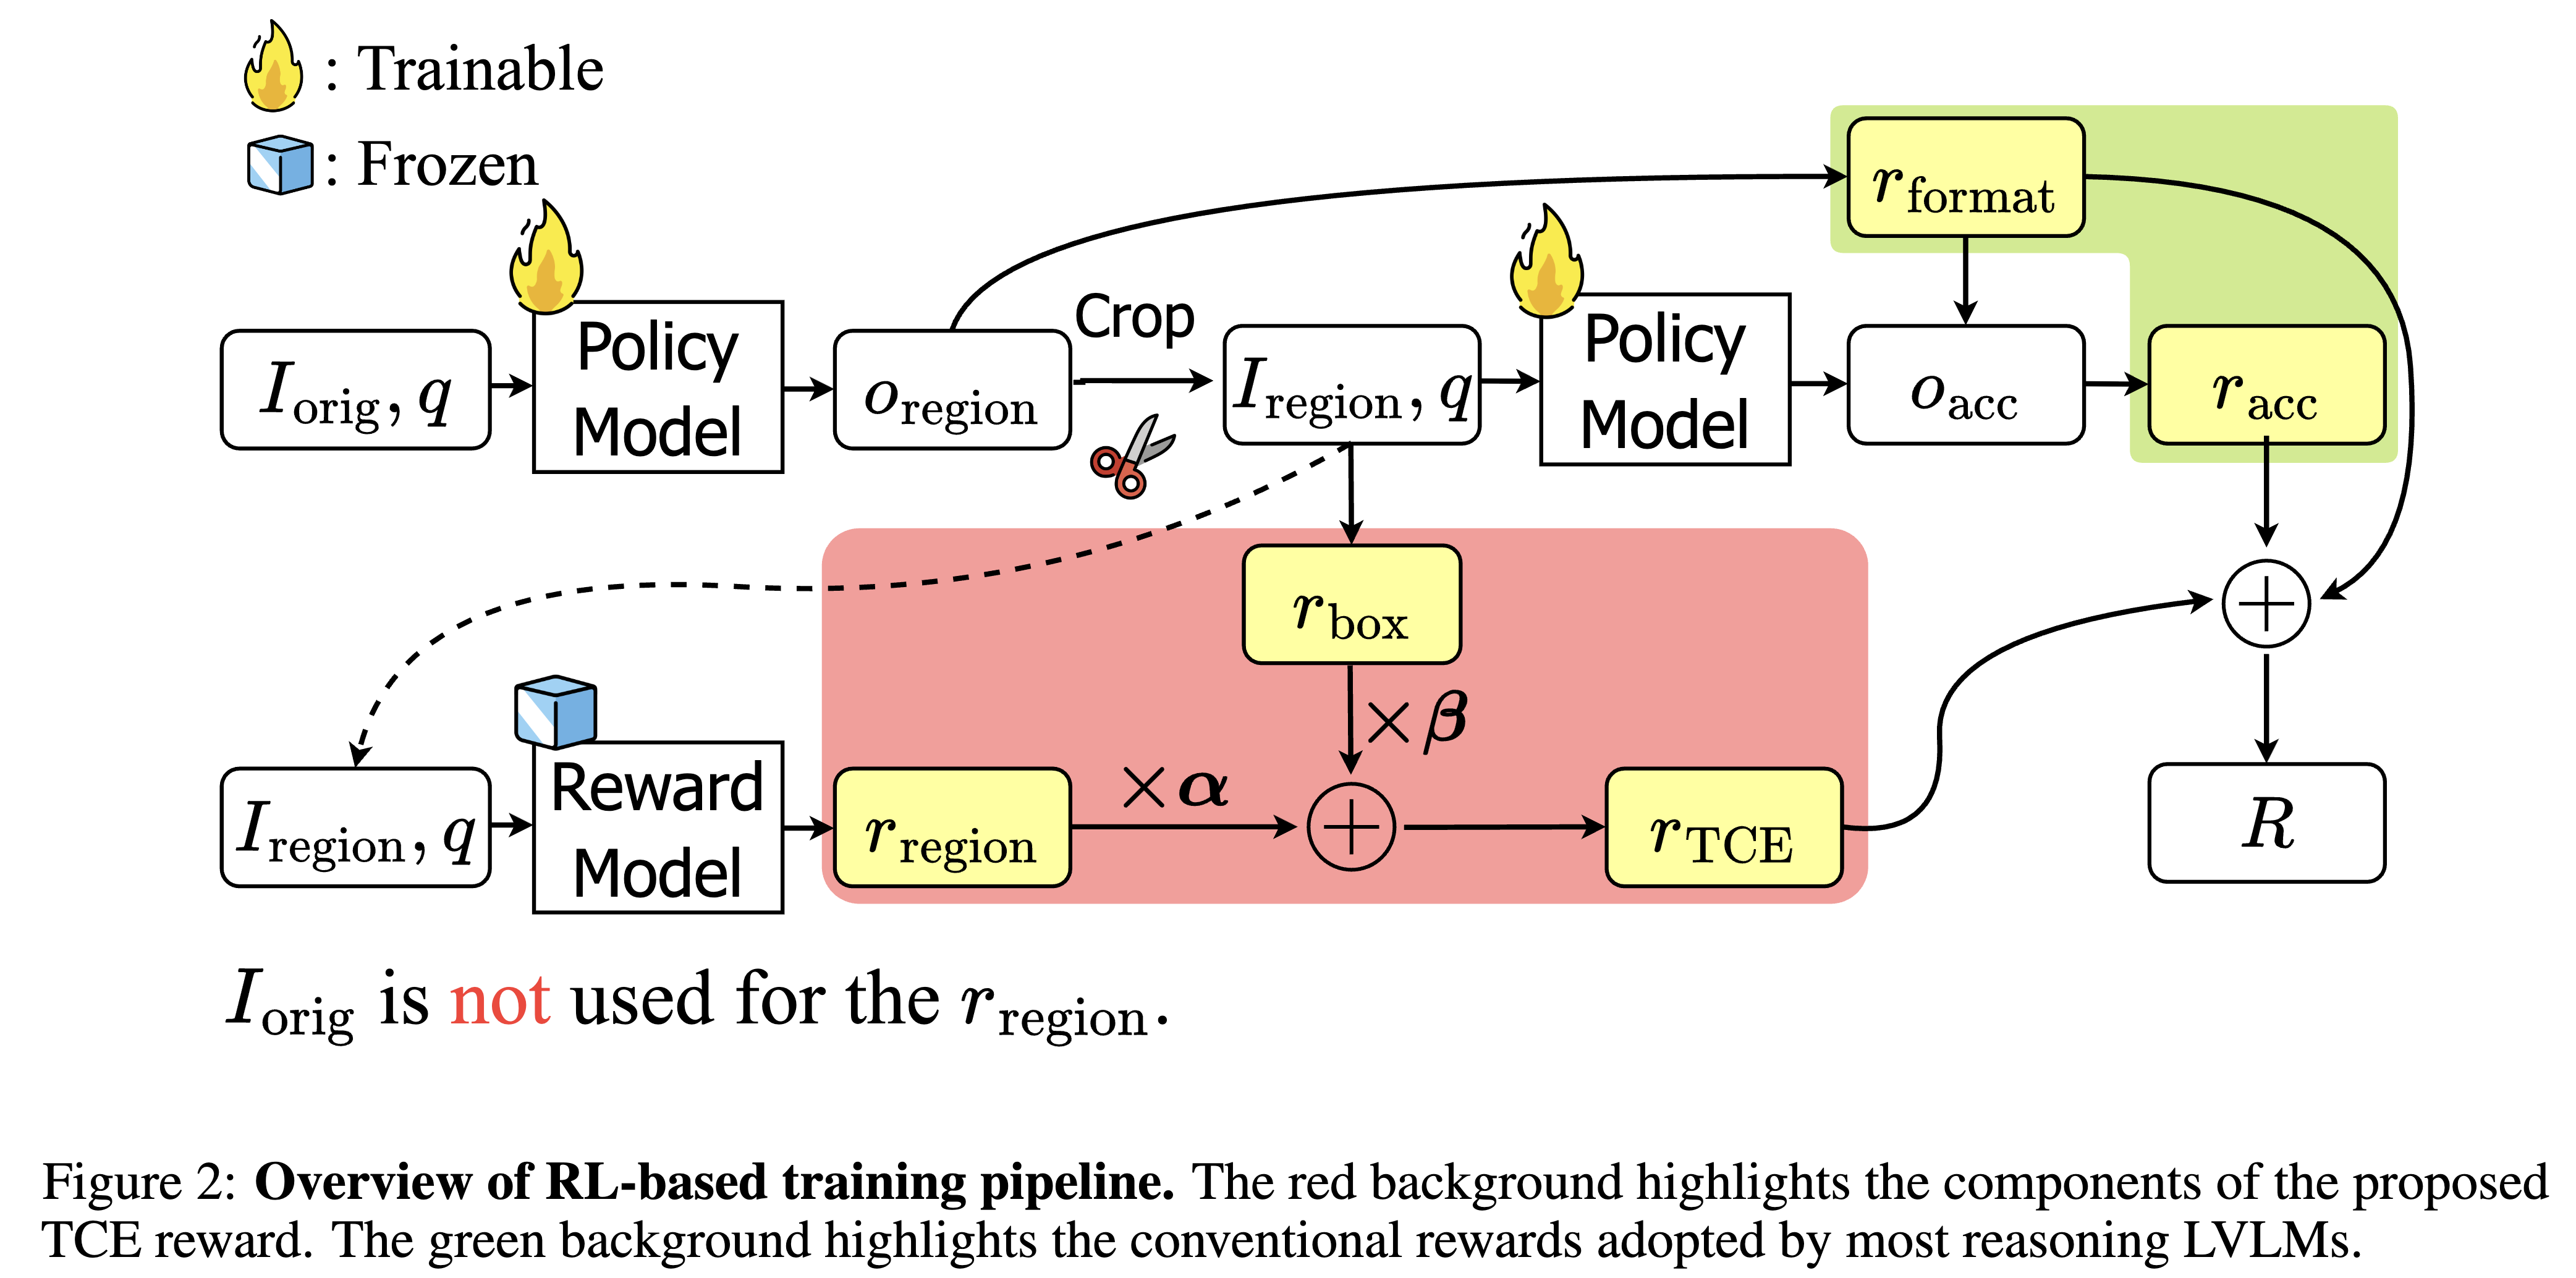
Python >= 3.10 is required.
curl -LsSf https://astral.sh/uv/install.sh | sh
git clone https://github.com/nota-github/ERGO.git
cd ERGO
uv venv
uv sync
source .venv/bin/activate
uv pip install -e .
We recommend using vLLM, as its
Automatic Prefix Cachingcan significantly improve inference speed.
This repository provides evaluation scripts for the following benchmarks:
See data/README.md for how to prepare datasets
bash ./scripts/run_vllm.sh
export MAX_VISION_TOKEN_NUM=1280
export VLLM_ENDPOINT=http://127.0.0.1:8008/v1
export DATA_ROOT=./data

python ./src/ergo/eval.py \
    --dataset {choose from [vstar, mmerwl, hrbench]} \
    --data_root $DATA_ROOT\
    --api_url $VLLM_ENDPOINT \
    --max_vision_token_num $MAX_VISION_TOKEN_NUM
python ./src/ergo/infer.py \
    --input_path {default = "./data/demo/demo.jpg"} \
    --question {default = "Is the orange luggage on the left or right side of the purple umbrella?"} \
    {--save_output} # optional
This project is released under Apache 2.0 licence.
We would like to express our sincere appreciation to the following projects:
We also deeply appreciate the generous GPU resource support from Gwangju AICA.
@misc{lee2025ergoefficienthighresolutionvisual,
      title={ERGO: Efficient High-Resolution Visual Understanding for Vision-Language Models},
      author={Jewon Lee and Wooksu Shin and Seungmin Yang and Ki-Ung Song and DongUk Lim and Jaeyeon Kim and Tae-Ho Kim and Bo-Kyeong Kim},
      year={2025},
      eprint={2509.21991},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2509.21991},
}