
Downloads · 30 days
12
4% of all-time downloads
nebchi/Llama3-Chat_Vector-kor_llava-v02
Llama3-Chat_Vector-kor_llava-v02 is a image-text-to-text model from nebchi. Use it for the image-text-to-text task on the model card, and read the license before you ship it in a product. It is set up for transformers. The card lists the license as cc-by-nc-sa-4.0.
I have implemented a Korean LLAVA model referring to the models created by Beomi, who made the Korean Chat Vector LLAVA model, and Toshi456, who made the Japanese Chat Vector LLAVA model.
Downloads · 30 days
12
4% of all-time downloads
All-time downloads
309
Public
Parameters
8.4B
16.7 GB on disk
Likes
2
Public
Click a slice to open those files.
.safetensors16.7 GB · 100%
From the Hugging Face model README
I have implemented a Korean LLAVA model referring to the models created by Beomi, who made the Korean Chat Vector LLAVA model, and Toshi456, who made the Japanese Chat Vector LLAVA model.
Citation
@misc {Llama3-Chat_Vector-kor_llava,
	author       = { {nebchi} },
	title        = { Llama3-Chat_Vector-kor_llava },
	year         = 2024,
	url          = { https://huggingface.co/nebchi/Llama3-Chat_Vector-kor_llava },
	publisher    = { Hugging Face }
}
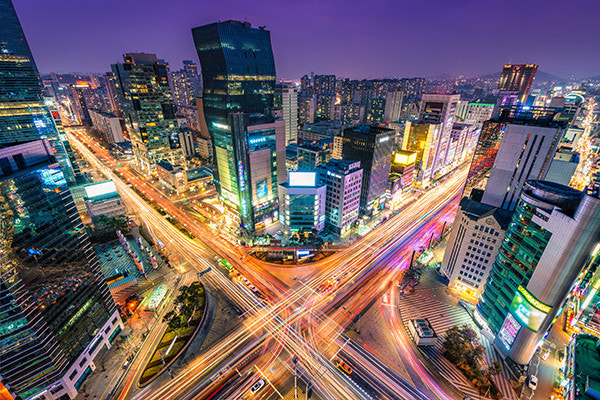
import requests
from PIL import Image

import torch
from transformers import AutoProcessor, LlavaForConditionalGeneration, TextStreamer

model_id = "nebchi/Llama3-Chat_Vector-kor_llava"

model = LlavaForConditionalGeneration.from_pretrained(
    model_id,
    torch_dtype='auto',
    device_map='auto',
    revision='a38aac3',
)

processor = AutoProcessor.from_pretrained(model_id)

tokenizer = processor.tokenizer
terminators = [
    tokenizer.eos_token_id,
    tokenizer.convert_tokens_to_ids("<|eot_id|>")
]
streamer = TextStreamer(tokenizer)

prompt = ("<|start_header_id|>user<|end_header_id|>\n\n<image>\n이 이미지에 대해서 설명해주세요.<|eot_id|>"
          "<|start_header_id|>assistant<|end_header_id|>\n\n이 이미지에는")
image_file = "https://search.pstatic.net/common/?src=http%3A%2F%2Fimgnews.naver.net%2Fimage%2F5582%2F2018%2F04%2F20%2F0000001323_001_20180420094641826.jpg&type=sc960_832"

raw_image = Image.open(requests.get(image_file, stream=True).raw)
inputs = processor(prompt, raw_image, return_tensors='pt').to(0, torch.float16)

output = model.generate(
    **inputs,
    max_new_tokens=512,
    do_sample=True,
    eos_token_id=terminators,
    no_repeat_ngram_size=3,
    temperature=0.7,
    top_p=0.9,
    streamer=streamer
)
print(processor.decode(output[0][2:], skip_special_tokens=False))
이 이미지에는 도시의 모습이 잘 보여집니다. 도시 내부에는 여러 건물과 건물들이 있고, 도시를 연결하는 도로와 교통 시스템이 잘 발달되어 있습니다. 이 도시의 특징은 높고 광범위한 건물들과 교통망을 갖춘 것이 좋습니다.