
Downloads · 30 days
24
6% of all-time downloads
navispace/Qwen3-VL-30B-A3B-Thinking-AWQ
Qwen3-VL-30B-A3B-Thinking-AWQ is a image-text-to-text model from navispace. Use it for the image-text-to-text task on the model card, and read the license before you ship it in a product. It is set up for transformers. The card lists the license as apache-2.0.
This model is a quantized version of Qwen/Qwen3-VL-30B-A3B-Thinking, specifically optimized for AMD GPUs (RDNA3 architecture) using ROCm and vLLM.
Downloads · 30 days
24
6% of all-time downloads
All-time downloads
380
Public
Parameters
5.1B
17.8 GB on disk
Likes
0
Public
Click a slice to open those files.
.safetensors17.8 GB · 100%
How the weights are stored.
I3229.9B · 96%
From the Hugging Face model README
This model is a quantized version of Qwen/Qwen3-VL-30B-A3B-Thinking, specifically optimized for AMD GPUs (RDNA3 architecture) using ROCm and vLLM.
The model was quantized using AWQ (Activation-aware Weight Quantization) with the following configuration, targeting efficient inference on AMD hardware:
pack-quantized (compatible with vLLM compressed-tensors){
"quantization_config": {
"quant_method": "compressed-tensors",
"format": "pack-quantized",
"config_groups": {
"group_0": {
"weights": {
"num_bits": 4,
"group_size": 128,
"symmetric": true,
"strategy": "group",
"observer": "mse"
},
"targets": ["Linear"]
}
},
"quantization_status": "compressed"
},
"dtype": "bfloat16",
"model_type": "qwen3_vl_moe"
}
This quantized model is prepared to run on AMD RDNA3 GPUs using the ROCm backend of vLLM.
docker.io/rocm/vllmThe following command assumes a 2-GPU setup (e.g., 2× RX 7900 XTX) with Tensor Parallelism set to 2. The model fits on a single GPU; a second GPU was used solely to extend the context length.
python -m vllm.entrypoints.openai.api_server \
  --model navispace/Qwen3-VL-32B-Thinking-AWQ \
  --served-model-name Qwen3-VL-32B-Thinking-AWQ \
  --tensor-parallel-size 2 \
  --max-model-len 131072 \
  --gpu-memory-utilization 0.95 \
  --enable-chunked-prefill \
  --host 0.0.0.0 \
  --port 8000 \
  --enable-prefix-caching \
  --max-num-seqs 2 \
  --max-num-batched-tokens 8192 \
  --enable-auto-tool-choice \
  --tool-call-parser hermes \
  --reasoning-parser deepseek_r1 \
  --trust-remote-code \
  --dtype float16 \
  --quantization compressed-tensors
This AWQ model preserves the original Qwen3-VL-30B-A3B-Thinking architecture and capabilities while significantly reducing VRAM requirements for ROCm-based deployments.
Meet Qwen3-VL — the most powerful vision-language model in the Qwen series to date.
This generation delivers comprehensive upgrades across the board: superior text understanding & generation, deeper visual perception & reasoning, extended context length, enhanced spatial and video dynamics comprehension, and stronger agent interaction capabilities.
Available in Dense and MoE architectures that scale from edge to cloud, with Instruct and reasoning‑enhanced Thinking editions for flexible, on‑demand deployment.
Visual Agent: Operates PC/mobile GUIs—recognizes elements, understands functions, invokes tools, completes tasks.
Visual Coding Boost: Generates Draw.io/HTML/CSS/JS from images/videos.
Advanced Spatial Perception: Judges object positions, viewpoints, and occlusions; provides stronger 2D grounding and enables 3D grounding for spatial reasoning and embodied AI.
Long Context & Video Understanding: Native 256K context, expandable to 1M; handles books and hours-long video with full recall and second-level indexing.
Enhanced Multimodal Reasoning: Excels in STEM/Math—causal analysis and logical, evidence-based answers.
Upgraded Visual Recognition: Broader, higher-quality pretraining is able to “recognize everything”—celebrities, anime, products, landmarks, flora/fauna, etc.
Expanded OCR: Supports 32 languages (up from 19); robust in low light, blur, and tilt; better with rare/ancient characters and jargon; improved long-document structure parsing.
Text Understanding on par with pure LLMs: Seamless text–vision fusion for lossless, unified comprehension.
Interleaved-MRoPE: Full‑frequency allocation over time, width, and height via robust positional embeddings, enhancing long‑horizon video reasoning.
DeepStack: Fuses multi‑level ViT features to capture fine‑grained details and sharpen image–text alignment.
Text–Timestamp Alignment: Moves beyond T‑RoPE to precise, timestamp‑grounded event localization for stronger video temporal modeling.
This is the weight repository for Qwen3-VL-30B-A3B-Thinking.
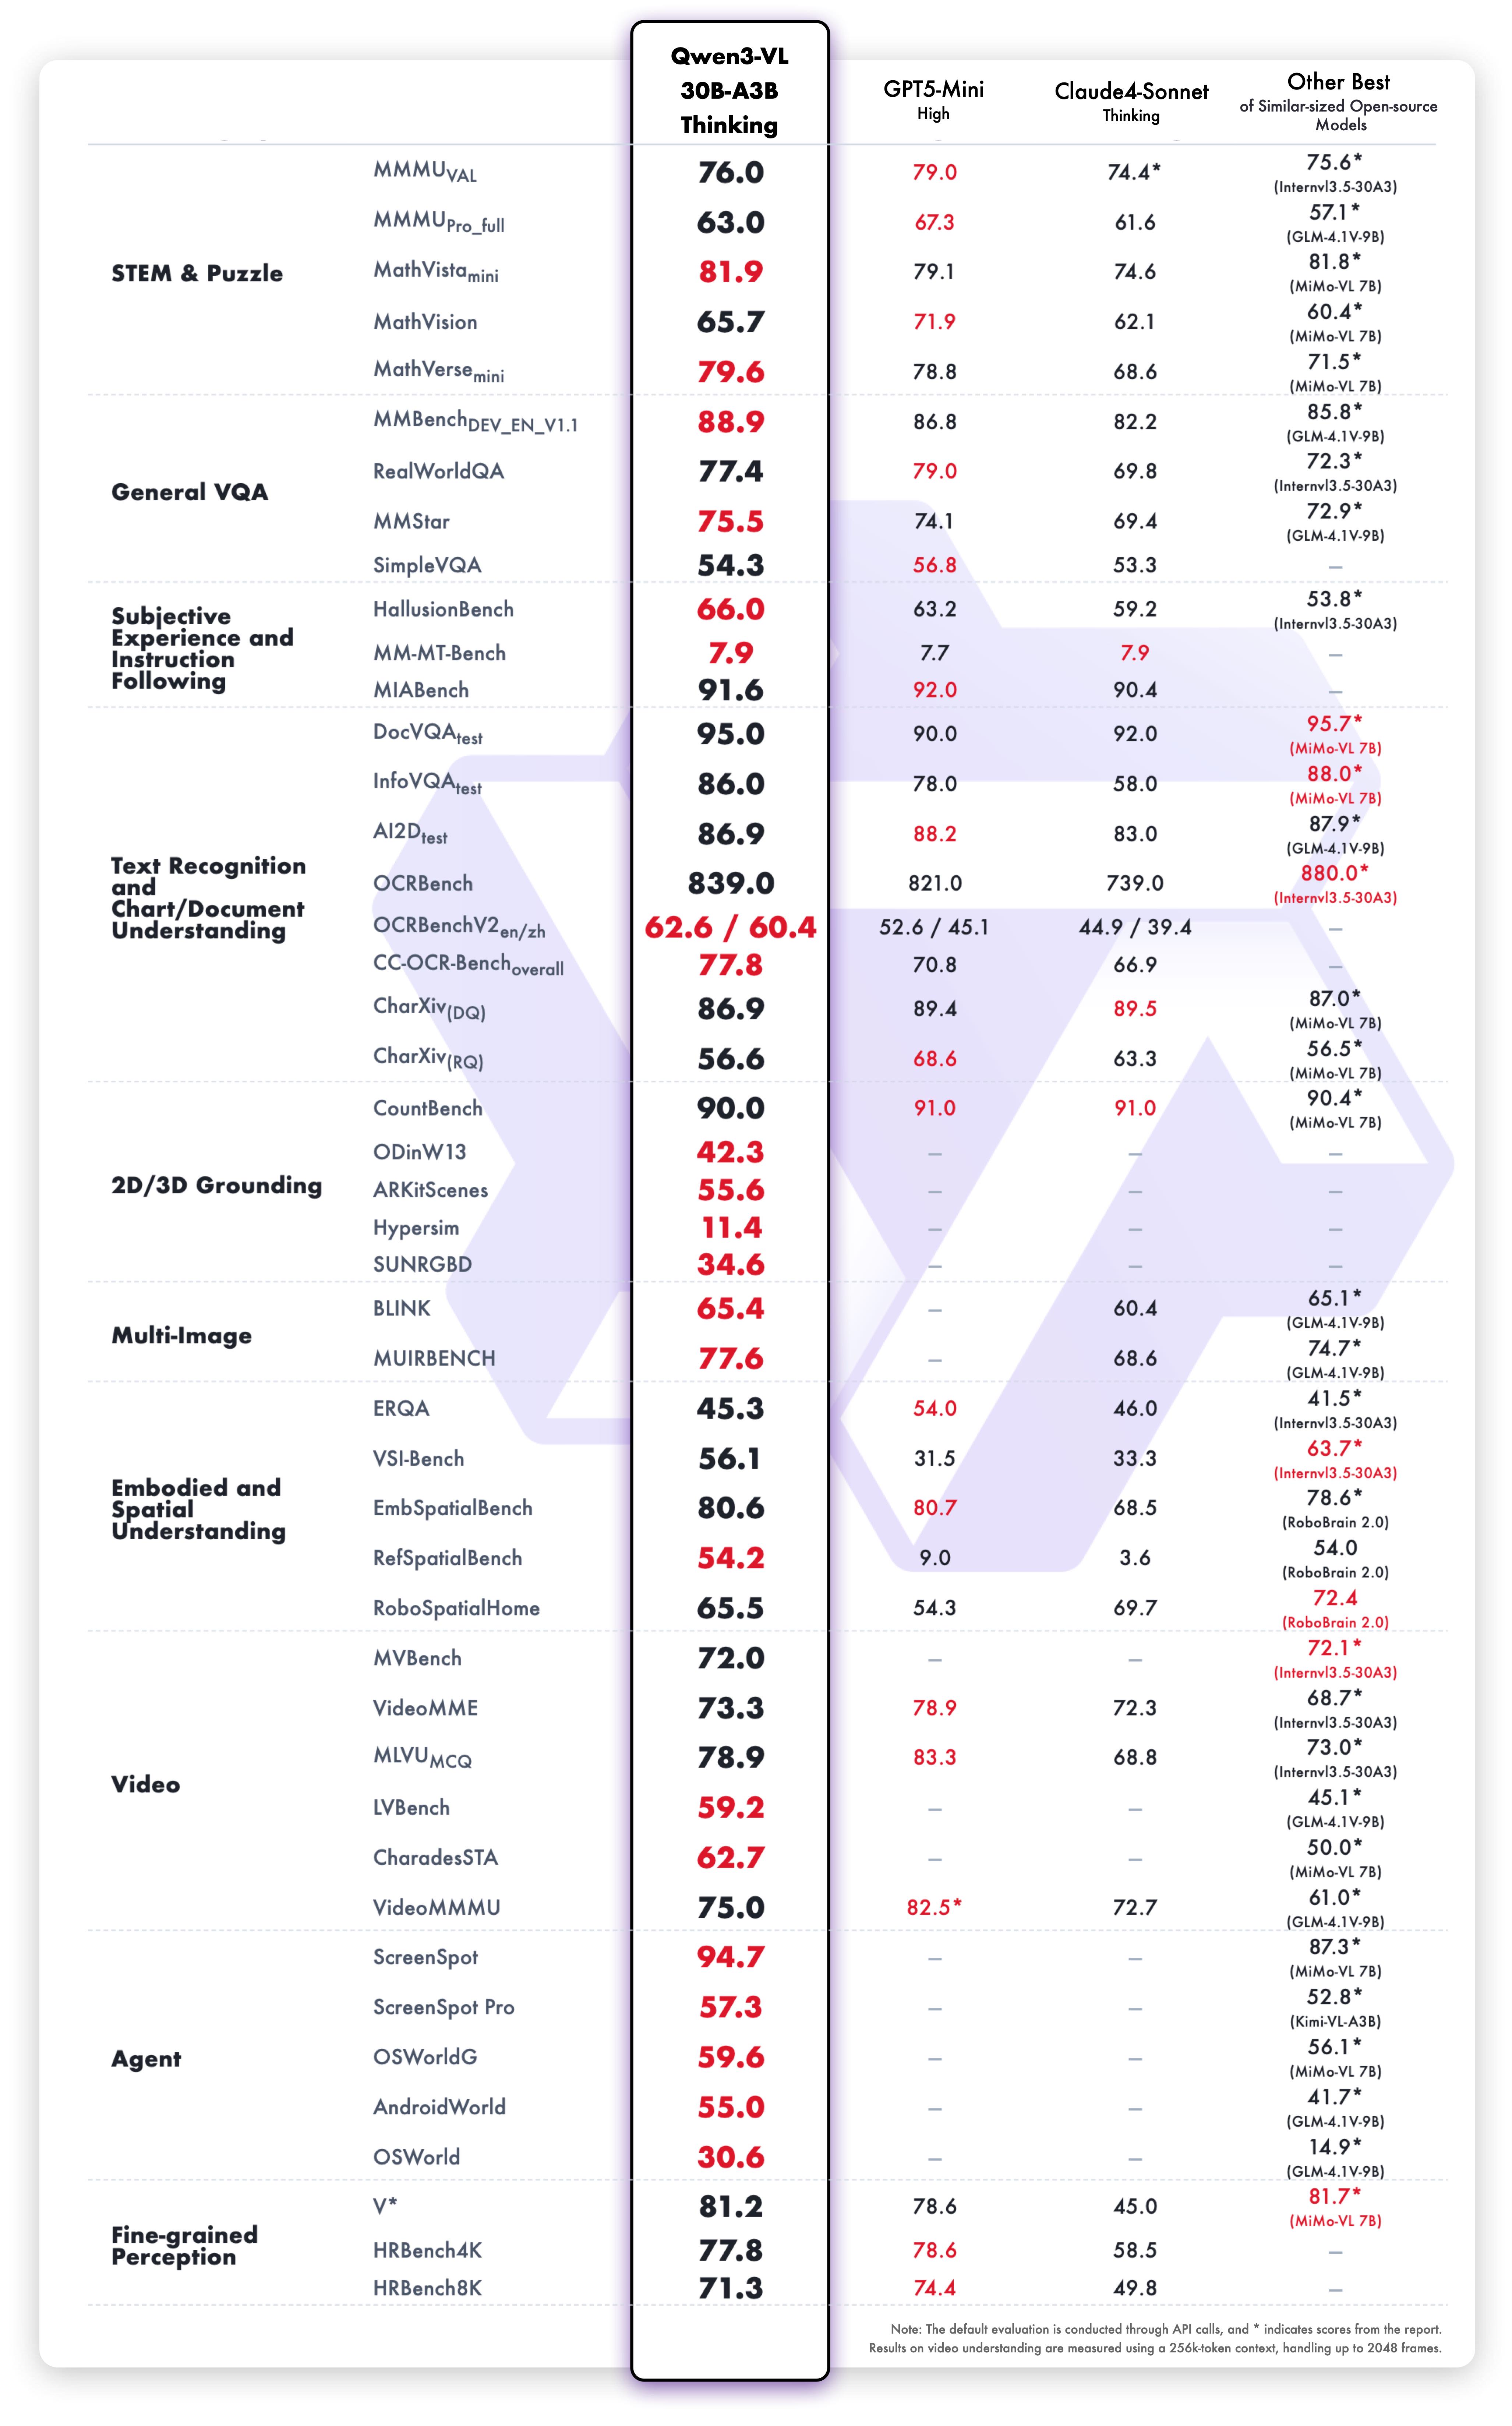
Multimodal performance
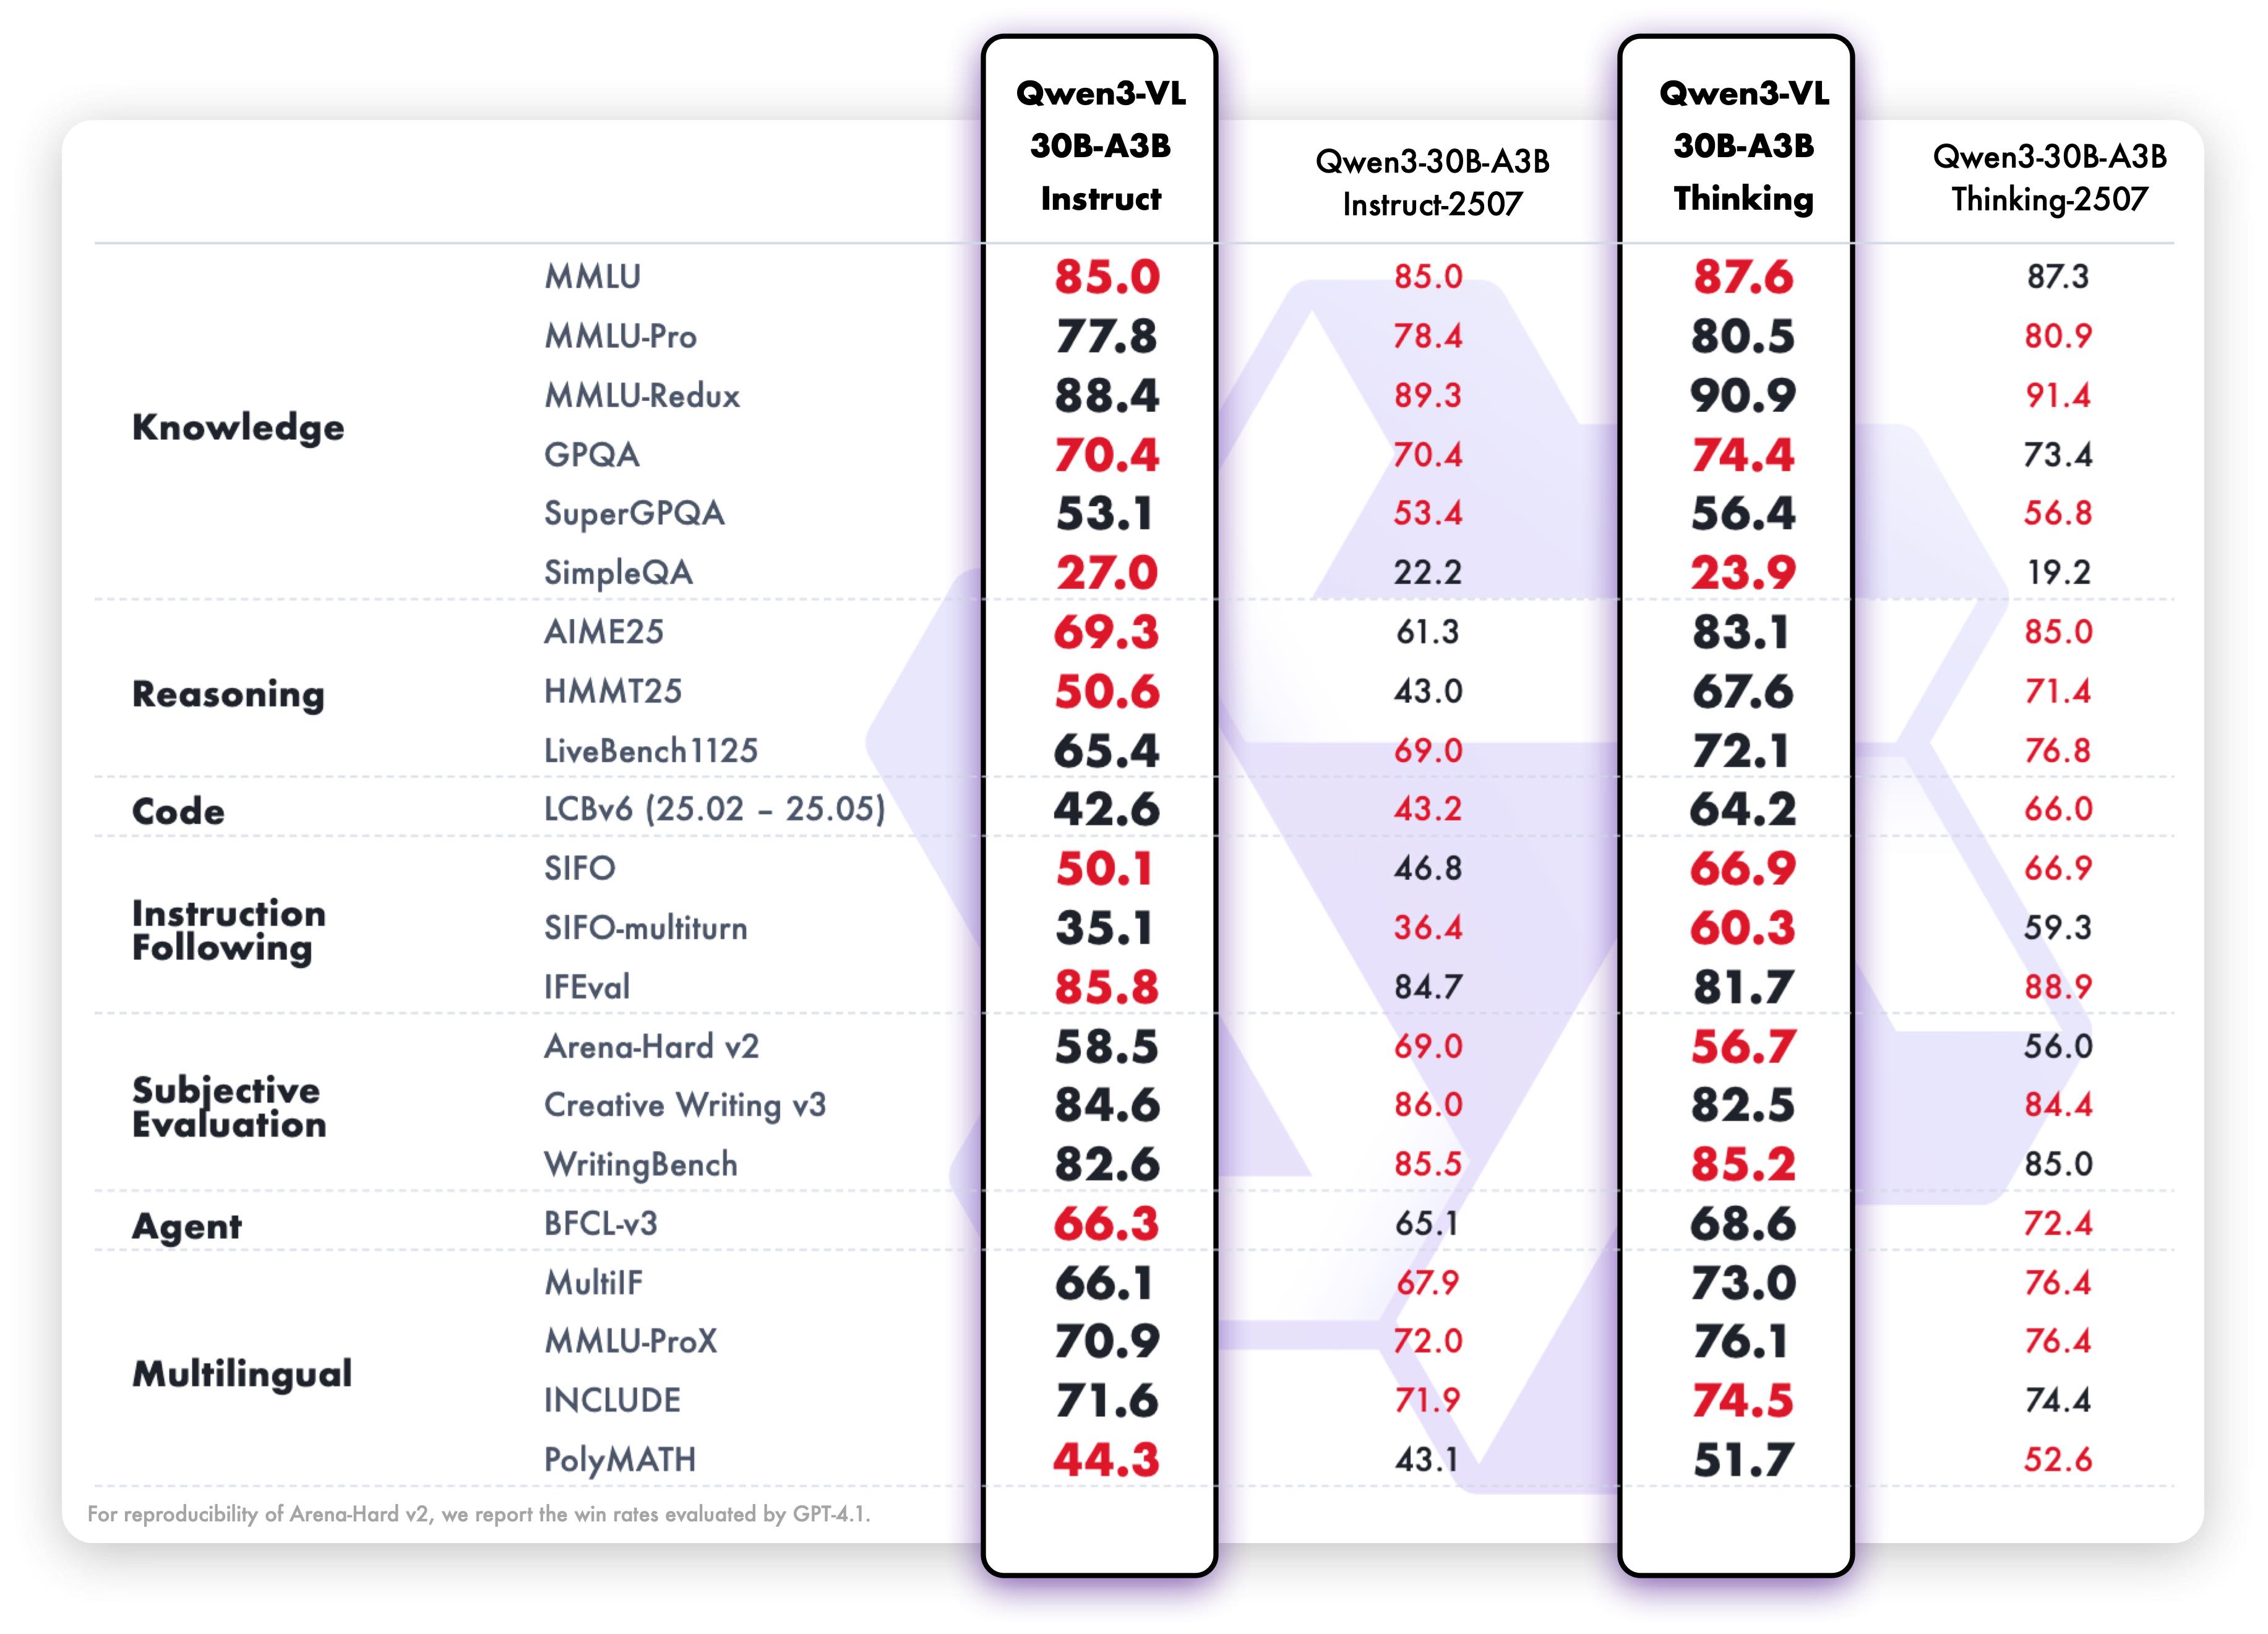
Pure text performance
Below, we provide simple examples to show how to use Qwen3-VL with 🤖 ModelScope and 🤗 Transformers.
The code of Qwen3-VL has been in the latest Hugging face transformers and we advise you to build from source with command:
pip install git+https://github.com/huggingface/transformers
# pip install transformers==4.57.0 # currently, V4.57.0 is not released
Here we show a code snippet to show you how to use the chat model with transformers:
from transformers import Qwen3VLMoeForConditionalGeneration, AutoProcessor

# default: Load the model on the available device(s)
model = Qwen3VLMoeForConditionalGeneration.from_pretrained(
    "Qwen/Qwen3-VL-30B-A3B-Thinking", dtype="auto", device_map="auto"
)

# We recommend enabling flash_attention_2 for better acceleration and memory saving, especially in multi-image and video scenarios.
# model = Qwen3VLMoeForConditionalGeneration.from_pretrained(
#     "Qwen/Qwen3-VL-30B-A3B-Thinking",
#     dtype=torch.bfloat16,
#     attn_implementation="flash_attention_2",
#     device_map="auto",
# )

processor = AutoProcessor.from_pretrained("Qwen/Qwen3-VL-30B-A3B-Thinking")

messages = [
    {
        "role": "user",
        "content": [
            {
                "type": "image",
                "image": "https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen-VL/assets/demo.jpeg",
            },
            {"type": "text", "text": "Describe this image."},
        ],
    }
]

# Preparation for inference
inputs = processor.apply_chat_template(
    messages,
    tokenize=True,
    add_generation_prompt=True,
    return_dict=True,
    return_tensors="pt"
)

# Inference: Generation of the output
generated_ids = model.generate(**inputs, max_new_tokens=128)
generated_ids_trimmed = [
    out_ids[len(in_ids) :] for in_ids, out_ids in zip(inputs.input_ids, generated_ids)
]
output_text = processor.batch_decode(
    generated_ids_trimmed, skip_special_tokens=True, clean_up_tokenization_spaces=False
)
print(output_text)
If you find our work helpful, feel free to give us a cite.
@misc{qwen3technicalreport,
      title={Qwen3 Technical Report},
      author={Qwen Team},
      year={2025},
      eprint={2505.09388},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2505.09388},
}

@article{Qwen2.5-VL,
  title={Qwen2.5-VL Technical Report},
  author={Bai, Shuai and Chen, Keqin and Liu, Xuejing and Wang, Jialin and Ge, Wenbin and Song, Sibo and Dang, Kai and Wang, Peng and Wang, Shijie and Tang, Jun and Zhong, Humen and Zhu, Yuanzhi and Yang, Mingkun and Li, Zhaohai and Wan, Jianqiang and Wang, Pengfei and Ding, Wei and Fu, Zheren and Xu, Yiheng and Ye, Jiabo and Zhang, Xi and Xie, Tianbao and Cheng, Zesen and Zhang, Hang and Yang, Zhibo and Xu, Haiyang and Lin, Junyang},
  journal={arXiv preprint arXiv:2502.13923},
  year={2025}
}

@article{Qwen2VL,
  title={Qwen2-VL: Enhancing Vision-Language Model's Perception of the World at Any Resolution},
  author={Wang, Peng and Bai, Shuai and Tan, Sinan and Wang, Shijie and Fan, Zhihao and Bai, Jinze and Chen, Keqin and Liu, Xuejing and Wang, Jialin and Ge, Wenbin and Fan, Yang and Dang, Kai and Du, Mengfei and Ren, Xuancheng and Men, Rui and Liu, Dayiheng and Zhou, Chang and Zhou, Jingren and Lin, Junyang},
  journal={arXiv preprint arXiv:2409.12191},
  year={2024}
}

@article{Qwen-VL,
  title={Qwen-VL: A Versatile Vision-Language Model for Understanding, Localization, Text Reading, and Beyond},
  author={Bai, Jinze and Bai, Shuai and Yang, Shusheng and Wang, Shijie and Tan, Sinan and Wang, Peng and Lin, Junyang and Zhou, Chang and Zhou, Jingren},
  journal={arXiv preprint arXiv:2308.12966},
  year={2023}
}