
Downloads · 30 days
47
0% of all-time downloads
mlabonne/NeuralLlama-3-8B-Instruct-abliterated
NeuralLlama-3-8B-Instruct-abliterated is a text generation model from mlabonne. Use it when you need the model to write or continue text. It is set up for transformers. The card lists the license as other.
This model is an experimental DPO fine-tune of an abliterated Llama 3 8B Instruct model on the full mlabonne/orpo-dpo-mix-40k dataset. It improves Llama 3 8B Instruct's performance while being uncensored.
Downloads · 30 days
47
0% of all-time downloads
All-time downloads
70.9K
Public
Parameters
8B
16.1 GB on disk
Likes
9
Public
Click a slice to open those files.
.safetensors16.1 GB · 100%
From the Hugging Face model README
This model is an experimental DPO fine-tune of an abliterated Llama 3 8B Instruct model on the full mlabonne/orpo-dpo-mix-40k dataset. It improves Llama 3 8B Instruct's performance while being uncensored.
This is an uncensored model. You can use it for any application that doesn't require alignment, like role-playing.
Tested on LM Studio using the "Llama 3" preset.
This model improves the performance of the abliterated source model and recovers the MMLU that was lost in the abliteration process.
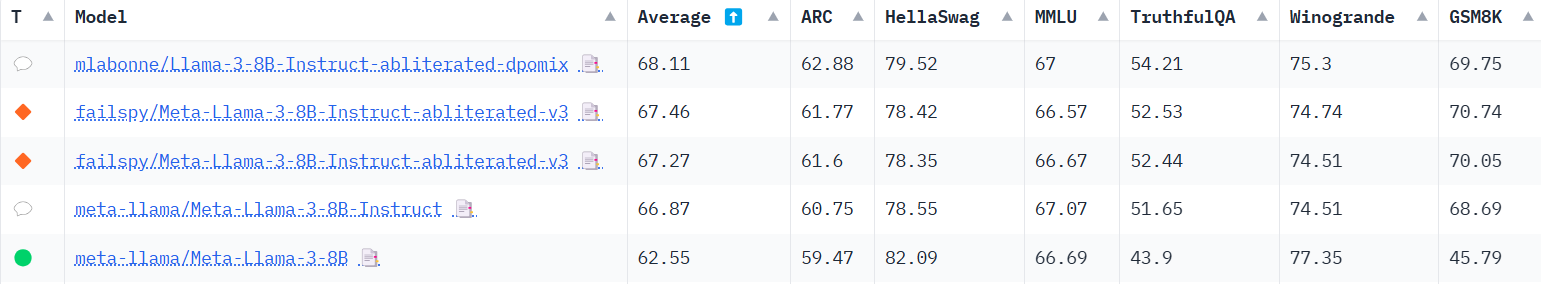
| Model | Average | AGIEval | GPT4All | TruthfulQA | Bigbench |
|---|---|---|---|---|---|
| mlabonne/Llama-3-8B-Instruct-abliterated-dpomix 📄 | 52.26 | 41.6 | 69.95 | 54.22 | 43.26 |
| meta-llama/Meta-Llama-3-8B-Instruct 📄 | 51.34 | 41.22 | 69.86 | 51.65 | 42.64 |
| failspy/Meta-Llama-3-8B-Instruct-abliterated-v3 📄 | 51.21 | 40.23 | 69.5 | 52.44 | 42.69 |
| abacusai/Llama-3-Smaug-8B 📄 | 49.65 | 37.15 | 69.12 | 51.66 | 40.67 |
| mlabonne/OrpoLlama-3-8B 📄 | 48.63 | 34.17 | 70.59 | 52.39 | 37.36 |
| meta-llama/Meta-Llama-3-8B 📄 | 45.42 | 31.1 | 69.95 | 43.91 | 36.7 |
!pip install -qU transformers accelerate

from transformers import AutoTokenizer
import transformers
import torch

model = "mlabonne/Llama-3-8B-Instruct-abliterated-dpomix"
messages = [{"role": "user", "content": "What is a large language model?"}]

tokenizer = AutoTokenizer.from_pretrained(model)
prompt = tokenizer.apply_chat_template(messages, tokenize=False, add_generation_prompt=True)
pipeline = transformers.pipeline(
    "text-generation",
    model=model,
    torch_dtype=torch.float16,
    device_map="auto",
)

outputs = pipeline(prompt, max_new_tokens=256, do_sample=True, temperature=0.7, top_k=50, top_p=0.95)
print(outputs[0]["generated_text"])