
Downloads · 30 days
21
1% of all-time downloads
mgoin/GLM-4.6-FP8-BLOCK
GLM-4.6-FP8-BLOCK is a text generation model from mgoin. Use it when you need the model to write or continue text. It is set up for transformers. The card lists the license as mit.
Downloads · 30 days
21
1% of all-time downloads
All-time downloads
2K
Public
Parameters
357B
358 GB on disk
Likes
0
Public
Click a slice to open those files.
.safetensors358 GB · 100%
How the weights are stored.
F8_E4M3355B · 100%
From the Hugging Face model README
Made using LLM Compressor model_free_ptq:
from llmcompressor import model_free_ptq

MODEL_ID = "zai-org/GLM-4.6"
SAVE_DIR = MODEL_ID.rstrip("/").split("/")[-1] + "-FP8-BLOCK"

# Apply FP8-Block to the model
# Once quantized, the model is saved
# using compressed-tensors to the SAVE_DIR.
model_free_ptq(
    model_stub=MODEL_ID,
    save_directory=SAVE_DIR,
    scheme="FP8_BLOCK",
    ignore=[
        "re:.*gate$",
        "lm_head",
        "model.embed_tokens",
    ],
    max_workers=15,
    device="cuda:0",
)
GSM8k running with vLLM TP=4 on GB300
vllm serve GLM-4.6-FP8-BLOCK -tp=4

python tests/evals/gsm8k/gsm8k_eval.py
Running GSM8K evaluation: 1319 questions, 5-shot
Evaluating: 100%|█████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████| 1319/1319 [00:52<00:00, 25.15it/s]

Results:
Accuracy: 0.929
Invalid responses: 0.001
Total latency: 52.449 s
Questions per second: 25.148
Total output tokens: 131828
Output tokens per second: 2513.428
Compared with GLM-4.5, GLM-4.6 brings several key improvements:
We evaluated GLM-4.6 across eight public benchmarks covering agents, reasoning, and coding. Results show clear gains over GLM-4.5, with GLM-4.6 also holding competitive advantages over leading domestic and international models such as DeepSeek-V3.1-Terminus and Claude Sonnet 4.
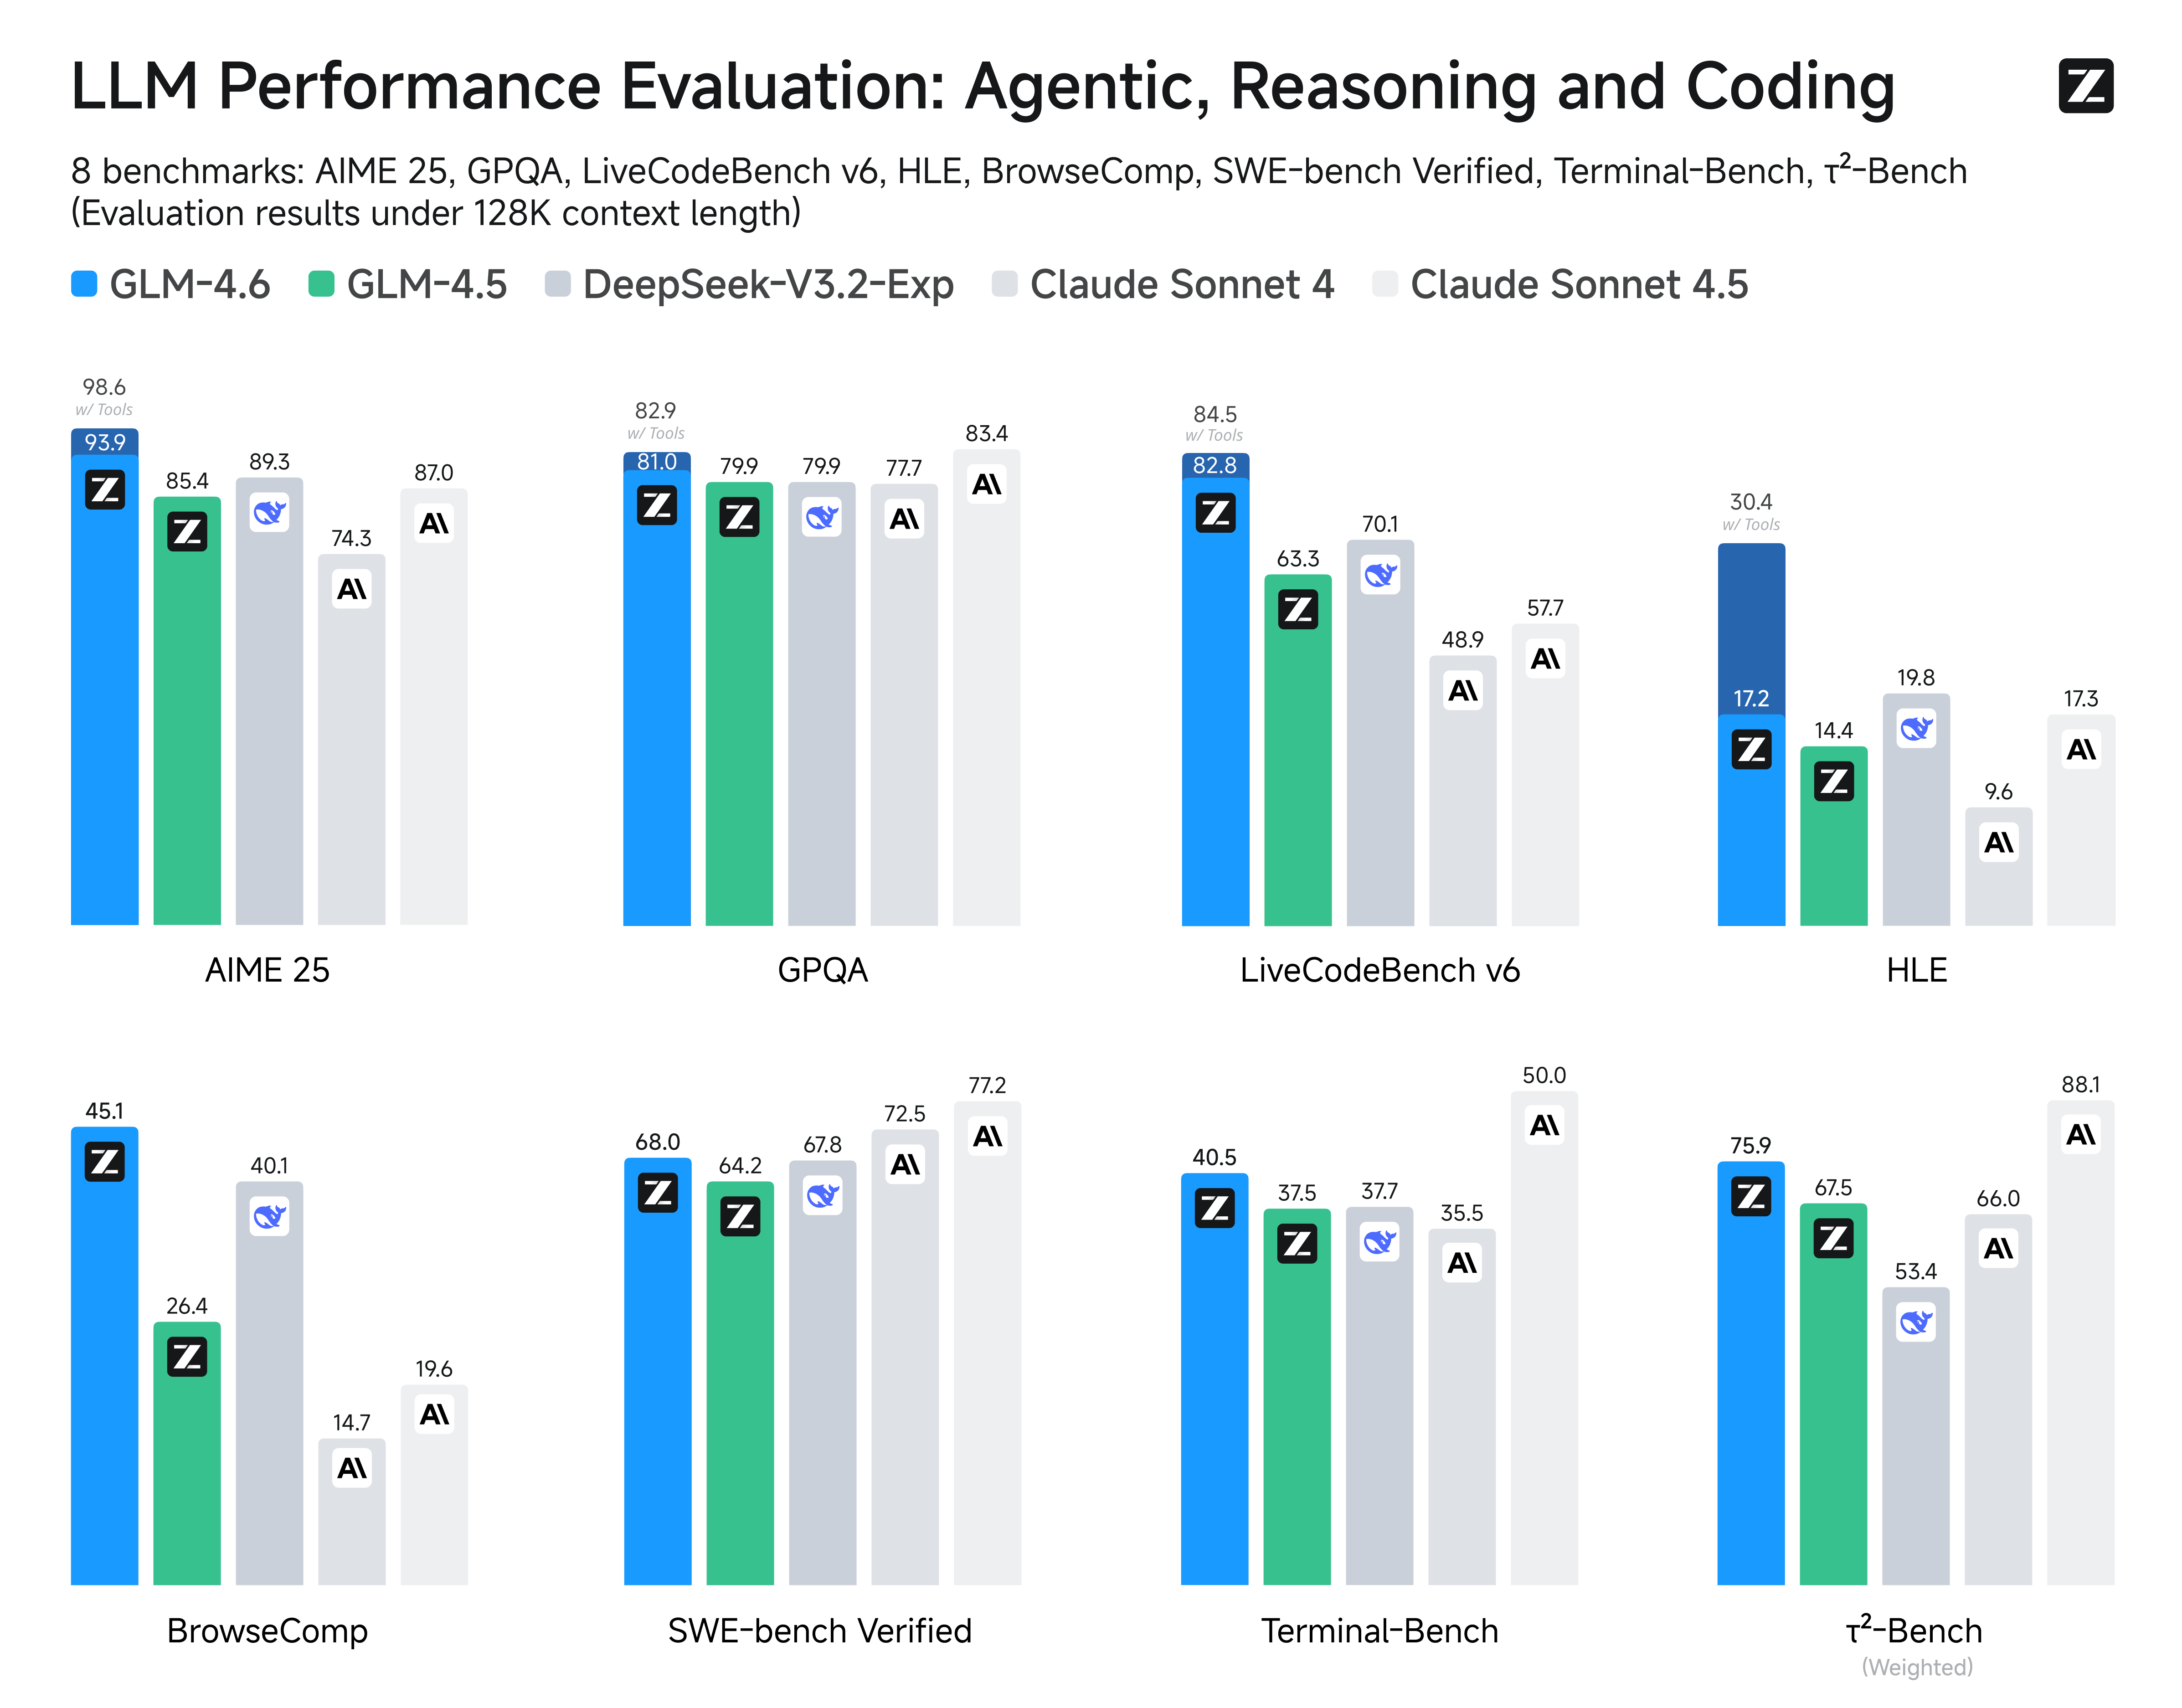
Both GLM-4.5 and GLM-4.6 use the same inference method.
you can check our github for more detail.
For general evaluations, we recommend using a sampling temperature of 1.0.
For code-related evaluation tasks (such as LCB), it is further recommended to set:
top_p = 0.95top_k = 40