Downloads · 30 days
41
3% of all-time downloads
maurice/PolitBERT
PolitBERT is a fill-mask model from maurice. Use it when you need the model to fill a missing word. It is set up for transformers.
This model was created to specialize on political speeches, interviews and press briefings of English-speaking politicians.
Downloads · 30 days
41
3% of all-time downloads
All-time downloads
1.3K
Public
Repo size
1.3 GB
Likes
1
Public
Click a slice to open those files.
.bin438 MB · 50%
From the Hugging Face model README
This model was created to specialize on political speeches, interviews and press briefings of English-speaking politicians.
The model was initialized using the pre-trained weights of BERT<sub>BASE</sub> and trained for 20 epochs on the standard MLM task with default parameters.
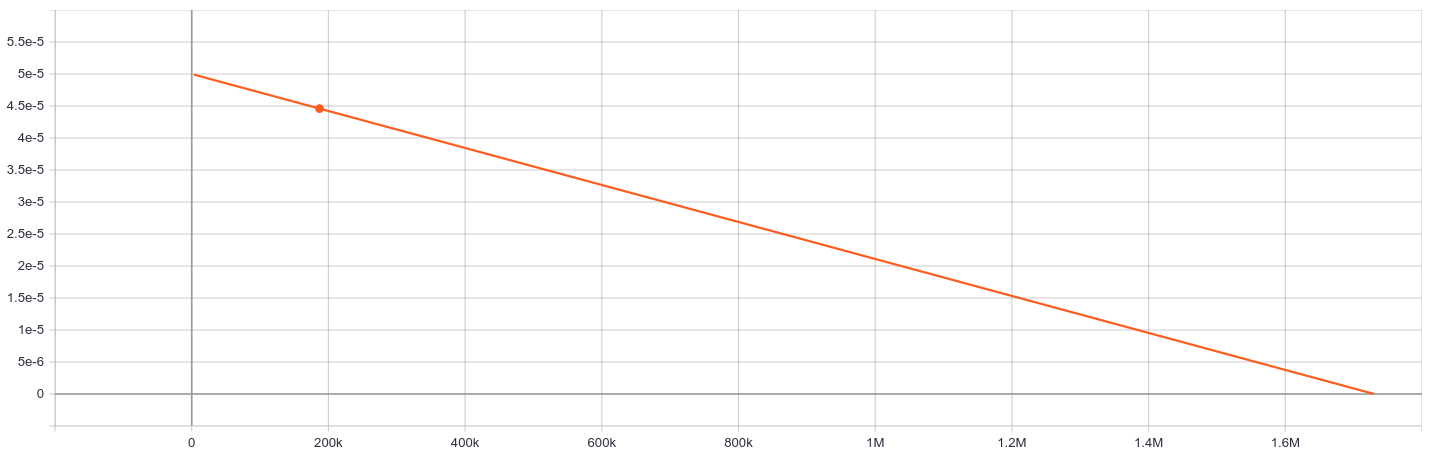
The used learning rate was 5e-5 with a linearly decreasing schedule and AdamW.
The used batch size is 8 per GPU while beeing trained on two Nvidia GTX TITAN X.
The rest of the used configuration is the same as in AutoConfig.from_pretrained('bert-base-uncased').
As a tokenizer the default tokenizer of BERT was used (BertTokenizer.from_pretrained('bert-base-uncased'))
PolitBERT was trained on the following dataset, which has been split up into single sentences: https://www.kaggle.com/mauricerupp/englishspeaking-politicians
To predict a missing word of a sentence, the following pipeline can be applied:
from transformers import pipeline, BertTokenizer, AutoModel

fill_mask = pipeline("fill-mask",
                     model=AutoModel.from_pretrained('maurice/PolitBERT'),
                     tokenizer=BertTokenizer.from_pretrained('bert-base-uncased'))

print(fill_mask('Donald Trump is a [MASK].'))
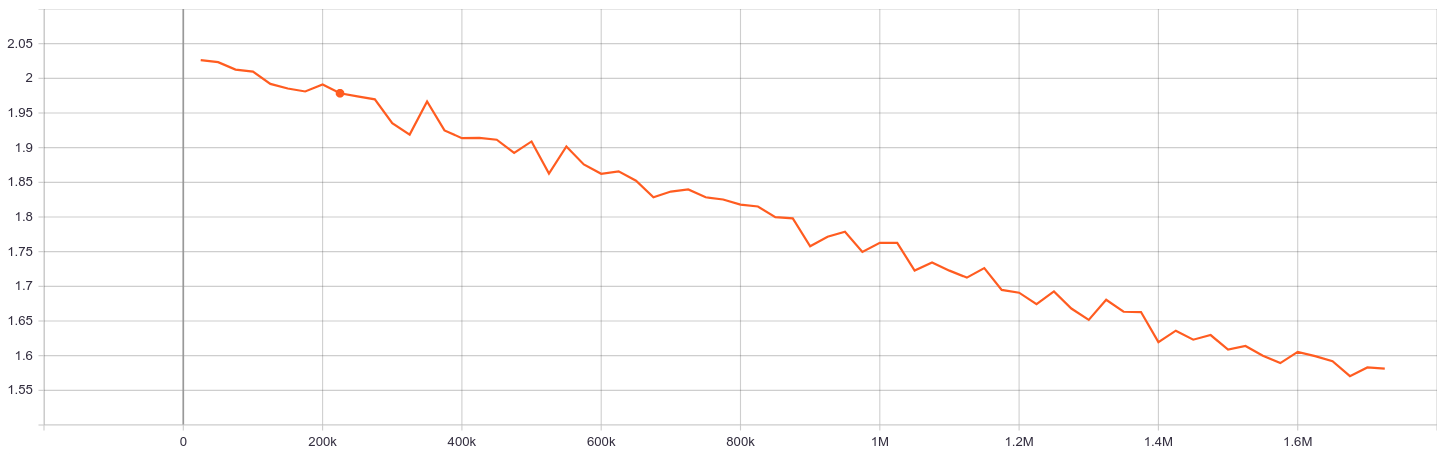
Evaluation Loss:
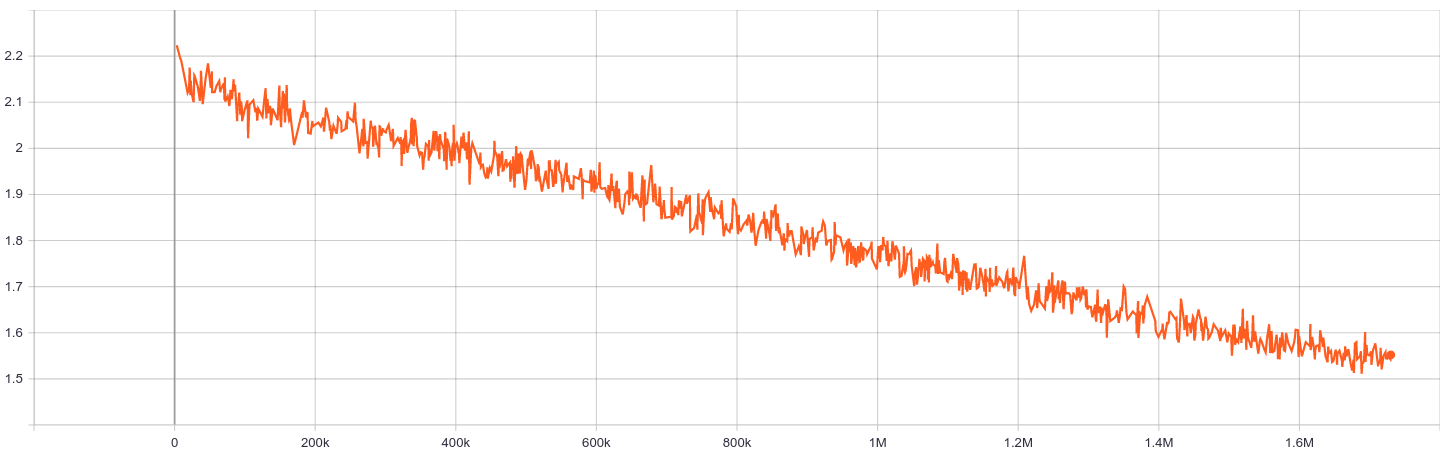
 Training Loss:
 Learning Rate Schedule: