
Downloads · 30 days
41
5% of all-time downloads
marzanconsulting/donut-dr-matriculas-ocr
donut-dr-matriculas-ocr is a image-to-text model from marzanconsulting. Use it when you need a caption or text from an image. It is set up for transformers. The card lists the license as mit.
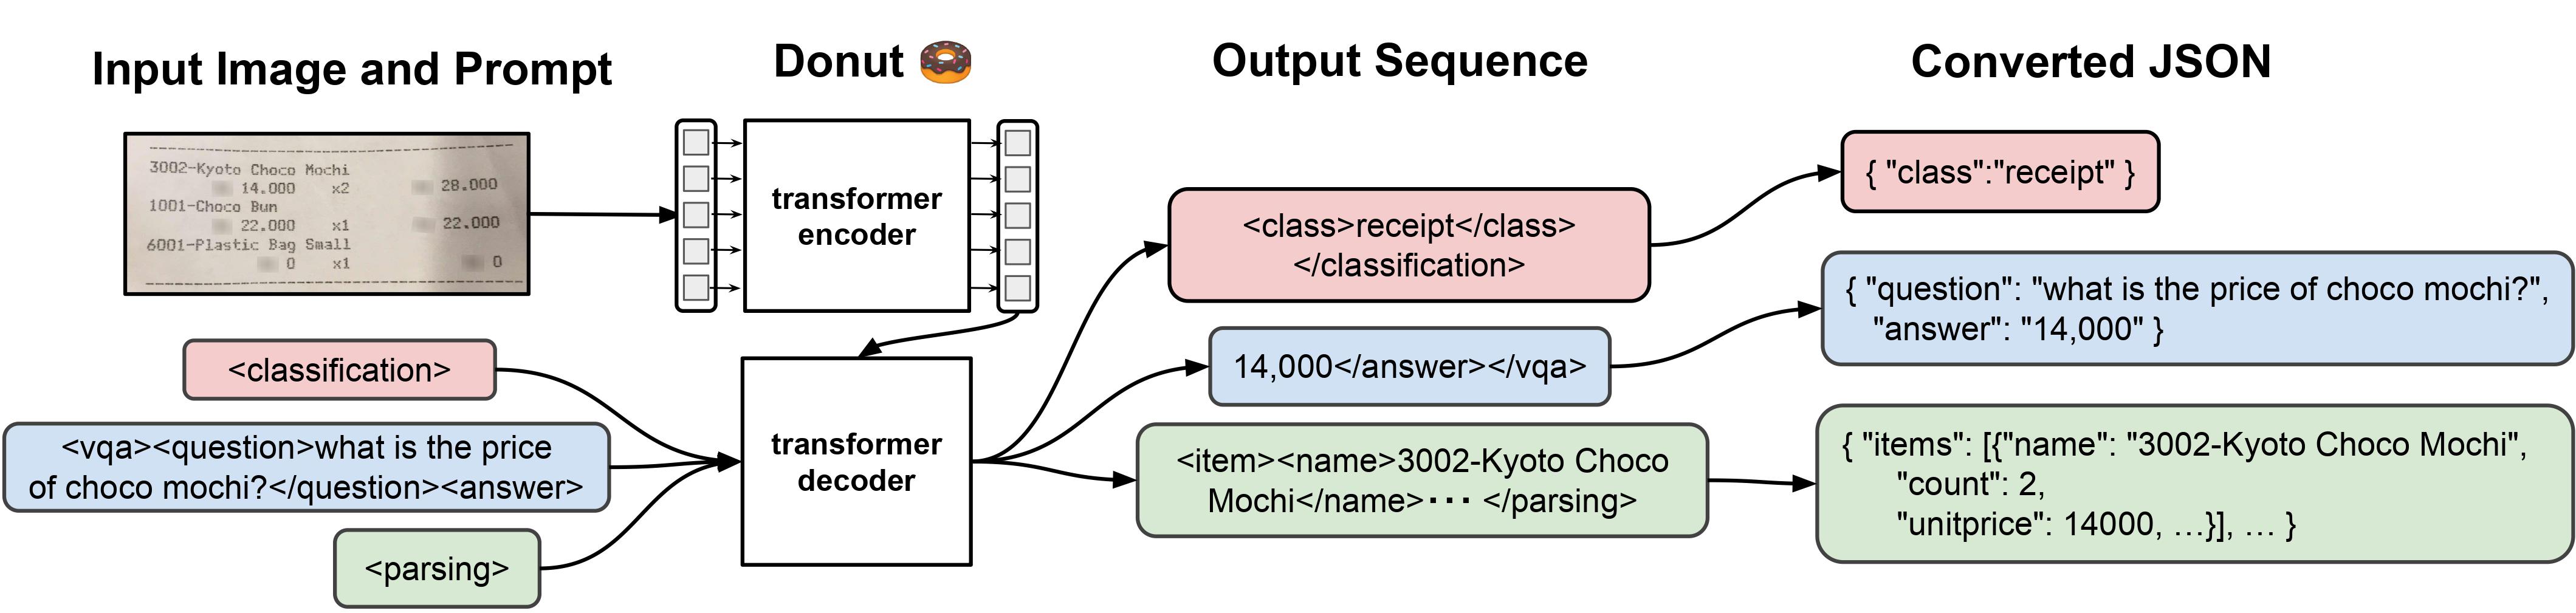
Donut model was introduced in the paper OCR-free Document Understanding Transformer by Geewok et al. and first released in this repository.
Downloads · 30 days
41
5% of all-time downloads
All-time downloads
837
Public
Repo size
1.7 GB
Likes
0
Public
Click a slice to open those files.
.bin859 MB · 100%
From the Hugging Face model README
Donut model was introduced in the paper OCR-free Document Understanding Transformer by Geewok et al. and first released in this repository.
This model is a finetune of the donut base model on a propietary dataset. Its purpose is to efficiently extract text from the dominican official vehicle registration documents.
This propietary dataset was manually corrected, and we prepared the teacher forcing (ground truth) data with the images and json lines. The license for the V1 model is mit, available under the MIT license.
It achieves the following results on the evaluation set:
The task_prompt has been changed to <s_matricula> for the V1.
The focus for the next or future version, will be to collect a better an larger dataset for training.
Donut consists of a vision encoder (Swin Transformer) and a text decoder (BART). Given an image, the encoder first encodes the image into a tensor of embeddings (of shape batch_size, seq_len, hidden_size), after which the decoder autoregressively generates text, conditioned on the encoding of the encoder.
import torch
import re
from PIL import Image
from transformers import DonutProcessor
#from transformers import VisionEncoderDecoderModel

import warnings
warnings.filterwarnings("ignore")

from sconf import Config
from donut import DonutConfig, DonutModel

config = Config(default="./config.yaml")

device = torch.device('cuda:0' if torch.cuda.is_available() else 'cpu')
processor = DonutProcessor.from_pretrained("marzanconsulting/donut-dr-matriculas-ocr")

model = DonutModel.from_pretrained(
                "marzanconsulting/donut-dr-matriculas-ocr",
                input_size=config.input_size,
                max_length=config.max_length,
                align_long_axis=config.align_long_axis,
                ignore_mismatched_sizes=True,
            )

model.to(device)

def load_and_preprocess_image(image_path: str, processor):
    """
    Load an image and preprocess it for the model.
    """
    image = Image.open(image_path).convert("RGB")
    pixel_values = processor(image, return_tensors="pt").pixel_values
    return pixel_values

def generate_text_from_image(model, image_path: str, processor, device):
    """
    Generate text from an image using the trained model.
    """
    # Load and preprocess the image
    pixel_values = load_and_preprocess_image(image_path, processor)
    pixel_values = pixel_values.to(device)

    decoder_input_ids = processor.tokenizer(task_prompt="<s_matricula>",
                                            add_special_tokens=False,
                                            return_tensors="pt").input_ids

    decoded_text = model.inference(image_tensors=pixel_values,
                                   prompt_tensors=decoder_input_ids)["predictions"][0]

    return decoded_text

# Example usage
image_path = "path_to_your_image"  # Replace with your image path
extracted_text = generate_text_from_image(model, image_path, processor, device)
print("Extracted Text:", extracted_text)
Refer to the documentation for more code examples.
This fine-tuned model is specifically designed for extracting text from dominican vehicle registration (matriculas) documents, and may not perform optimally on other types of documents. The dataset used is still suboptimal (numerous errors are still there), thus, this model will need to be retrained later to improve its performance.
The following hyperparameters were used during training:
If you want to support me, you can here.
@article{DBLP:journals/corr/abs-2111-15664,
  author    = {Geewook Kim and
               Teakgyu Hong and
               Moonbin Yim and
               Jinyoung Park and
               Jinyeong Yim and
               Wonseok Hwang and
               Sangdoo Yun and
               Dongyoon Han and
               Seunghyun Park},
  title     = {Donut: Document Understanding Transformer without {OCR}},
  journal   = {CoRR},
  volume    = {abs/2111.15664},
  year      = {2021},
  url       = {https://arxiv.org/abs/2111.15664},
  eprinttype = {arXiv},
  eprint    = {2111.15664},
  timestamp = {Thu, 02 Dec 2021 10:50:44 +0100},
  biburl    = {https://dblp.org/rec/journals/corr/abs-2111-15664.bib},
  bibsource = {dblp computer science bibliography, https://dblp.org}
}