
Downloads · 30 days
145
14% of all-time downloads
maglun/Gemma-4-12B-it-QAT-Text-MLX-Mixed-3.70bpw
Gemma-4-12B-it-QAT-Text-MLX-Mixed-3.70bpw is a text generation model from maglun. Use it when you need the model to write or continue text. It is set up for mlx. The card lists the license as apache-2.0.
Downloads · 30 days
145
14% of all-time downloads
All-time downloads
1K
Public
Parameters
11.9B
5.5 GB on disk
Likes
1
Public
Click a slice to open those files.
.safetensors5.5 GB · 99%
How the weights are stored.
U3211.9B · 100%
From the Hugging Face model README
TEXT-ONLY MLX QUANTIZATION
An experimental MLX affine mixed-precision quantization of google/gemma-4-12B-it-qat-q4_0-unquantized. This release contains the extracted language-model path only: the upstream checkpoint is multimodal, but 11 multimodal tensor groups were intentionally omitted. Image, audio, video, and any-to-any inputs are not supported by this repository.
This is a personal experimental research preview. It is a compact release candidate, not a claim of lossless compression or equivalent quality to bf16. Feedback and reports from people trying it on Apple Silicon are welcome through the maintainer account maglun.
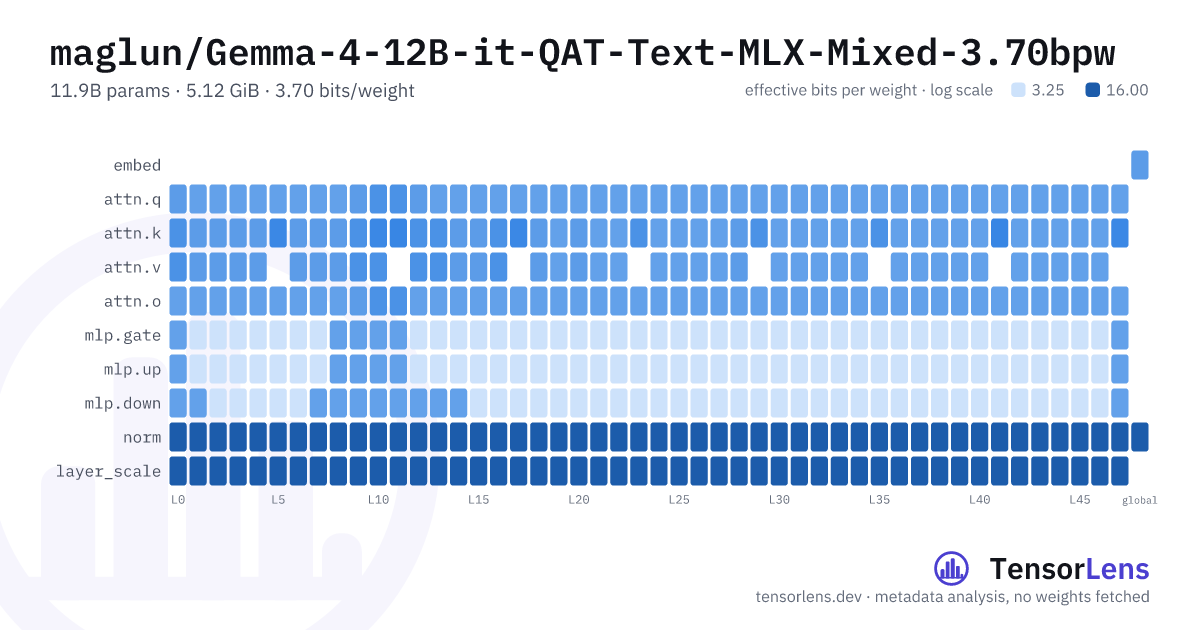 Fig 1. Bit allocation of model as shown on TensorLens (see link for details)
Install the current MLX-LM package and generate text with thinking enabled by default:
pip install -U mlx-lm

python -m mlx_lm.generate \
  --model maglun/Gemma-4-12B-it-QAT-Text-MLX-Mixed-3.70bpw \
  --prompt "Explain why the sky appears blue." \
  --temp 1.0 \
  --top-k 64 \
  --top-p 0.95 \
  --repetition-penalty 1.08 \
  --repetition-context-size 4096 \
  --max-tokens 256
The release benchmark used fixed per-item seeds, temperature=1.0, top_k=64, top_p=0.95, repetition penalty 1.08 with context 4096, an 8K generation cap, and suppression of the upstream modality boundary IDs 258883 and 258882. The public command above uses the same intended-use sampling values; exact seed control is benchmark-harness-specific.
The selected root chat_template.jinja is the current official 12B/QAT-compatible template pinned for this release. The original historical template is retained only as a labelled reference at reference/chat_template.original.jinja.reference and is not a loader-recognized template file.
QAT identifies the upstream source lineage. GPTQ describes a rounding/build stage. This published artifact is not GGUF, AutoGPTQ, or a uniform q4_0 model, and it does not use AWQ.
The release comparison was run with thinking enabled on the candidate and the direct QAT-unquantized bf16 text-path anchor, using identical fixed seeds, prompts, decoding settings, scorers, and suppression contract. Errors and capped outputs remain failures in the full denominators.
| Task | Candidate | Direct QAT-bf16 | Candidate − bf16 |
|---|---|---|---|
| IFEval strict prompt | 486/541 (89.83%) | 496/541 (91.68%) | −1.85 pp |
| MMLU-Pro | 258/400 (64.50%) | 291/400 (72.75%) | −8.25 pp |
| HumanEval+ | 145/164 (88.41%) | 146/164 (89.02%) | −0.61 pp |
| GSM8K | 372/400 (93.00%) | 376/400 (94.00%) | −1.00 pp |
| Unweighted mean of the four rows | 83.94% | 86.86% | −2.93 pp |
This is one fixed-seed sampled comparison, not a claim of universal ranking. The candidate's lower scores are part of the release evidence. The paired 95% bootstrap intervals for candidate-minus-bf16 were −3.55 to +0.19 pp (IFEval), −10.70 to −1.13 pp (MMLU-Pro), −6.17 to +4.94 pp (HumanEval+), and −2.60 to +2.08 pp (GSM8K).
Wikitext was evaluated separately with native Gemma chat framing, the instruction Continue the following text., explicit thinking disabled, and continuation-only scoring. The pinned English heldout fixture contains 41 documents; Swedish contains 80.
| Corpus | Candidate PPL | Direct QAT-bf16 PPL | Candidate / bf16 |
|---|---|---|---|
| English heldout | 16.6255 | 15.0995 | 1.1011× |
| Swedish heldout | 14.2315 | 12.5226 | 1.1365× |
The candidate and bf16 Wikitext runs used identical document IDs, term counts, and block manifests. The initial bare-BOS measurements are retained in the project ledger as invalid diagnostic evidence and are not the release metrics.
Measured on an Apple Mac mini with Apple M4 Pro, 64 GB unified memory, macOS 26.5, using MLX 0.32.0 and MLX-LM 0.31.3. These are machine-specific measurements, not guarantees.
| Measurement | Result |
|---|---|
| Cold load | 1.08–1.09 s |
| Prompt prefill, 44 tokens | 154.42–161.63 tok/s |
| Generation/decode, 256 tokens | 38.42–38.52 tok/s |
| MLX peak after decode | 5.374 GiB |
| 8,192-token prefill MLX peak | 10.316 GiB |
| 8,192-token prefill process RSS peak | 6.248 GiB |
The measurements used fresh processes and sampling with thinking enabled. Do not infer decode speed by dividing generated tokens by total prompt-plus-generation wall time.
The base model is google/gemma-4-12B-it-qat-q4_0-unquantized at revision b6ed86275a6a5735884e208bfed95b445a684ca2. The upstream metadata identifies Apache-2.0 and links to the Gemma 4 terms. Please review both before redistribution or use.
The conversion and allocation evidence is recorded in the release repository's private preparation ledger. Immutable artifact identifiers are:
safetensors set SHA-256: 89a3922294730b2739c396c21f4e06fc25b509dda3a41c62f01770566cfcdf4f
config SHA-256:          f876e02dc5692a254841f3877777907042757bba74894563255019f20b936e71
index SHA-256:           bbe00e8192c5dd8b64244a7153208d5eef3cddca1e96ac5a1f2d9f0e0366f2bc
tokenizer SHA-256:       cc8d3a0ce36466ccc1278bf987df5f71db1719b9ca6b4118264f45cb627bfe0f
chat template SHA-256:   ae53464bf3be25802b3a5b37def7fd89667067d7577049b3b2d74c4d8de4c6d4
Related personal experimental releases: Gemma 4 E2B Text MLX Mixed, Gemma 4 E4B Text MLX Mixed, and Qwen3.8 27B MLX Mixed. Their benchmark generations and sizes are not directly comparable to this release.