
Downloads · 30 days
65
4% of all-time downloads
m-a-p/CT-LLM-SFT-DPO
CT-LLM-SFT-DPO is a text generation model from m-a-p. Use it when you need the model to write or continue text. It is set up for transformers. The card lists the license as apache-2.0.
🌐 Homepage | 🤗 MAP-CC | 🤗 CHC-Bench | 🤗 CT-LLM | 📖 arXiv | GitHub
Downloads · 30 days
65
4% of all-time downloads
All-time downloads
1.6K
Public
Parameters
2.1B
4.3 GB on disk
Likes
5
Public
Click a slice to open those files.
.safetensors4.3 GB · 100%
From the Hugging Face model README
🌐 Homepage | 🤗 MAP-CC | 🤗 CHC-Bench | 🤗 CT-LLM | 📖 arXiv | GitHub
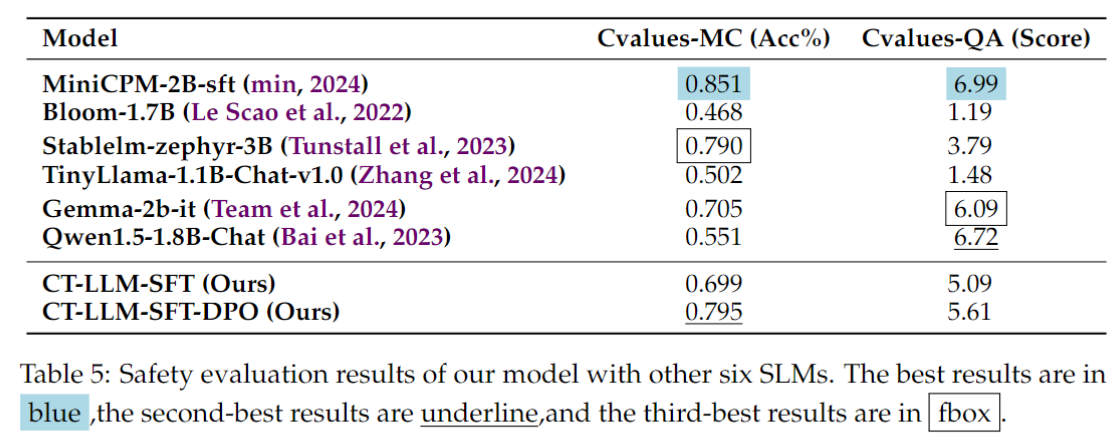
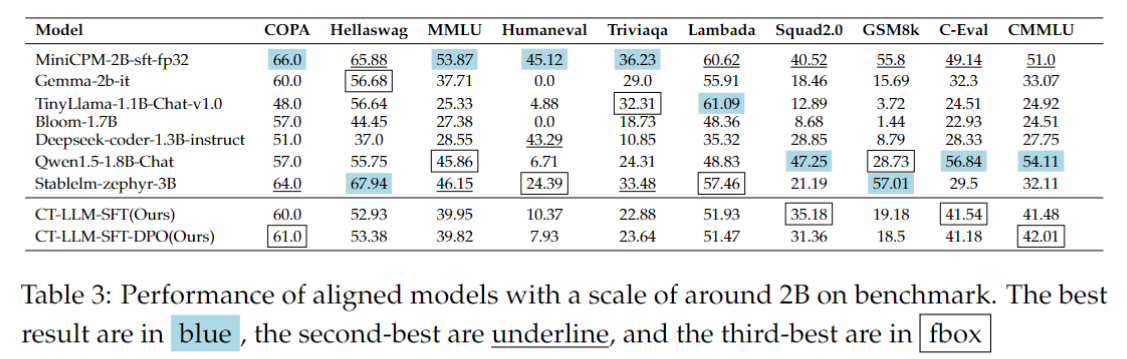
CT-LLM-SFT-DPO is an alignment version of CT-LLM. The main features of this model is:
Our model incorporates a blend of publicly accessible datasets and synthetic data from the LLM. The open-source Chinese datasets consist of non-harmful and beneficial sections from cvalues_rlhf, comparison_gpt4_data_zh and oaast_rm_zh in Llama-factory, huozi, and zhihu. For English, the dataset includes comparison_gpt4_data_en from Llama-factory and beavertails. To construct a more high-quality preference dataset via a synthetics approach, we adopt alpaca-gpt4 which generates "chosen" responses using GPT-4, and we adopt baichuan-6B serving as a weaker model for generating "reject" responses. The dataset comprises 183k Chinese pairs and 46k English pairs in total.
We leverage the CT-LLM-SFT as a reference model $\pi_{sft}$ to optimize the objective language model $\pi_{\theta}$. $\pi_{\theta}$ is initialized by the model parameters of the $\pi_{sft}$. We set the hyperparameters as follows:
from transformers import AutoModelForCausalLM, AutoTokenizer
model_path = '<your-model-path>'
tokenizer = AutoTokenizer.from_pretrained(model_path, use_fast=False, trust_remote_code=True)
model = AutoModelForCausalLM.from_pretrained(
    model_path,
    device_map="auto",
    torch_dtype='auto'
).eval()
messages = [
    {"role": "system", "content": "你是一个有用的人工智能助手。"},
    {"role": "user", "content": "你好"},
]
input_ids = tokenizer.apply_chat_template(conversation=messages, add_generation_prompt=True, return_tensors='pt')
output_ids = model.generate(input_ids.to('cuda'), max_new_tokens=20)
response = tokenizer.decode(output_ids[0][input_ids.shape[1]:], skip_special_tokens=True)
print(response)
This model, developed for academic purposes, employs rigorously compliance-checked training data to uphold the highest standards of integrity and compliance. Despite our efforts, the inherent complexities of data and the broad spectrum of model applications prevent us from ensuring absolute accuracy or appropriateness of the model outputs in every scenario.
It is essential to highlight that our model and its associated training data are intended solely for scholarly research. We explicitly disclaim any liability for problems that may arise from improper use, interpretation errors, unlawful activities, the dissemination of false information, or any data security issues related to the utilization of our model or its training data.
We strongly encourage users to report any concerns related to data misuse, security breaches, or potential infringement issues directly to us for immediate investigation and resolution.
[email protected]; [email protected]}Our commitment to responsible data sharing and the security of our academic tools is paramount. We thank you for your cooperation in maintaining the ethical use of this technology.