
Downloads · 30 days
83
7% of all-time downloads
lt-asset/Waffle_VLM_WebSight
Waffle_VLM_WebSight is a machine learning model from lt-asset. Use it for the machine learning task on the model card, and read the license before you ship it in a product. The card lists the license as bsd-3-clause-clear.
We develope WAFFLE, a fine-tuning approach to train multi-modal LLM (MLLM) to generate HTML code from webpage screenshots or UI designs. WAFFLE uses a structure-aware attention mechanism to improve MLLMs' understandin…
Downloads · 30 days
83
7% of all-time downloads
All-time downloads
1.1K
Public
Parameters
8.2B
16.4 GB on disk
Likes
14
Public
Click a slice to open those files.
.safetensors16.4 GB · 100%
From the Hugging Face model README
We develope WAFFLE, a fine-tuning approach to train multi-modal LLM (MLLM) to generate HTML code from webpage screenshots or UI designs. WAFFLE uses a structure-aware attention mechanism to improve MLLMs' understanding of HTML's structure and a contrastive fine-tuning approach to align MLLMs' understanding of UI images and HTML code. Models fine-tuned with WAFFLE show up to 9.00 pp (percentage point) higher HTML match, 0.0982 higher CW-SSIM, 32.99 higher CLIP, and 27.12 pp higher LLEM on our new benchmark WebSight-Test and an existing benchmark Design2Code.
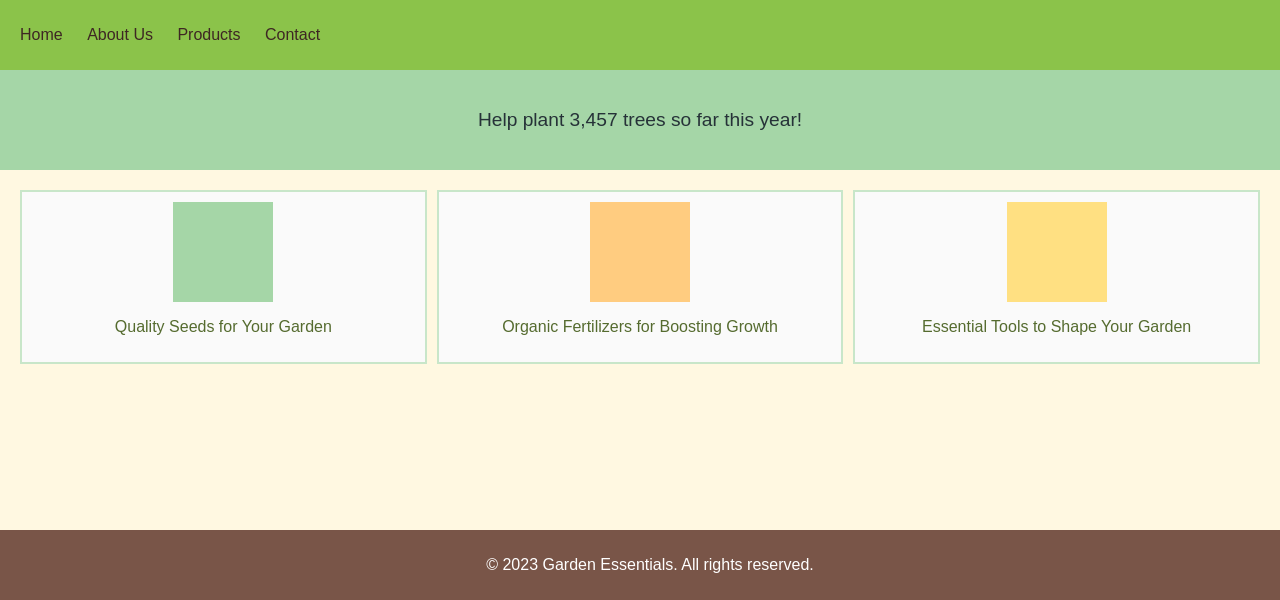
Find a webpage screenshot, or UI design:
import torch
from PIL import Image
from transformers import AutoProcessor, AutoModelForCausalLM
from transformers.image_utils import to_numpy_array, PILImageResampling, ChannelDimension
from transformers.image_transforms import resize, to_channel_dimension_format
from utils import TreeBuilder


def convert_to_rgb(image):
    if image.mode == "RGB":
        return image

    image_rgba = image.convert("RGBA")
    background = Image.new("RGBA", image_rgba.size, (255, 255, 255))
    alpha_composite = Image.alpha_composite(background, image_rgba)
    alpha_composite = alpha_composite.convert("RGB")
    return alpha_composite


def inference_vlm_websight(image_path, html_path):

    def custom_transform(x):
        x = convert_to_rgb(x)
        x = to_numpy_array(x)
        x = resize(x, (960, 960), resample=PILImageResampling.BILINEAR)
        x = processor.image_processor.rescale(x, scale=1 / 255)
        x = processor.image_processor.normalize(
            x,
            mean=processor.image_processor.image_mean,
            std=processor.image_processor.image_std
        )
        x = to_channel_dimension_format(x, ChannelDimension.FIRST)
        x = torch.tensor(x)
        return x

    model_dir = "lt-asset/Waffle_VLM_WebSight"
    processor = AutoProcessor.from_pretrained(model_dir)
    model = AutoModelForCausalLM.from_pretrained(model_dir, torch_dtype=torch.bfloat16, trust_remote_code=True).cuda()

    assert model.config.web_attention_range == 2, "Waffle_VLM_WebSight is trained with hierarchical attention applied to 2 / 8 heads"
    # use 2/8 = 1/4 attention heads for hierarchical attention (as described in paper)
    model.eval()

    image_seq_len = model.config.perceiver_config.resampler_n_latents
    BOS_TOKEN = processor.tokenizer.bos_token
    BAD_WORDS_IDS = processor.tokenizer(["<image>", "<fake_token_around_image>"], add_special_tokens=False).input_ids

    image = Image.open(image_path)
    inputs = processor.tokenizer(
        f"{BOS_TOKEN}<fake_token_around_image>{'<image>' * image_seq_len}<fake_token_around_image>",
        return_tensors="pt",
        add_special_tokens=False,
    )
    inputs["pixel_values"] = processor.image_processor([image], transform=custom_transform).to(dtype=torch.bfloat16)
    inputs_for_generation = {k: v.cuda() for k, v in inputs.items()}
    inputs_for_generation["web_attention_mask"] = None
    inputs_for_generation["html_tree"] = TreeBuilder(processor.tokenizer)
    inputs_for_generation["html_tree"].web_attention_mask = inputs_for_generation["web_attention_mask"]

    generated_ids = model.generate(
        **inputs_for_generation, bad_words_ids=BAD_WORDS_IDS, max_length=2048,
        num_return_sequences=1, do_sample=False
    )
    generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)[0]

    with open(html_path, 'w') as wp:
        wp.write(generated_text)


if __name__ == '__main__':
    inference_vlm_websight('examples/test-495.png', 'examples/example-495.html')
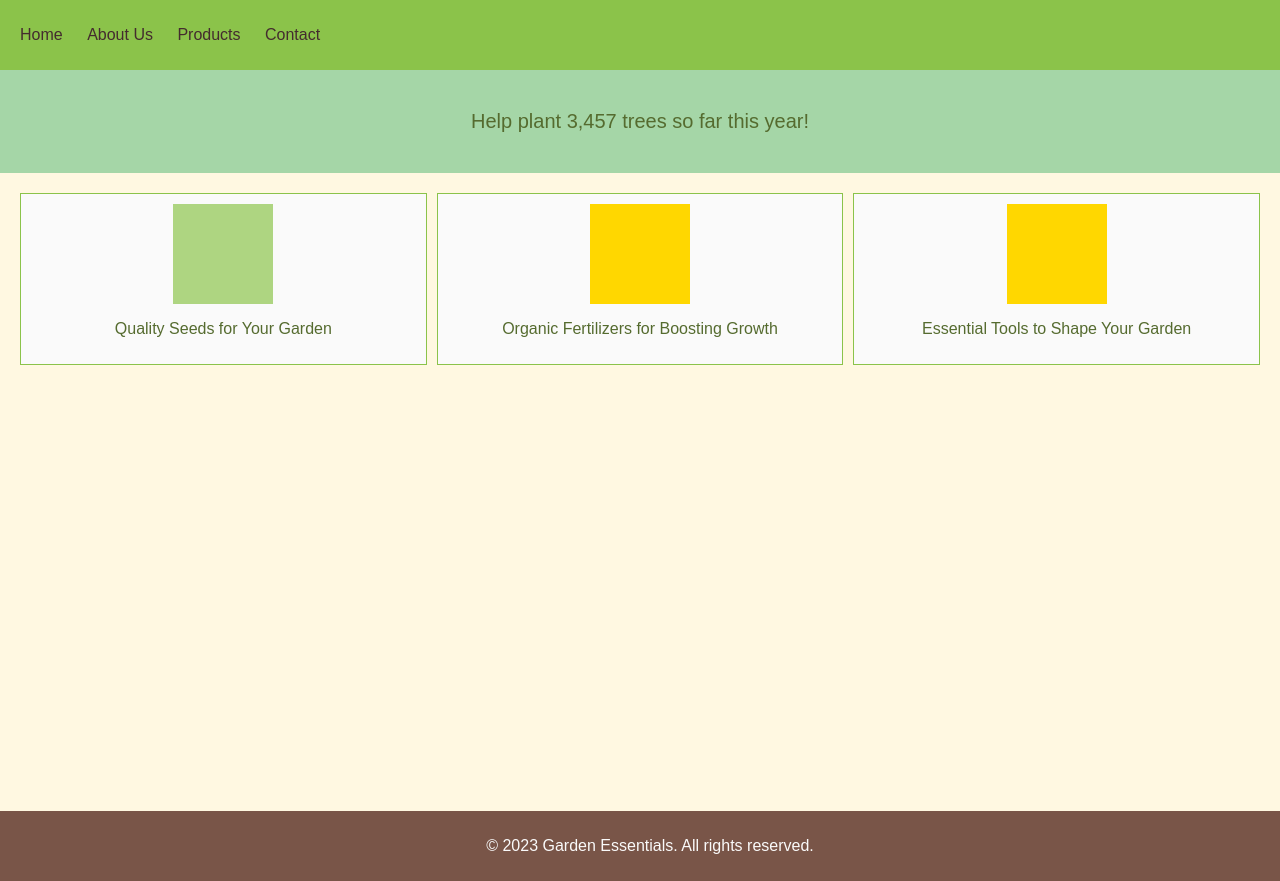
Render the HTML, or preview the HTML to check the correctness:
@misc{liang2024wafflemultimodalmodelautomated,
      title={WAFFLE: Multi-Modal Model for Automated Front-End Development},
      author={Shanchao Liang and Nan Jiang and Shangshu Qian and Lin Tan},
      year={2024},
      eprint={2410.18362},
      archivePrefix={arXiv},
      primaryClass={cs.SE},
      url={https://arxiv.org/abs/2410.18362},
}
The model is built on top of VLM_WebSight_finetuned. As such, users should comply with the licenses of these models.
The DoRA weights we trained are integrated with the original model's weights to produce the final model. We release the final model's weights under the Apache-2.0 license.