
Downloads · 30 days
0
louisbrulenaudet/docutron
docutron is a feature extraction model from louisbrulenaudet. Use it when you need embeddings to search or compare text. The card lists the license as apache-2.0.
Docutron is a tool designed to facilitate the extraction of relevant information from legal documents, enabling professionals to create datasets for fine-tuning language models (LLM) for specific legal domains.
Downloads · 30 days
0
Access
Public
Updated Jan 2, 2024
Repo size
330 MB
Likes
1
Public
Click a slice to open those files.
.pth330 MB · 100%
From the Hugging Face model README
Docutron is a tool designed to facilitate the extraction of relevant information from legal documents, enabling professionals to create datasets for fine-tuning language models (LLM) for specific legal domains.
Legal professionals often deal with vast amounts of text data in various formats, including legal documents, contracts, regulations, and case law. Extracting structured information from these documents is a time-consuming and error-prone task. Docutron simplifies this process by using state-of-the-art computer vision and natural language processing techniques to automate the extraction of key information from legal documents.
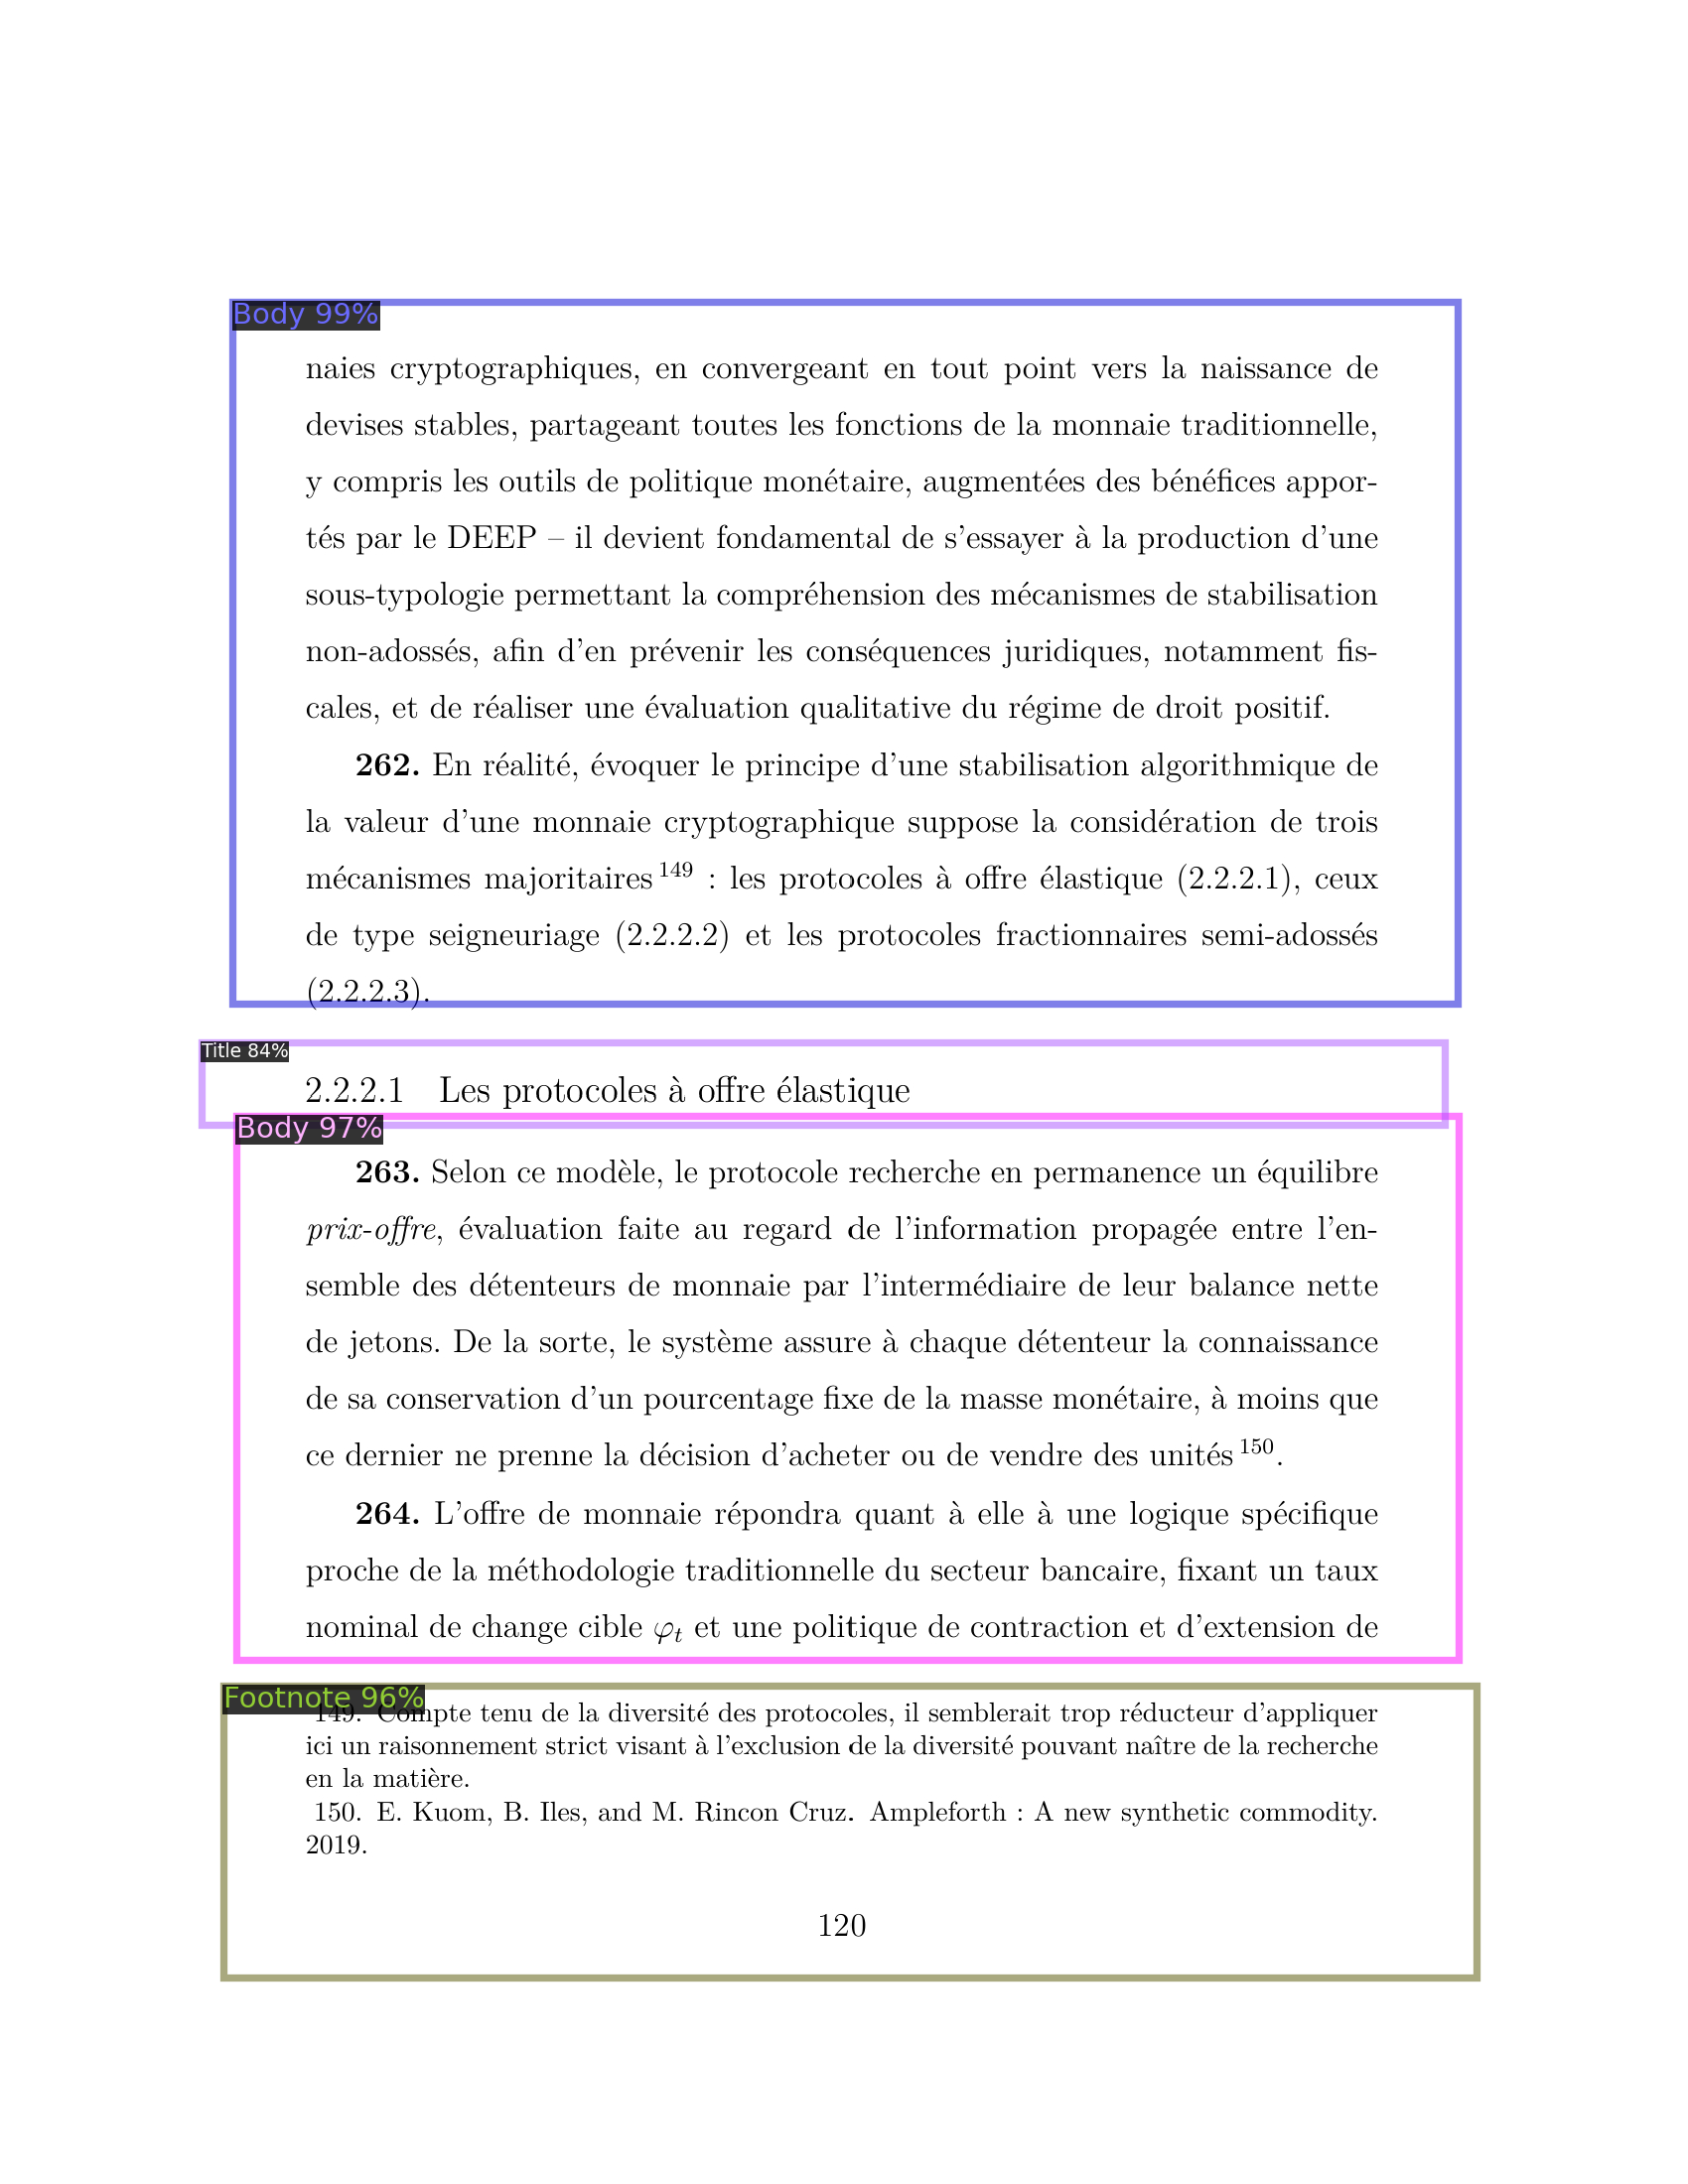
Whether you are delving into contract analysis, legal document summarization, or any other legal task that demands meticulous data extraction, Docutron stands ready to be your reliable technical companion, simplifying complex legal workflows and opening doors to new possibilities in legal research and analysis.
If you use this code in your research, please use the following BibTeX entry.
@misc{louisbrulenaudet2023,
  author = {Louis Brulé Naudet},
  title = {Docutron Toolkit: detection and segmentation analysis for legal data extraction over documents},
  howpublished = {\url{https://github.com/louisbrulenaudet/docutron}},
  year = {2023}
}
If you have any feedback, please reach out at [email protected].