
Downloads · 30 days
9
1% of all-time downloads
lnxdx/Wav2Vec2-Large-XLSR-Persian-ShEMO
Wav2Vec2-Large-XLSR-Persian-ShEMO is a automatic speech recognition model from lnxdx. Use it when you need speech turned into text. It is set up for transformers.
should probably proofread and complete it, then remove this comment. --
Downloads · 30 days
9
1% of all-time downloads
All-time downloads
1.5K
Public
Parameters
315M
1.3 GB on disk
Likes
2
Public
Click a slice to open those files.
.safetensors1.3 GB · 100%
From the Hugging Face model README
This model is a fine-tuned version of masoudmzb/wav2vec2-xlsr-multilingual-53-fa on the ShEMO dataset for speech recognition in Persian (Farsi). When using this model, make sure that your speech input is sampled at 16 kHz.
It achieves the following results:
| Checkpoint Name | WER on ShEMO dev set | WER on Common Voice 13 test set | Max :) |
|---|---|---|---|
| m3hrdadfi/wav2vec2-large-xlsr-persian-v3 | 46.55 | 17.43 | 46.55 |
| m3hrdadfi/wav2vec2-large-xlsr-persian-shemo | 7.42 | 33.88 | 33.88 |
| masoudmzb/wav2vec2-xlsr-multilingual-53-fa | 56.54 | 24.68 | 56.54 |
| This checkpoint | 32.85 | 19.21 | 32.85 |
As you can see, my model performs better in maximum case :D
The following hyperparameters were used during training:
You may need gradient_accumulation because you need more batch size.
| Training Loss | Epoch | Step | Validation Loss | Wer |
|---|---|---|---|---|
| 1.8553 | 0.62 | 100 | 1.4126 | 0.4866 |
| 1.4083 | 1.25 | 200 | 1.0428 | 0.4366 |
| 1.1718 | 1.88 | 300 | 0.8683 | 0.4127 |
| 0.9919 | 2.5 | 400 | 0.7921 | 0.3919 |
| 0.9493 | 3.12 | 500 | 0.7676 | 0.3744 |
| 0.9414 | 3.75 | 600 | 0.7247 | 0.3695 |
| 0.8897 | 4.38 | 700 | 0.7202 | 0.3598 |
| 0.8716 | 5.0 | 800 | 0.7096 | 0.3546 |
| 0.8467 | 5.62 | 900 | 0.7023 | 0.3499 |
| 0.8227 | 6.25 | 1000 | 0.6994 | 0.3411 |
| 0.855 | 6.88 | 1100 | 0.6883 | 0.3432 |
| 0.8457 | 7.5 | 1200 | 0.6773 | 0.3426 |
| 0.7614 | 8.12 | 1300 | 0.6913 | 0.3344 |
| 0.8127 | 8.75 | 1400 | 0.6827 | 0.3335 |
| 0.8443 | 9.38 | 1500 | 0.6725 | 0.3356 |
| 0.7548 | 10.0 | 1600 | 0.6759 | 0.3318 |
| 0.7839 | 10.62 | 1700 | 0.6773 | 0.3286 |
| 0.7912 | 11.25 | 1800 | 0.6748 | 0.3286 |
| 0.8238 | 11.88 | 1900 | 0.6735 | 0.3297 |
| 0.7618 | 12.5 | 2000 | 0.6728 | 0.3286 |
Several models with differet hyperparameters were trained. The following figures show the training process for three of them.
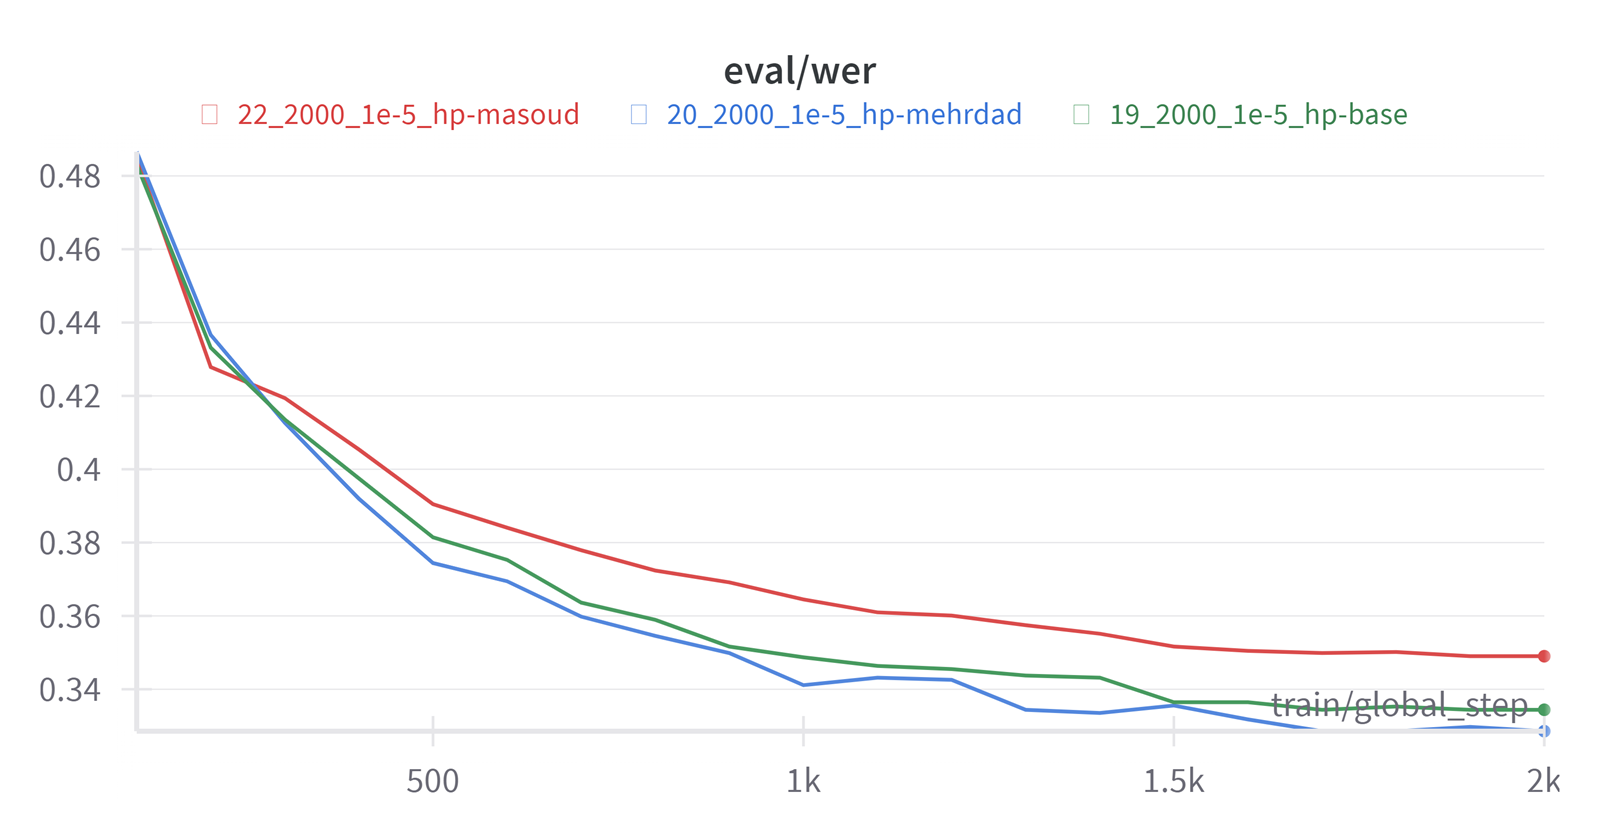
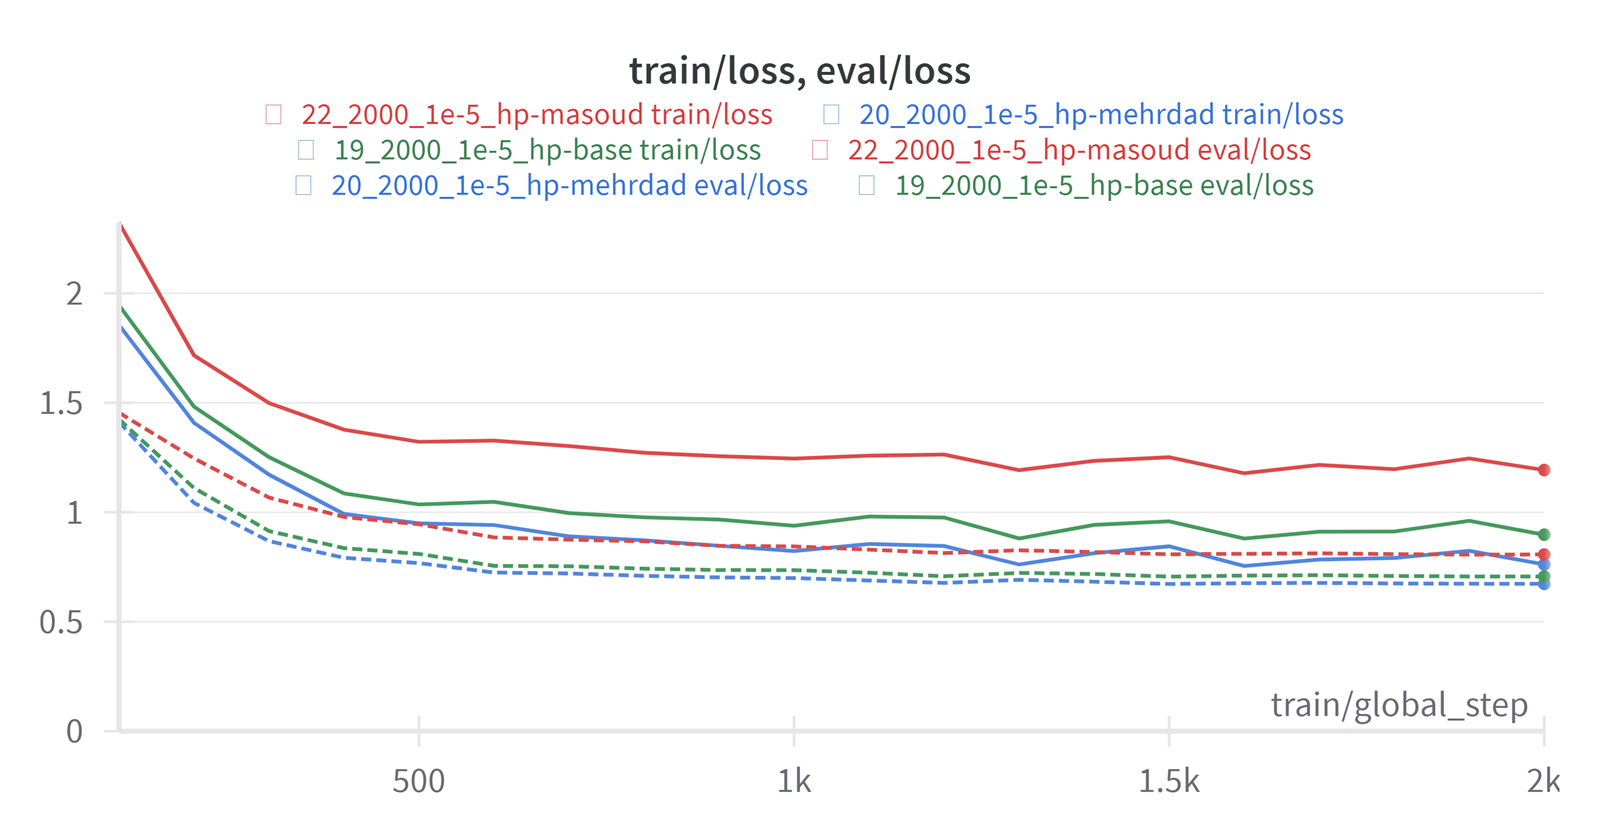 20_2000_1e-5_hp-mehrdad is the current model (lnxdx/Wav2Vec2-Large-XLSR-Persian-ShEMO) and it's hyperparameters are:
model = Wav2Vec2ForCTC.from_pretrained(
    model_name_or_path if not last_checkpoint else last_checkpoint,
    # hp-mehrdad: Hyperparams of 'm3hrdadfi/wav2vec2-large-xlsr-persian-v3'
    attention_dropout = 0.05316,
    hidden_dropout    = 0.01941,
    feat_proj_dropout = 0.01249,
    mask_time_prob    = 0.04529,
    layerdrop         = 0.01377,
    ctc_loss_reduction = 'mean',
    ctc_zero_infinity = True,
)
The hyperparameters of 19_2000_1e-5_hp-base are:
model = Wav2Vec2ForCTC.from_pretrained(
    model_name_or_path if not last_checkpoint else last_checkpoint,
    # hp-base: Hyperparams simmilar to ('facebook/wav2vec2-large-xlsr-53' or 'facebook/wav2vec2-xls-r-300m')
    attention_dropout = 0.1,
    hidden_dropout    = 0.1,
    feat_proj_dropout = 0.1,
    mask_time_prob    = 0.075,
    layerdrop         = 0.1,
    ctc_loss_reduction = 'mean',
    ctc_zero_infinity = True,
)
And the hyperparameters of 22_2000_1e-5_hp-masoud are:
model = Wav2Vec2ForCTC.from_pretrained(
    model_name_or_path if not last_checkpoint else last_checkpoint,
    # hp-masoud: Hyperparams of 'masoudmzb/wav2vec2-xlsr-multilingual-53-fa'
	attention_dropout = 0.2,
	hidden_dropout    = 0.2,
	feat_proj_dropout = 0.1,
	mask_time_prob    = 0.2,
	layerdrop         = 0.2,
	ctc_loss_reduction = 'mean',
	ctc_zero_infinity = True,
)
Learning rate is 1e-5 for all three models.
As you can see this model performs better with WER metric on validation(evaluation) set.
📒 The script used for training can be found here.
📒 The script used for evaluating on ShEMO and Common Voice can be found here.
Check out this blog for more information.
If you have any technical question regarding the model, pretraining, code or publication, please create an issue in the repository. This is the best way to reach us.
TO DO!
Fine-tuned with ❤️ without ☕︎