
Downloads · 30 days
532
0% of all-time downloads
lllyasviel/sd-controlnet-mlsd
sd-controlnet-mlsd is a image-to-image model from lllyasviel. Use it when you need one image transformed into another. It is set up for diffusers. The card lists the license as openrail.
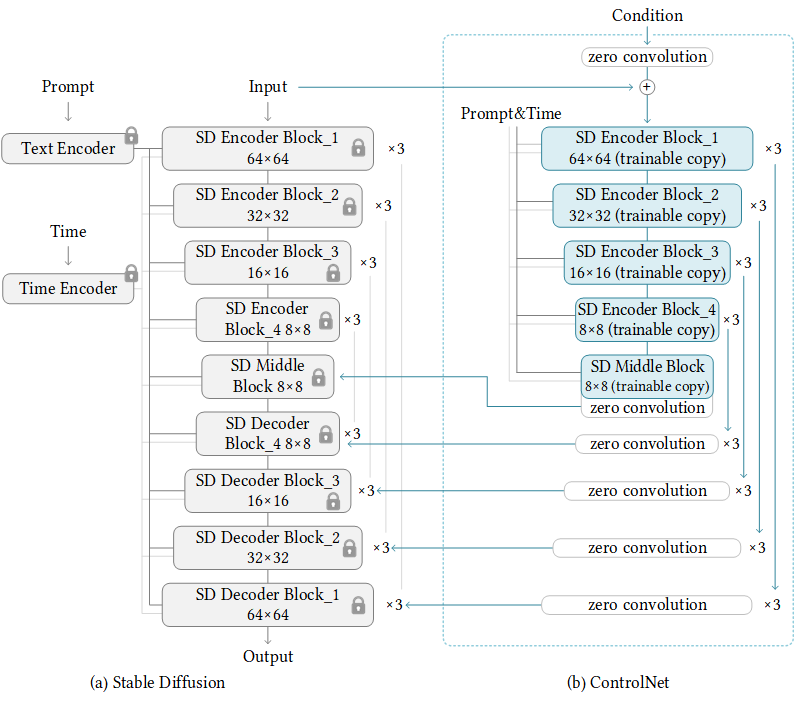
ControlNet is a neural network structure to control diffusion models by adding extra conditions. This checkpoint corresponds to the ControlNet conditioned on M-LSD straight line detection.
Downloads · 30 days
532
0% of all-time downloads
All-time downloads
215K
Public
Parameters
361M
9.8 GB on disk
Likes
48
Public
Click a slice to open those files.
.bin1.4 GB · 50%
From the Hugging Face model README
ControlNet is a neural network structure to control diffusion models by adding extra conditions. This checkpoint corresponds to the ControlNet conditioned on M-LSD straight line detection.
It can be used in combination with Stable Diffusion.
Developed by: Lvmin Zhang, Maneesh Agrawala
Model type: Diffusion-based text-to-image generation model
Language(s): English
License: The CreativeML OpenRAIL M license is an Open RAIL M license, adapted from the work that BigScience and the RAIL Initiative are jointly carrying in the area of responsible AI licensing. See also the article about the BLOOM Open RAIL license on which our license is based.
Resources for more information: GitHub Repository, Paper.
Cite as:
@misc{zhang2023adding, title={Adding Conditional Control to Text-to-Image Diffusion Models}, author={Lvmin Zhang and Maneesh Agrawala}, year={2023}, eprint={2302.05543}, archivePrefix={arXiv}, primaryClass={cs.CV} }
Controlnet was proposed in Adding Conditional Control to Text-to-Image Diffusion Models by Lvmin Zhang, Maneesh Agrawala.
The abstract reads as follows:
We present a neural network structure, ControlNet, to control pretrained large diffusion models to support additional input conditions. The ControlNet learns task-specific conditions in an end-to-end way, and the learning is robust even when the training dataset is small (< 50k). Moreover, training a ControlNet is as fast as fine-tuning a diffusion model, and the model can be trained on a personal devices. Alternatively, if powerful computation clusters are available, the model can scale to large amounts (millions to billions) of data. We report that large diffusion models like Stable Diffusion can be augmented with ControlNets to enable conditional inputs like edge maps, segmentation maps, keypoints, etc. This may enrich the methods to control large diffusion models and further facilitate related applications.
The authors released 8 different checkpoints, each trained with Stable Diffusion v1-5 on a different type of conditioning:
| Model Name | Control Image Overview | Control Image Example | Generated Image Example |
|---|---|---|---|
| lllyasviel/sd-controlnet-canny<br/> Trained with canny edge detection | A monochrome image with white edges on a black background. | <a href="https://huggingface.co/takuma104/controlnet_dev/blob/main/gen_compare/control_images/converted/control_bird_canny.png"><img width="64" style="margin:0;padding:0;" src="https://huggingface.co/takuma104/controlnet_dev/resolve/main/gen_compare/control_images/converted/control_bird_canny.png"/></a> | <a href="https://huggingface.co/takuma104/controlnet_dev/resolve/main/gen_compare/output_images/diffusers/output_bird_canny_1.png"><img width="64" src="https://huggingface.co/takuma104/controlnet_dev/resolve/main/gen_compare/output_images/diffusers/output_bird_canny_1.png"/></a> |
| lllyasviel/sd-controlnet-depth<br/> Trained with Midas depth estimation | A grayscale image with black representing deep areas and white representing shallow areas. | <a href="https://huggingface.co/takuma104/controlnet_dev/blob/main/gen_compare/control_images/converted/control_vermeer_depth.png"><img width="64" src="https://huggingface.co/takuma104/controlnet_dev/resolve/main/gen_compare/control_images/converted/control_vermeer_depth.png"/></a> | <a href="https://huggingface.co/takuma104/controlnet_dev/resolve/main/gen_compare/output_images/diffusers/output_vermeer_depth_2.png"><img width="64" src="https://huggingface.co/takuma104/controlnet_dev/resolve/main/gen_compare/output_images/diffusers/output_vermeer_depth_2.png"/></a> |
| lllyasviel/sd-controlnet-hed<br/> Trained with HED edge detection (soft edge) | A monochrome image with white soft edges on a black background. | <a href="https://huggingface.co/takuma104/controlnet_dev/blob/main/gen_compare/control_images/converted/control_bird_hed.png"><img width="64" src="https://huggingface.co/takuma104/controlnet_dev/resolve/main/gen_compare/control_images/converted/control_bird_hed.png"/></a> | <a href="https://huggingface.co/takuma104/controlnet_dev/resolve/main/gen_compare/output_images/diffusers/output_bird_hed_1.png"><img width="64" src="https://huggingface.co/takuma104/controlnet_dev/resolve/main/gen_compare/output_images/diffusers/output_bird_hed_1.png"/></a> |
| lllyasviel/sd-controlnet-mlsd<br/> Trained with M-LSD line detection | A monochrome image composed only of white straight lines on a black background. | <a href="https://huggingface.co/takuma104/controlnet_dev/blob/main/gen_compare/control_images/converted/control_room_mlsd.png"><img width="64" src="https://huggingface.co/takuma104/controlnet_dev/resolve/main/gen_compare/control_images/converted/control_room_mlsd.png"/></a> | <a href="https://huggingface.co/takuma104/controlnet_dev/resolve/main/gen_compare/output_images/diffusers/output_room_mlsd_0.png"><img width="64" src="https://huggingface.co/takuma104/controlnet_dev/resolve/main/gen_compare/output_images/diffusers/output_room_mlsd_0.png"/></a> |
| lllyasviel/sd-controlnet-normal<br/> Trained with normal map | A normal mapped image. | <a href="https://huggingface.co/takuma104/controlnet_dev/blob/main/gen_compare/control_images/converted/control_human_normal.png"><img width="64" src="https://huggingface.co/takuma104/controlnet_dev/resolve/main/gen_compare/control_images/converted/control_human_normal.png"/></a> | <a href="https://huggingface.co/takuma104/controlnet_dev/resolve/main/gen_compare/output_images/diffusers/output_human_normal_1.png"><img width="64" src="https://huggingface.co/takuma104/controlnet_dev/resolve/main/gen_compare/output_images/diffusers/output_human_normal_1.png"/></a> |
| lllyasviel/sd-controlnet_openpose<br/> Trained with OpenPose bone image | A OpenPose bone image. | <a href="https://huggingface.co/takuma104/controlnet_dev/blob/main/gen_compare/control_images/converted/control_human_openpose.png"><img width="64" src="https://huggingface.co/takuma104/controlnet_dev/resolve/main/gen_compare/control_images/converted/control_human_openpose.png"/></a> | <a href="https://huggingface.co/takuma104/controlnet_dev/resolve/main/gen_compare/output_images/diffusers/output_human_openpose_0.png"><img width="64" src="https://huggingface.co/takuma104/controlnet_dev/resolve/main/gen_compare/output_images/diffusers/output_human_openpose_0.png"/></a> |
| lllyasviel/sd-controlnet_scribble<br/> Trained with human scribbles | A hand-drawn monochrome image with white outlines on a black background. | <a href="https://huggingface.co/takuma104/controlnet_dev/blob/main/gen_compare/control_images/converted/control_vermeer_scribble.png"><img width="64" src="https://huggingface.co/takuma104/controlnet_dev/resolve/main/gen_compare/control_images/converted/control_vermeer_scribble.png"/></a> | <a href="https://huggingface.co/takuma104/controlnet_dev/resolve/main/gen_compare/output_images/diffusers/output_vermeer_scribble_0.png"><img width="64" src="https://huggingface.co/takuma104/controlnet_dev/resolve/main/gen_compare/output_images/diffusers/output_vermeer_scribble_0.png"/></a> |
| lllyasviel/sd-controlnet_seg<br/>Trained with semantic segmentation | An ADE20K's segmentation protocol image. | <a href="https://huggingface.co/takuma104/controlnet_dev/blob/main/gen_compare/control_images/converted/control_room_seg.png"><img width="64" src="https://huggingface.co/takuma104/controlnet_dev/resolve/main/gen_compare/control_images/converted/control_room_seg.png"/></a> | <a href="https://huggingface.co/takuma104/controlnet_dev/resolve/main/gen_compare/output_images/diffusers/output_room_seg_1.png"><img width="64" src="https://huggingface.co/takuma104/controlnet_dev/resolve/main/gen_compare/output_images/diffusers/output_room_seg_1.png"/></a> |
It is recommended to use the checkpoint with Stable Diffusion v1-5 as the checkpoint has been trained on it. Experimentally, the checkpoint can be used with other diffusion models such as dreamboothed stable diffusion.
Note: If you want to process an image to create the auxiliary conditioning, external dependencies are required as shown below:
$ pip install controlnet_aux
diffusers and related packages:$ pip pip install diffusers transformers accelerate
from PIL import Image
from diffusers import StableDiffusionControlNetPipeline, ControlNetModel, UniPCMultistepScheduler
import torch
from controlnet_aux import MLSDdetector
from diffusers.utils import load_image

mlsd = MLSDdetector.from_pretrained('lllyasviel/ControlNet')

image = load_image("https://huggingface.co/lllyasviel/sd-controlnet-mlsd/resolve/main/images/room.png")

image = mlsd(image)

controlnet = ControlNetModel.from_pretrained(
    "lllyasviel/sd-controlnet-mlsd", torch_dtype=torch.float16
)

pipe = StableDiffusionControlNetPipeline.from_pretrained(
    "runwayml/stable-diffusion-v1-5", controlnet=controlnet, safety_checker=None, torch_dtype=torch.float16
)

pipe.scheduler = UniPCMultistepScheduler.from_config(pipe.scheduler.config)

# Remove if you do not have xformers installed
# see https://huggingface.co/docs/diffusers/v0.13.0/en/optimization/xformers#installing-xformers
# for installation instructions
pipe.enable_xformers_memory_efficient_attention()

pipe.enable_model_cpu_offload()

image = pipe("room", image, num_inference_steps=20).images[0]

image.save('images/room_mlsd_out.png')
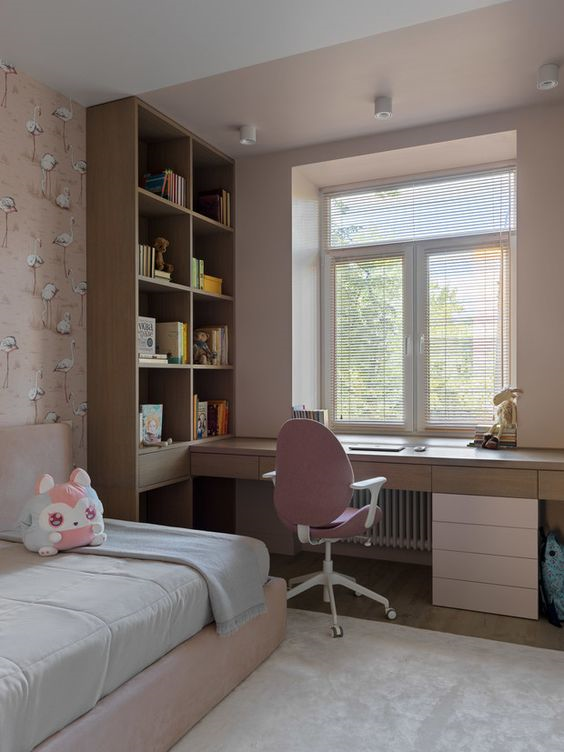
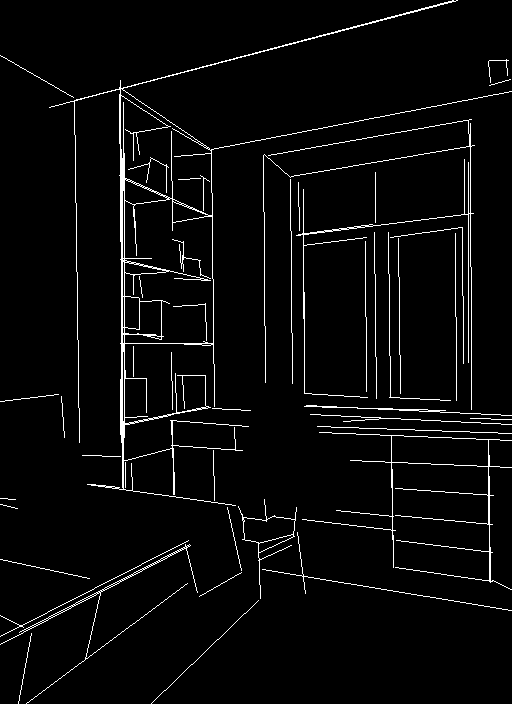
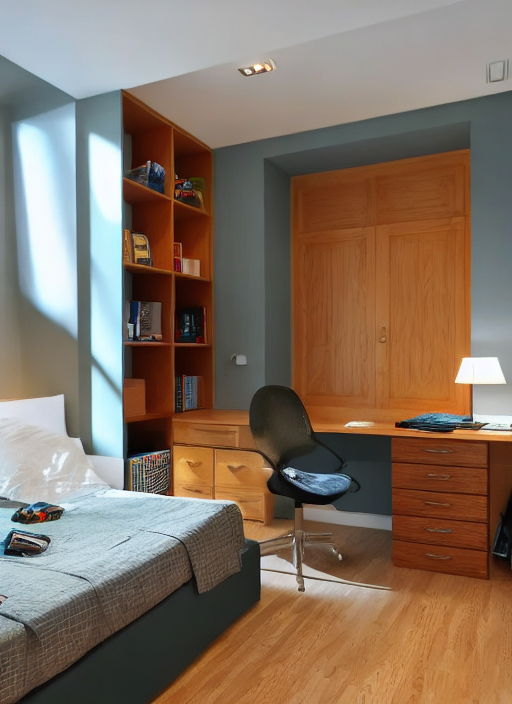
The hough line model was trained on 600k edge-image, caption pairs. The dataset was generated from Places2 using BLIP to generate text captions and a deep Hough transform to generate edge-images. The model was trained for 160 GPU-hours with Nvidia A100 80G using the Canny model as a base model.
For more information, please also have a look at the official ControlNet Blog Post.