
Downloads · 30 days
0
linagora/linto-asr-ar-tn-0.1
linto-asr-ar-tn-0.1 is a automatic speech recognition model from linagora. Use it when you need speech turned into text. The card lists the license as apache-2.0.
Downloads · 30 days
0
Access
Public
Updated Apr 11, 2025
Repo size
807 MB
Likes
16
Public
Click a slice to open those files.
.zip707 MB · 88%
From the Hugging Face model README

LinTO ASR Arabic Tunisia v0.1 is an Automatic Speech Recognition (ASR) model for the Tunisian dialect, with some capabilities of code-switching when some French or English words are used.
This repository includes two versions of the model and a Language model with ARPA format:
vosk-model: The original, comprehensive model.android-model: A lighter version with a simplified graph, optimized for deployment on Android devices or Raspberry Pi applications.lm_TN_CS.arpa.gz: A language model trained using SRILM on a dataset containing 4.5 million lines of text collected from various sources.The following table summarizes the performance of the LinTO ASR Arabic Tunisia v0.1 model on various considered test sets:
| Dataset | CER | WER |
|---|---|---|
| Youtube_TNScrapped_V1 | 25.39% | 37.51% |
| TunSwitchCS | 17.72% | 20.51% |
| TunSwitchTO | 11.13% | 22.54% |
| ApprendreLeTunisien | 11.81% | 23.27% |
| TARIC | 10.60% | 16.06% |
| OneStory | 1.53% | 4.47% |
The model was trained using the following GitHub repository: ASR_train_kaldi_tunisian
The model was trained using the following datasets:
You can download the model and its components directly from this repository using one of the following methods:
Method 1: Direct Download via Browser
Method 2: Using curl command
You can follow the command below:
sudo apt-get install curl

curl -L https://huggingface.co/linagora/linto-asr-ar-tn-0.1/resolve/main/vosk-model.zip --output vosk-model.zip
(or same with android-model.zip instead of vosk-model.zip)
Method 3: Cloning the Repository
You can clone the repository and create a zip file of the contents if needed:
sudo apt-get install git-lfs
git lfs install

git clone https://huggingface.co/linagora/linto-asr-ar-tn-0.1.git

cd linto-asr-ar-tn-0.1
This can be done in bash:
mkdir dir_for_zip_extract

unzip /path/to/model-name.zip -d dir_for_zip_extract
First, make sure to install the required dependencies:
pip install vosk
Then you can launch the inference script from this repository:
python inference.py <path/to/your/model> <path/to/your/audio/file.wav>
or use such a python code:
from vosk import Model, KaldiRecognizer
import wave
import json

model_dir = "path/to/your/model"
audio_file = "path/to/your/audio/file.wav"

model = Model(model_dir)

with wave.open(audio_file, "rb") as wf:
    if wf.getnchannels() != 1 or wf.getsampwidth() != 2 or wf.getcomptype() != "NONE":
        raise ValueError("Audio file must be WAV format mono PCM.")

    rec = KaldiRecognizer(model, wf.getframerate())
    rec.AcceptWaveform(wf.readframes(wf.getnframes()))
    res = rec.FinalResult()
    transcript = json.loads(res)["text"]
print(f"Transcript: {transcript}")
Here is an example of the transcription capabilities of the model:
<audio controls> <source src="https://huggingface.co/linagora/linto-asr-ar-tn-0.1/resolve/main/sample.wav" type="audio/wav"> </audio>Install required dependencies:
pip install vosk
pip install websockets
If not done, close the repostorory:
git clone https://huggingface.co/linagora/linto-asr-ar-tn-0.1.git
Then call the app.py script:
cd linto-asr-ar-tn-0.1/Demo-WebRTC

python3 app.py <model-path>
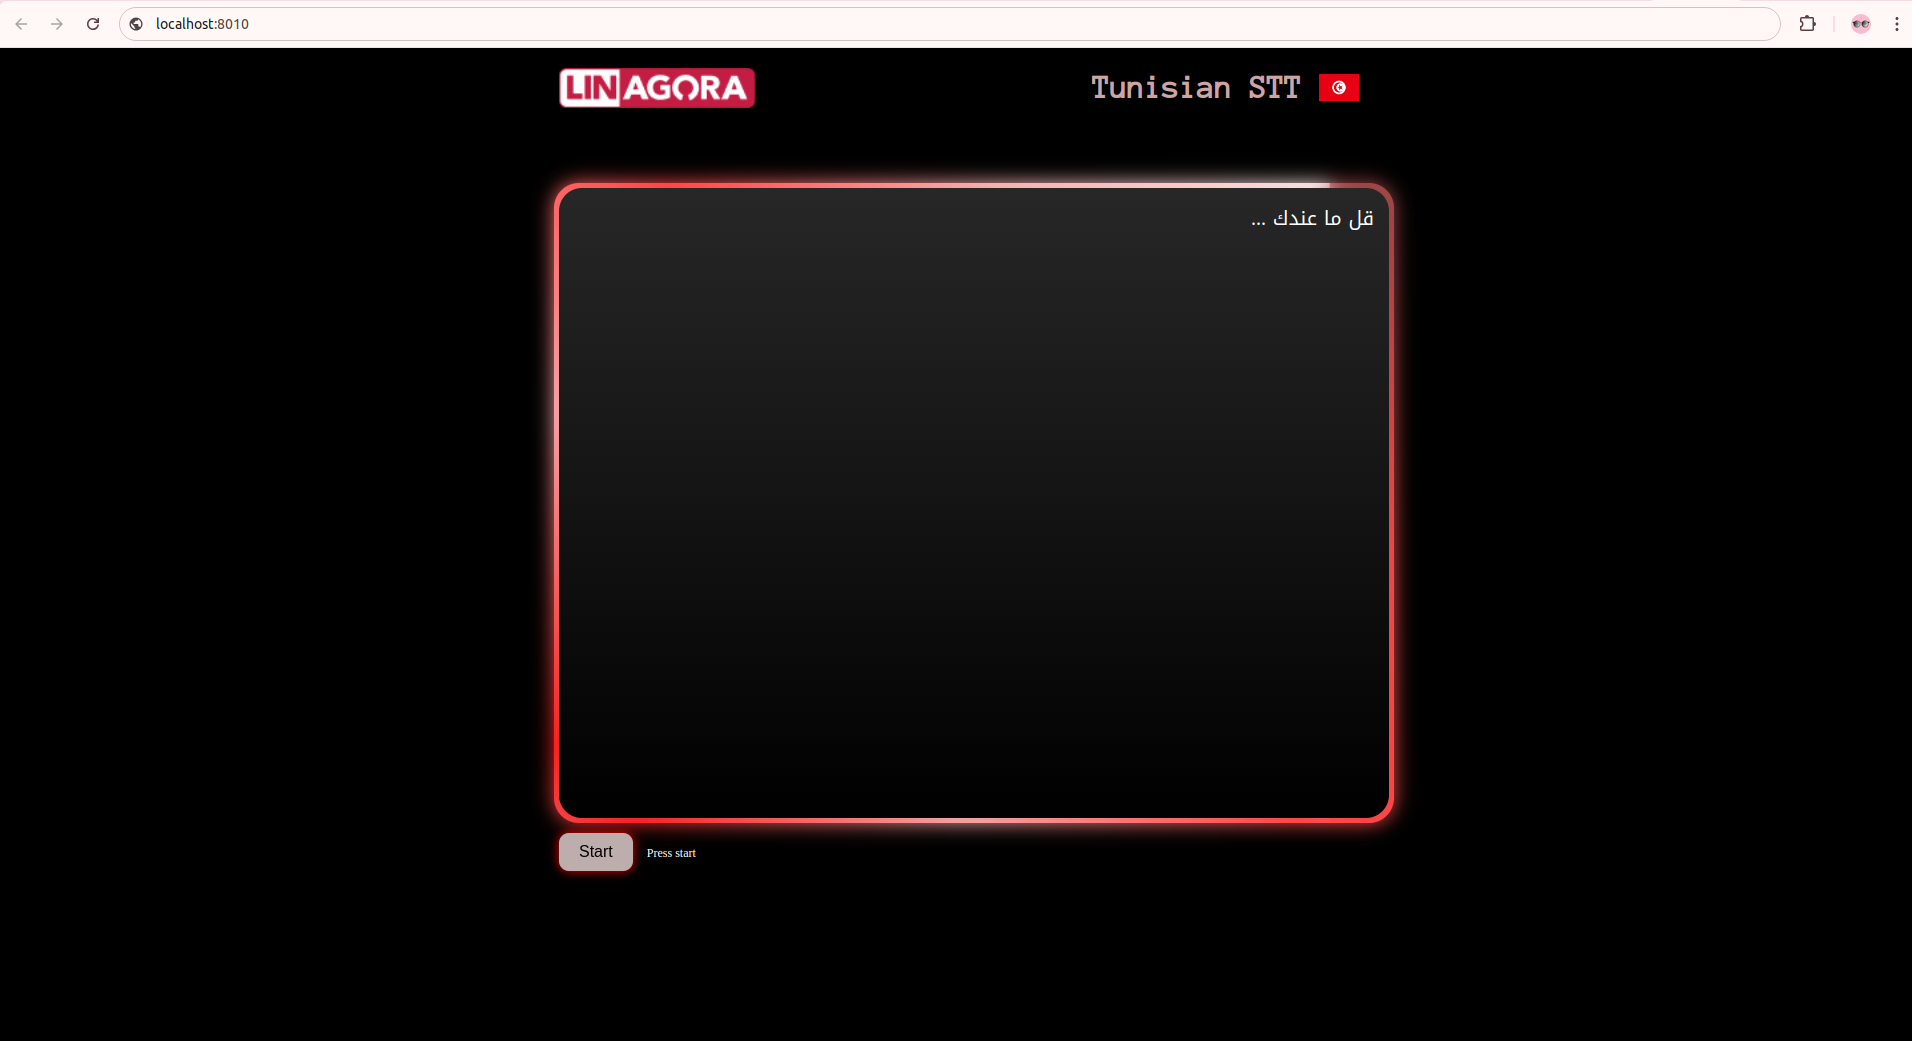
Access the web interface at: localhost:8010 Just start and speak.
Preview of the web app interface:
When using the LinTO ASR for Arabic Tunisian model, please cite the following paper (arxiv:2504.02604).
@misc{linagora2024Linto-tn,
  title = {LinTO Audio and Textual Datasets to Train and Evaluate Automatic Speech Recognition in Tunisian Arabic Dialect},
  author = {Hedi Naouara and Jérôme Louradour and Jean-Pierre Lorré},
  year = {2025},
  month = {March},
  eprint={2504.02604},
  archivePrefix={arXiv},
  primaryClass={cs.CL},
  note={Good Data Workshop, AAAI 2025},
  url={arxiv.org/abs/2504.02604},
}
