
Downloads · 30 days
19
17% of all-time downloads
lhca521/QWEN_IMAGE_nf4_w_AbliteratedTE_Diffusers
QWEN_IMAGE_nf4_w_AbliteratedTE_Diffusers is a text-to-image model from lhca521. Use it when you need an image from a text prompt. It is set up for diffusers. The card lists the license as apache-2.0.
<p align="center" <img src="https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen-Image/qwenimagelogo.png" width="200"/ <p
Downloads · 30 days
19
17% of all-time downloads
All-time downloads
113
Public
Parameters
10.5B
44.9 GB on disk
Likes
1
Public
Click a slice to open those files.
.safetensors44.9 GB · 100%
How the weights are stored.
U810.2B · 97%
From the Hugging Face model README
This repo contains a variant of QWEN's QWEN-IMAGE, the state-of-the-art generative model with extensive and (image/)text-to-image &/or instruction/control-editing capabilities. <br>
To make these cutting edge capabilities more accessible to those constrained to low-end consumer-grade hardware, we've quantized the DiT (Diffusion Transformer) component of Qwen-Image to the 4-bit NF4 format using the Bits&Bytes toolkit.<br>
This optimization was derived by us directly from the BF16 base model weights released on 08/04/2025, with no other mix-ins or modifications to the DiT component. <br>
NOTE: Install bitsandbytes prior to inference. <br>
QWEN-IMAGE is an open-weights customization-friendly frontier model released under the highly permissive Apache 2.0 license, welcoming unrestricted (within legal limits) commercial, experimental, artistic, academic, and other uses &/or modifications. <br>
To help highlight horizons of possibility broadened by the QWEN-IMAGE release, our quantization is bundled with an "Abliterated" (aka de-censored) finetune of Qwen2.5-VL 7B Instruct, QWEN-IMAGE model's sole conditioning encoder (of prompts, instructions, input images, controls, etc), as well as a powerful Vision-Language-Model in its own right. <br>
As such, our repo saddles a lean & prim NF4 DiT over the Qwen2.5-VL-7B-Abliterated-Caption-it by Prithiv Sakthi (aka prithivMLmods).
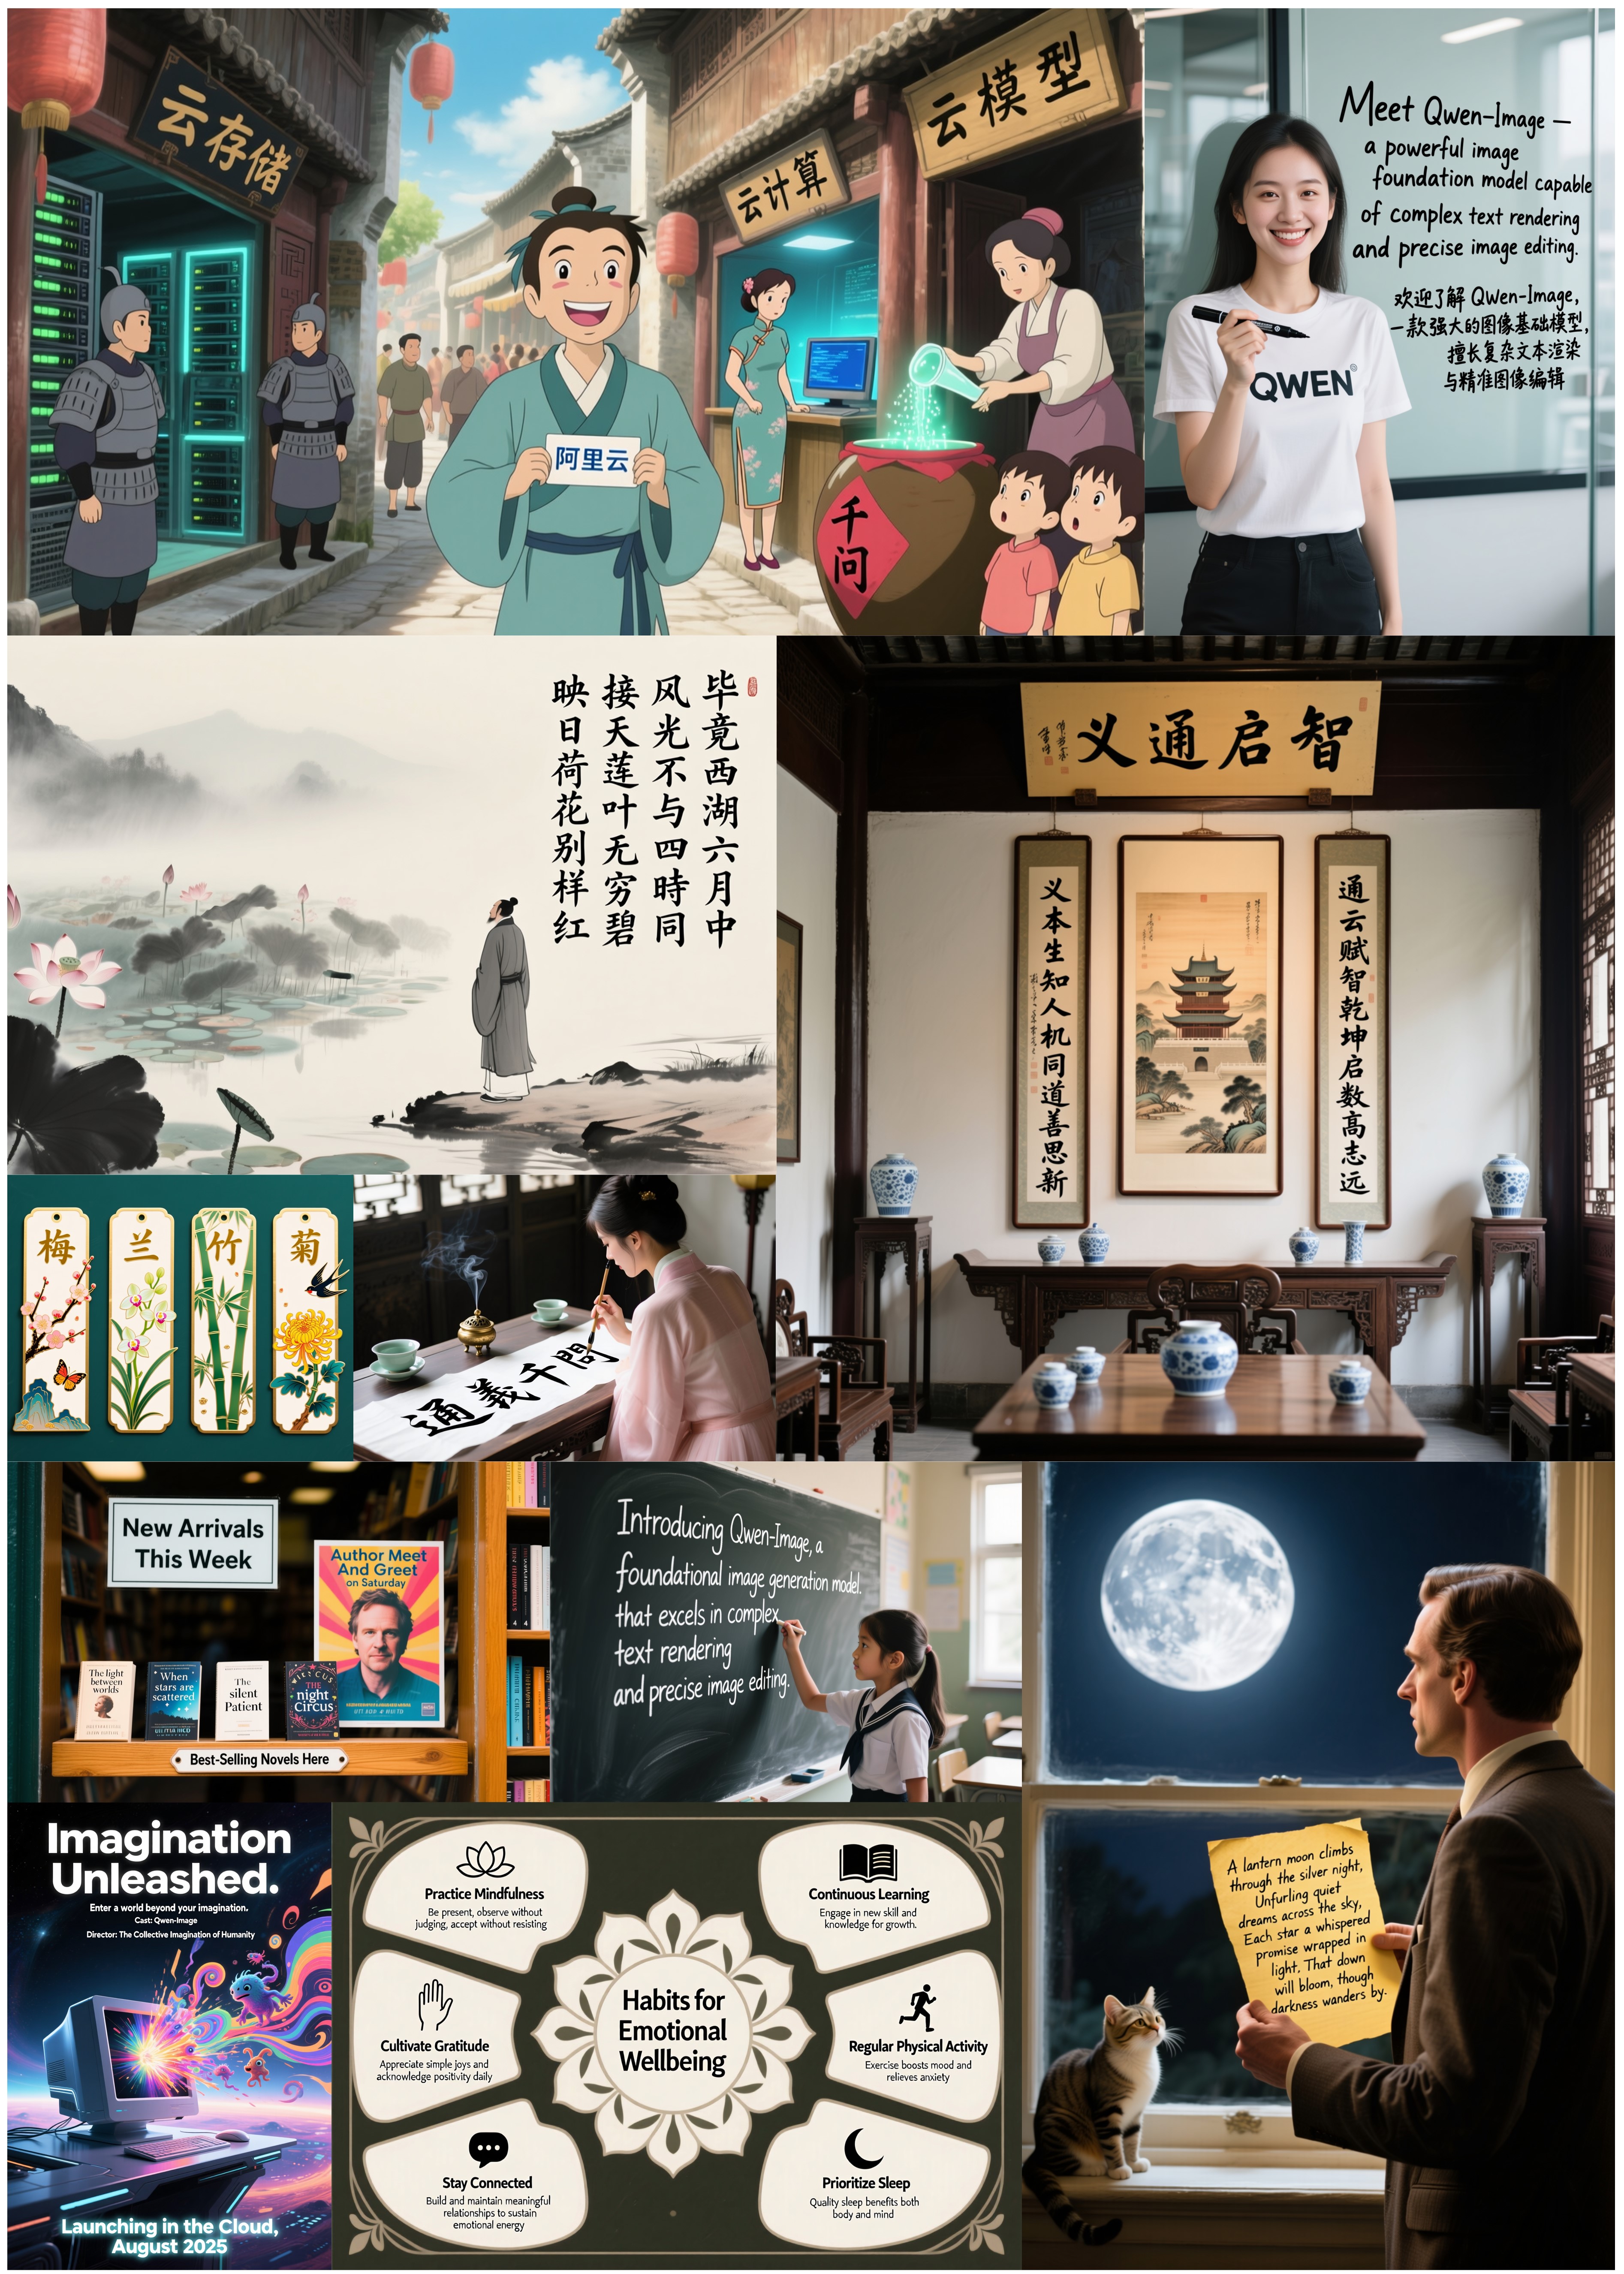
<p align="center"> <img src="https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen-Image/merge3.jpg" width="1600"/> <p>Do not be alarmed by the file warning from the ClamAV automated checker. <br>
It is a clear false positive. In assessing one of the typical Diffusers-adapted Safetensors shards (model weights), the checker reads:
The following viruses have been found: Pickle.Malware.SysAccess.sys.STACK_GLOBAL.UNOFFICIAL <br>
However, a Safetensors by its sheer design can not contain suchlike inserts. You may confirm for yourself thru HF's built-in weight/index viewer. <br>
So, to be sure, this repo does not contain any pickle checkpoints, or any other pickled data. <br>
This repo is formatted for usage with Diffusers (0.35.0.dev0+) & Transformers libraries, vis-a-vis associated pipelines & model component classes, such as the defaults listed in model_index.json (in this repo's root folder). <br>
Sourced/adapted from the original base model repo by QWEN.
EDIT:
We've confronted some issues with using the below pipeline. Will update once reliable adjustments are confirmed. <br>
from diffusers import DiffusionPipeline
import torch
import bitsandbytes
model_name = "AlekseyCalvin/QwenImage_nf4"
# Load the pipeline
if torch.cuda.is_available():
    torch_dtype = torch.bfloat16
    device = "cuda"
else:
    torch_dtype = torch.float32
    device = "cpu"
pipe = DiffusionPipeline.from_pretrained(model_name, torch_dtype=torch_dtype)
pipe = pipe.to(device)
positive_magic = [
    "en": "Ultra HD, 4K, cinematic composition." # for english prompt,
    "zh": "超清,4K,电影级构图" # for chinese prompt,
]
# Generate image
prompt = '''A coffee shop entrance features a chalkboard sign reading "Qwen Coffee 😊 $2 per cup," with a neon light beside it displaying "通义千问". Next to it hangs a poster showing a beautiful Chinese woman, and beneath the poster is written "π≈3.1415926-53589793-23846264-33832795-02384197". Ultra HD, 4K, cinematic composition'''
negative_prompt = " "
# Generate with different aspect ratios
aspect_ratios = {
    "1:1": (1328, 1328),
    "16:9": (1664, 928),
    "9:16": (928, 1664),
    "4:3": (1472, 1140),
    "3:4": (1140, 1472)
}
width, height = aspect_ratios["16:9"]
image = pipe(
    prompt=prompt + positive_magic["en"],
    negative_prompt=negative_prompt,
    width=width,
    height=height,
    num_inference_steps=50,
    true_cfg_scale=4.0,
    generator=torch.Generator(device="cuda").manual_seed(42)
).images[0]
image.save("example.png")


@article{qwen-image,
    title={Qwen-Image Technical Report},
    author={Qwen Team},
    journal={arXiv preprint},
    year={2025}
}