
Downloads · 30 days
43
3% of all-time downloads
laicsiifes/swin-gportuguese-2
swin-gportuguese-2 is a image-to-text model from laicsiifes. Use it when you need a caption or text from an image. It is set up for transformers. The card lists the license as mit.
This model was presented in the paper Brazilian Portuguese Image Captioning with Transformers: A Study on Cross-Native-Translated Dataset.
Downloads · 30 days
43
3% of all-time downloads
All-time downloads
1.5K
Public
Parameters
240M
962 MB on disk
Likes
5
Public
Click a slice to open those files.
.safetensors962 MB · 100%
How the weights are stored.
F32240M · 100%
From the Hugging Face model README
This model was presented in the paper Brazilian Portuguese Image Captioning with Transformers: A Study on Cross-Native-Translated Dataset.
Swin-GPorTuguese-2 model trained for image captioning on Flickr30K Portuguese (translated version using Google Translator API) at resolution 224x224 and max sequence length of 1024 tokens.
The Swin-GPorTuguese-2 is a type of Vision Encoder Decoder which leverage the checkpoints of the Swin Transformer as encoder and the checkpoints of the GPorTuguese-2 as decoder. The encoder checkpoints come from Swin Trasnformer version pre-trained on ImageNet-1k at resolution 224x224.
The code used for training and evaluation is available at: https://github.com/laicsiifes/transformer-caption-ptbr. In this work, Swin-GPorTuguese-2 was trained together with its buddy Swin-DistilBERTimbau.
Other models evaluated did not perform as well as Swin-DistilBERTimbau and Swin-GPorTuguese-2, namely: DeiT-BERTimbau, DeiT-DistilBERTimbau, DeiT-GPorTuguese-2, Swin-BERTimbau, ViT-BERTimbau, ViT-DistilBERTimbau and ViT-GPorTuguese-2.
Use the code below to get started with the model.
import requests
from PIL import Image

from transformers import AutoTokenizer, AutoImageProcessor, VisionEncoderDecoderModel

# load a fine-tuned image captioning model and corresponding tokenizer and image processor
model = VisionEncoderDecoderModel.from_pretrained("laicsiifes/swin-gportuguese-2")
tokenizer = AutoTokenizer.from_pretrained("laicsiifes/swin-gportuguese-2")
image_processor = AutoImageProcessor.from_pretrained("laicsiifes/swin-gportuguese-2")

# preprocess an image
url = "http://images.cocodataset.org/val2014/COCO_val2014_000000458153.jpg"
image = Image.open(requests.get(url, stream=True).raw)
pixel_values = image_processor(image, return_tensors="pt").pixel_values

# generate caption
generated_ids = model.generate(pixel_values)
generated_text = tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
import matplotlib.pyplot as plt

# plot image with caption
plt.imshow(image)
plt.axis("off")
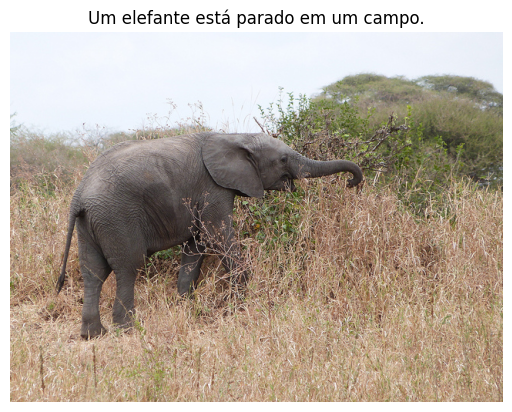
plt.title(generated_text)
plt.show()
The evaluation metrics CIDEr-D, BLEU@4, ROUGE-L, METEOR and BERTScore (using BERTimbau) are abbreviated as C, B@4, RL, M and BS, respectively.
| Model | Dataset | Eval. Split | C | B@4 | RL | M | BS |
|---|---|---|---|---|---|---|---|
| Swin-DistilBERTimbau | Flickr30K Portuguese | test | 66.73 | 24.65 | 39.98 | 44.71 | 72.30 |
| Swin-GPorTuguese-2 | Flickr30K Portuguese | test | 64.71 | 23.15 | 39.39 | 44.36 | 71.70 |
@inproceedings{bromonschenkel2024comparative,
  title={A Comparative Evaluation of Transformer-Based Vision Encoder-Decoder Models for Brazilian Portuguese Image Captioning},
  author={Bromonschenkel, Gabriel and Oliveira, Hil{\'a}rio and Paix{\~a}o, Thiago M},
  booktitle={2024 37th SIBGRAPI Conference on Graphics, Patterns and Images (SIBGRAPI)},
  pages={1--6},
  year={2024},
  organization={IEEE}
}