
Downloads · 30 days
33
7% of all-time downloads
kyujinpy/Tune-A-VideKO-disney
Tune-A-VideKO-disney is a text-to-video model from kyujinpy. Use it when you need video from a text prompt. It is set up for diffusers. The card lists the license as creativeml-openrail-m.
Downloads · 30 days
33
7% of all-time downloads
All-time downloads
472
Public
Repo size
12.6 GB
Likes
3
Public
Click a slice to open those files.
.bin5.5 GB · 100%
From the Hugging Face model README
Github: Kyujinpy/Tune-A-VideKO
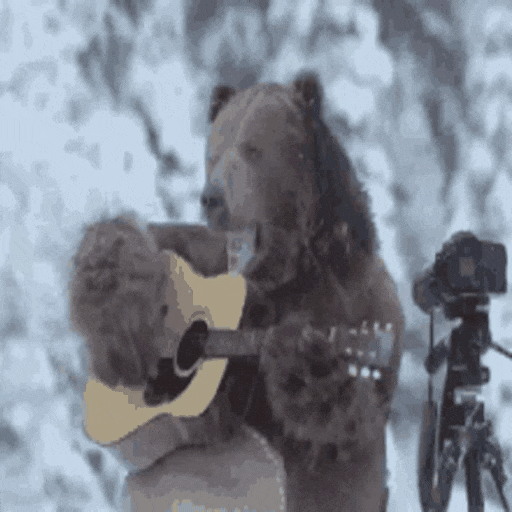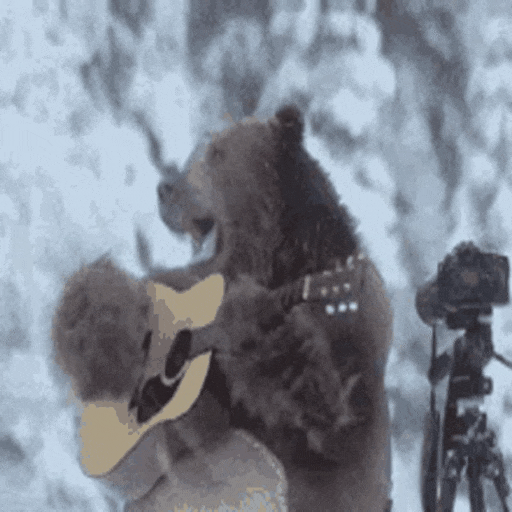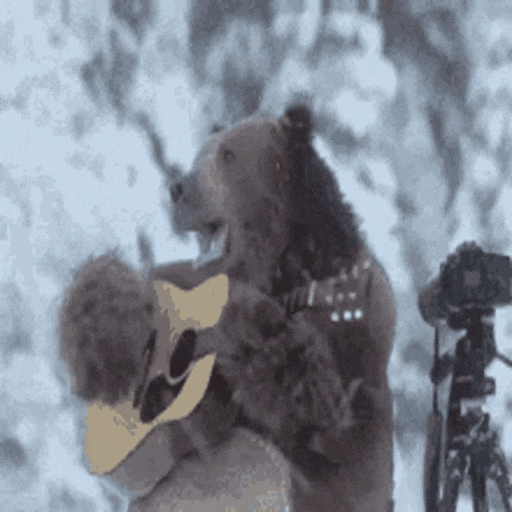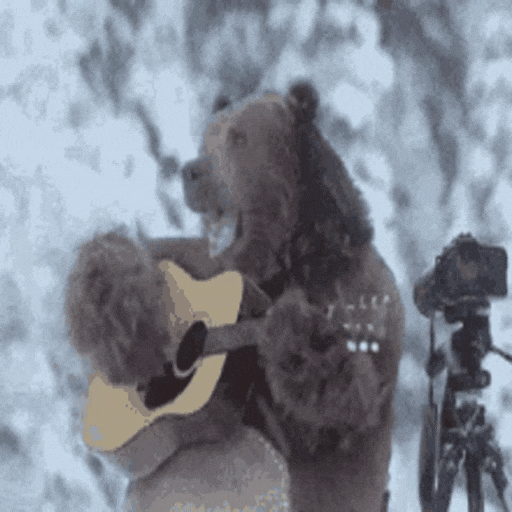
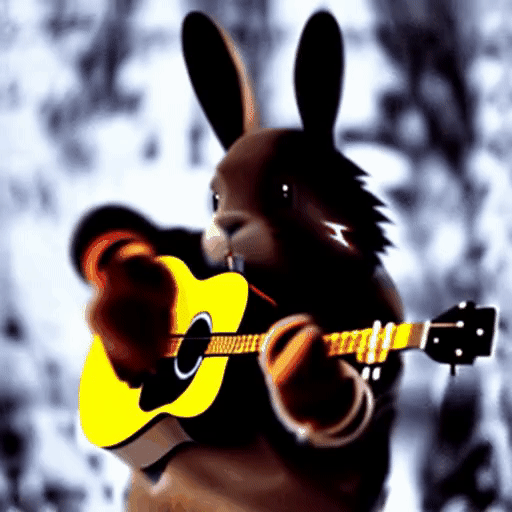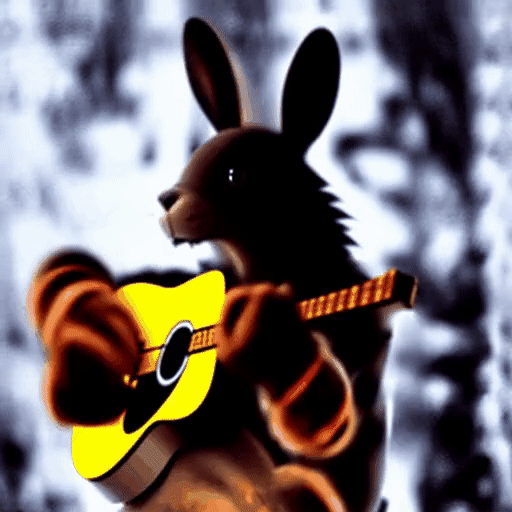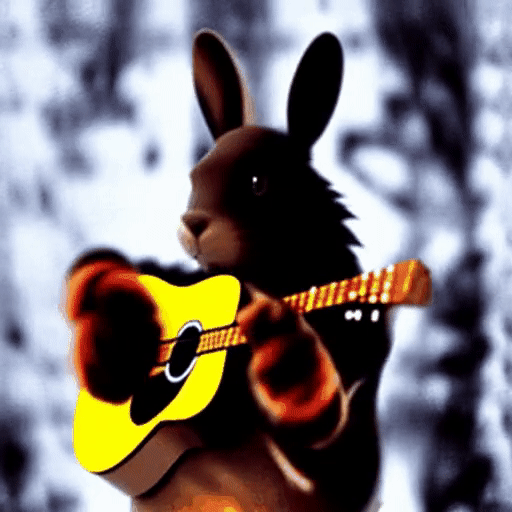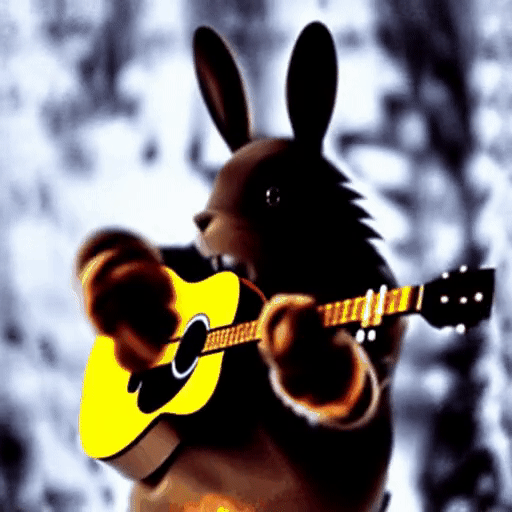 Test prompt: 토끼가 기타를 치고 있습니다, 모던한 디즈니 스타일
 Test prompt: 잘생긴 왕자가 기타를 치고 있습니다, 모던한 디즈니 스타일
 Test prompt: 사자가 기타를 치고 있습니다, 모던한 디즈니 스타일
Clone the github repo
git clone https://github.com/showlab/Tune-A-Video.git
Run inference code
from tuneavideo.pipelines.pipeline_tuneavideo import TuneAVideoPipeline
from tuneavideo.models.unet import UNet3DConditionModel
from tuneavideo.util import save_videos_grid
import torch

pretrained_model_path = "kyujinpy/KO-stable-diffusion-disney"
unet_model_path = "kyujinpy/Tune-A-VideKO-disney"
unet = UNet3DConditionModel.from_pretrained(unet_model_path, subfolder='unet', torch_dtype=torch.float16).to('cuda')
pipe = TuneAVideoPipeline.from_pretrained(pretrained_model_path, unet=unet, torch_dtype=torch.float16).to("cuda")
pipe.enable_xformers_memory_efficient_attention()

prompt = "사자가 기타를 치고 있습니다, 모던한 디즈니 스타일"
video = pipe(prompt, video_length=14, height=512, width=512, num_inference_steps=50, guidance_scale=7.5).videos

save_videos_grid(video, f"./{prompt}.gif")