
Downloads · 30 days
22
9% of all-time downloads
kousw/stablelm-gamma-7b-chatvector
stablelm-gamma-7b-chatvector is a text generation model from kousw. Use it when you need the model to write or continue text. It is set up for transformers. The card lists the license as apache-2.0.
Downloads · 30 days
22
9% of all-time downloads
All-time downloads
239
Public
Parameters
7.2B
14.5 GB on disk
Likes
1
Public
Click a slice to open those files.
.safetensors14.5 GB · 100%
From the Hugging Face model README
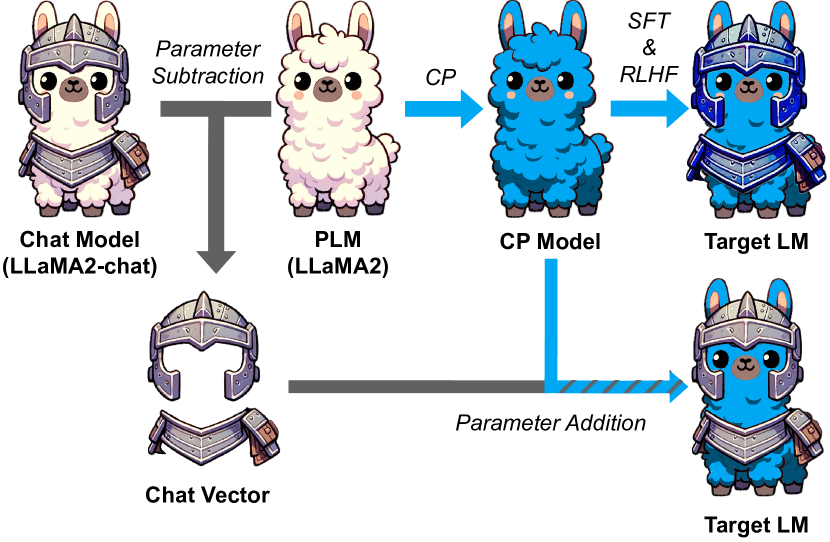
This model employs the technique described in "Chat Vector: A Simple Approach to Equip LLMs with Instruction Following and Model Alignment in New Languages".
It is based on stablelm-gamma-7b, a model that has not undergone instruction tuning, which was pre-trained using mistral-7b-v0.1.
To extract chat vectors, mistral-7b-v0.1 was "subtracted" from mistral-7b-instruct-v0.2.
By applying these extracted chat vectors to the non-instruction-tuned model stablelm-gamma-7b, an effect equivalent to instruction tuning is achieved.
from transformers import AutoModelForCausalLM, AutoTokenizer

device = "cuda" # the device to load the model onto

model = AutoModelForCausalLM.from_pretrained("kousw/stablelm-gamma-7b-chatvector")
tokenizer = AutoTokenizer.from_pretrained("kousw/stablelm-gamma-7b-chatvector")

messages = [
    {"role": "user", "content": "与えられたことわざの意味を小学生でも分かるように教えてください。"},
    {"role": "assistant", "content": "はい、どんなことわざでもわかりやすく答えます"},
    {"role": "user", "content": "情けは人のためならず"}
]

encodeds = tokenizer.apply_chat_template(messages, return_tensors="pt")

model_inputs = encodeds.to(device)
model.to(device)

generated_ids = model.generate(model_inputs, max_new_tokens=256, do_sample=True)
decoded = tokenizer.batch_decode(generated_ids)
print(decoded[0])