Downloads · 30 days
10
1% of all-time downloads
keras-io/video-transformers
video-transformers is a image classification model from keras-io. Use it when you need a label for an image. It is set up for tf-keras.
This model is intended to be used for the task of classifying videos. A video is an ordered sequence of frames. An individual frame of a video has spatial information whereas a sequence of video frames have temporal i…
Downloads · 30 days
10
1% of all-time downloads
All-time downloads
1.1K
Public
Repo size
103 MB
Likes
3
Public
Click a slice to open those files.
.data-00000-of-0000150.9 MB · 98%
From the Hugging Face model README
This model is intended to be used for the task of classifying videos.
A video is an ordered sequence of frames. An individual frame of a video has spatial information whereas a sequence of video frames have temporal information.
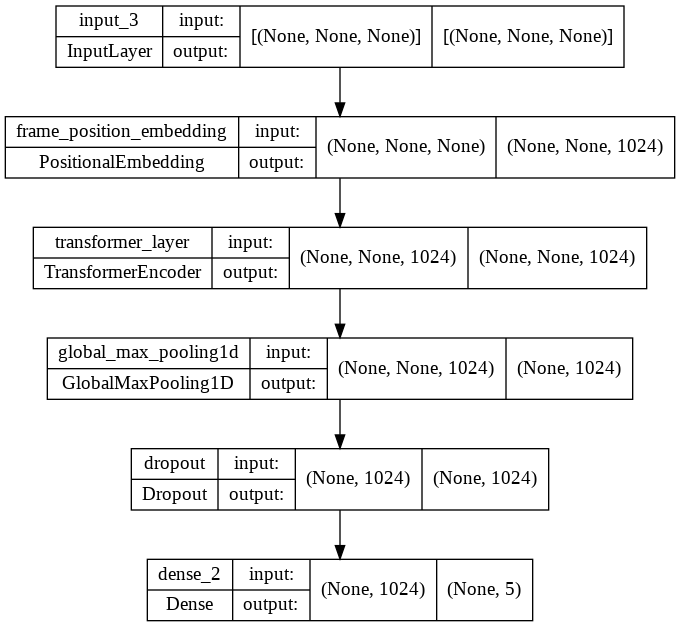
In order to capture both the spatial and temporal information present within a video, this model is made up of a hybrid architecture consisting of a Transformer Encoder operating on top of CNN feature maps. The CNN helps in capturing the spatial information present in the videos. For this purpose, a pretrained CNN (DenseNet121) is used to generate feature maps for the videos.
The temporal information corresponding to the ordering of the video frames can't be captured by the self-attention layers of a Transformer alone as they are order-agnostic by default. Therefore, this ordering related information has to be injected into the model with the help of a Positional Embedding.
The positional embeddings are added to the pre-computed CNN feature maps and finally fed as input to the Transformer Encoder.
The final model has nearly 4.23 million parameters. It works best with large datasets and longer training schedules.
The model can be used for the purpose of classifying videos belonging to different categories. Currently, the model recognises the following 5 classes:
| Classes |
|---|
| CricketShot |
| PlayingCello |
| Punch |
| ShavingBeard |
| TennisSwing |
The dataset used for training the model is a subsampled version of the UCF101 dataset. UCF101 is an action recognition dataset of realistic action videos collected from YouTube. The original UCF101 dataset has videos of 101 categories. However, the model was trained on a smaller subset of the original dataset which consisted of only 5 classes.
594 videos were used for training and 224 videos were used for testing.
The model is then trained using the following config:
| Training Config | Value |
|---|---|
| Optimizer | Adam |
| Loss Function | sparse_categorical_crossentropy |
| Metric | Accuracy |
| Epochs | 5 |
The model is tested on the test data post training achieving an accuracy of ~90%.
The following hyperparameters were used during training:
| Hyperparameters | Value |
|---|---|
| name | Adam |
| learning_rate | 0.0010000000474974513 |
| decay | 0.0 |
| beta_1 | 0.8999999761581421 |
| beta_2 | 0.9990000128746033 |
| epsilon | 1e-07 |
| amsgrad | False |
| training_precision | float32 |