Downloads · 30 days
33
7% of all-time downloads
keras-io/learning_to_tokenize_in_ViT
learning_to_tokenize_in_ViT is a image classification model from keras-io. Use it when you need a label for an image. It is set up for tf-keras.
The full credit goes to: Aritra Roy Gosthipaty, Sayak Paul
Downloads · 30 days
33
7% of all-time downloads
All-time downloads
480
Public
Repo size
10.1 MB
Likes
1
Public
Click a slice to open those files.
.data-00000-of-000015.4 MB · 54%
From the Hugging Face model README
The full credit goes to: Aritra Roy Gosthipaty, Sayak Paul
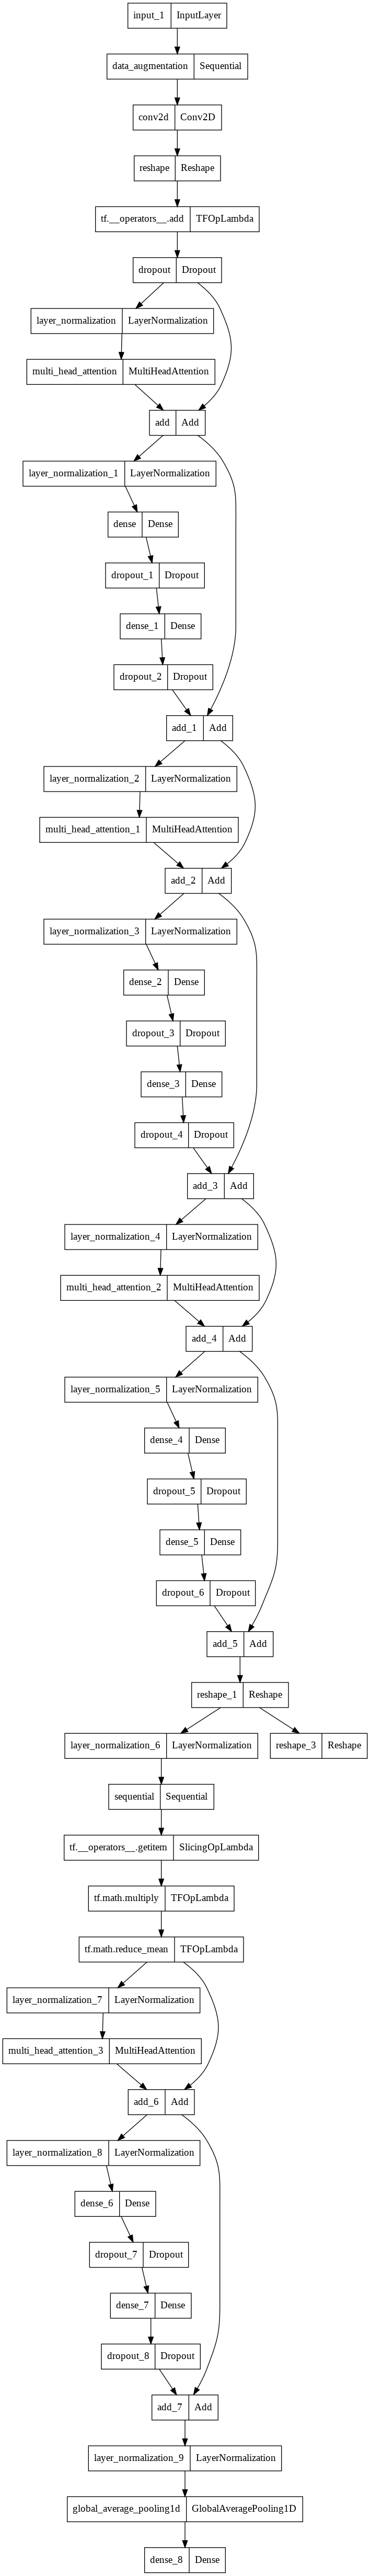
ViT and other Transformer based architectures break down images into patches. As we increase the resolution of the images, the number of patches increases as well. To tackle this, Ryoo et al. introduced a new module called TokenLearner which can help reduce the number of patches used. The full paper can be found here
The Dataset used here is CIFAR-10. The model used here is a mini ViT model with the TokenLearner module.
The following hyperparameters were used during training:
| Hyperparameters | Value |
|---|---|
| name | AdamW |
| learning_rate | 0.0010000000474974513 |
| decay | 0.0 |
| beta_1 | 0.8999999761581421 |
| beta_2 | 0.9990000128746033 |
| epsilon | 1e-07 |
| amsgrad | False |
| weight_decay | 9.999999747378752e-05 |
| exclude_from_weight_decay | None |
| training_precision | float32 |
After 20 Epocs, the test accuracy of the model is 55.9% and the Top 5 test accuracy is 95.06%