
Downloads · 30 days
36
9% of all-time downloads
keeeeenw/MicroLlava-Qwen3-0.6B-base-siglip2-so400m
MicroLlava-Qwen3-0.6B-base-siglip2-so400m is a visual question answering model from keeeeenw. Use it for the visual question answering task on the model card, and read the license before you ship it in a product. It is set up for transformers. The card lists the license as apache-2.0.
A compact yet competitive open-source vision-language model trained from scratch on a single RTX 4090.
Downloads · 30 days
36
9% of all-time downloads
All-time downloads
396
Public
Parameters
1B
2.9 GB on disk
Likes
1
Public
Click a slice to open those files.
.safetensors2.9 GB · 100%
How the weights are stored.
BF16596M · 58%
From the Hugging Face model README
A compact yet competitive open-source vision-language model trained from scratch on a single RTX 4090.
This is a ~1B parameter model that performs on par with the original LLaVA-1.5-7B, making it a serious candidate for visual question answering tasks—both for everyday users and researchers focused on efficient multimodal architectures.
It is also well suited for Edge AI applications, such as on-device visual question answering, thanks to its small size and fast inference performance.
keeeeenw/MicroLLaVA-Qwen3-0.6B-base-siglip2-so400m combines the strengths of:
Trained using a modified TinyLLaVA Factory fork, this model reaches 78.52% overall on VQAv2 test-dev, outperforming:
Zhang199/TinyLLaVA-Qwen2-0.5B-SigLIP: 72.33%LLaVA-1.5-7B: ~78.5%See https://huggingface.co/Zhang199/TinyLLaVA-Qwen2-0.5B-SigLIP#result for evaluation of the original models from TinyLLaVa and LLaVa authors.
Code:
# Tested with transformers: 4.55.2, torch: 2.8.0, and torchvision: 0.23.0
# Older versions of the transformers do not support qwen3 model.
# pip install transformers torch torchvision

from transformers import AutoTokenizer, AutoModelForCausalLM

hf_path = 'keeeeenw/MicroLlava-Qwen3-0.6B-base-siglip2-so400m'
model = AutoModelForCausalLM.from_pretrained(hf_path, trust_remote_code=True)
# model.cuda() # if no cuda is used, it takes ~78 seconds inference on my AMD 5950 CPU.
config = model.config
tokenizer = AutoTokenizer.from_pretrained(hf_path, use_fast=False, model_max_length = config.tokenizer_model_max_length,padding_side = config.tokenizer_padding_side)

prompt="What are the things I should be cautious about when I visit here?"
image_url="https://llava-vl.github.io/static/images/view.jpg"
output_text, genertaion_time = model.chat(prompt=prompt,
                                          image=image_url,
                                          tokenizer=tokenizer)

print('model output:', output_text)
print('runing time:', genertaion_time)
Prompt:
🧠 "What are the things I should be cautious about when I visit here?"
Image:
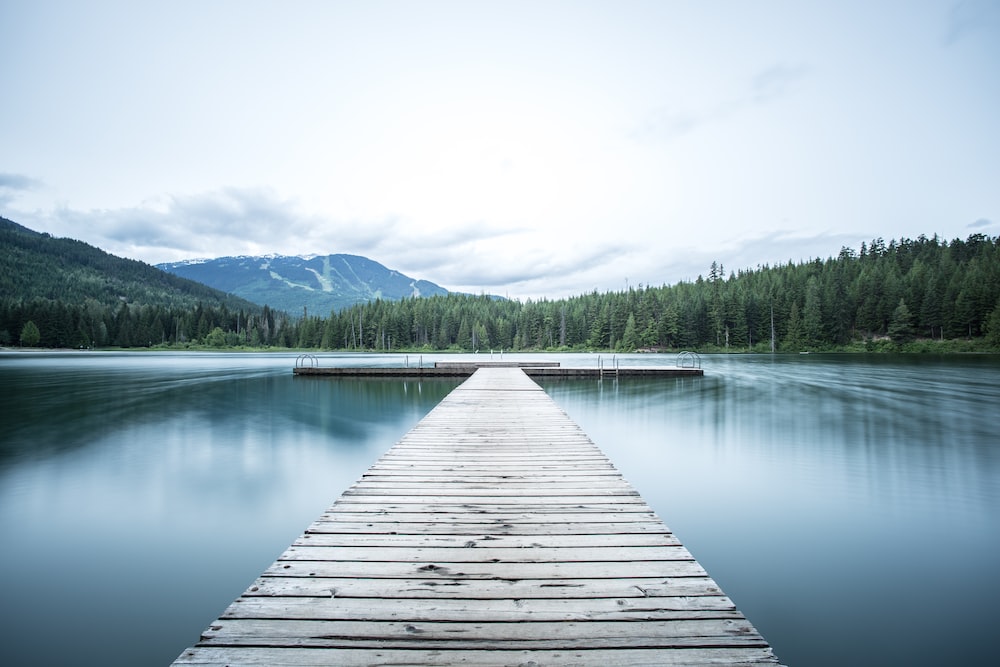
Model Output: When visiting this wooden pier on the lake, there are a few things to be cautious about. First, be aware of the water depth, as the water may be shallow or choppy, which could pose a risk of falling into the water or getting caught in a strong current. Second, be mindful of the weather conditions, as the image shows a cloudy day, which might indicate the possibility of rain or strong winds. These conditions can make the experience more challenging and potentially dangerous. Lastly, be cautious about the presence of any wildlife in the area, as the lake and its surroundings may attract various animals. Always follow safety guidelines and be respectful of the natural environment when visiting this picturesque location.
ocr_vqa was omitted in fine-tuning due to dataset access issues (to be re-added in next training run)qwen3_base_template.py| Question Type | Accuracy |
|---|---|
| Yes/No | 91.56% |
| Number | 65.69% |
| Other | 70.28% |
| Overall | 78.52% |
Note: Evaluation was performed on the VQAv2 test-dev set. It is unclear whether prior models used test-dev or test set. This model is currently being evaluated on the full test set and other benchmarks.
This model is currently undergoing evaluation on:
Stay tuned for updates!
If you find this model helpful, please consider citing or referencing this repo:
@misc{wang2024microllama,
  title        = {MicroLLaVA: a TinyLLaVA based VLM with MicroLlama 300M for single GPU training},
  author       = {Zixiao Ken Wang},
  year         = {2025},
  url          = {https://huggingface.co/keeeeenw/MicroLlava,https://huggingface.co/keeeeenw/MicroLlava-Qwen3-0.6B-base-siglip2-so400m}
}
Please also support my release of https://huggingface.co/keeeeenw/MicroLlava which is based on own https://huggingface.co/keeeeenw/MicroLlama for the language capabilities.