
Downloads · 30 days
16
9% of all-time downloads
jkim96/Qwen3.5-9B-DASHQ-INT4-g128
Qwen3.5-9B-DASHQ-INT4-g128 is a image-text-to-text model from jkim96. Use it for the image-text-to-text task on the model card, and read the license before you ship it in a product. It is set up for transformers. The card lists the license as apache-2.0.
Downloads · 30 days
16
9% of all-time downloads
All-time downloads
182
Public
Parameters
2.5B
8.7 GB on disk
Likes
0
Public
Click a slice to open those files.
.safetensors8.7 GB · 100%
How the weights are stored.
BF162.5B · 72%
From the Hugging Face model README
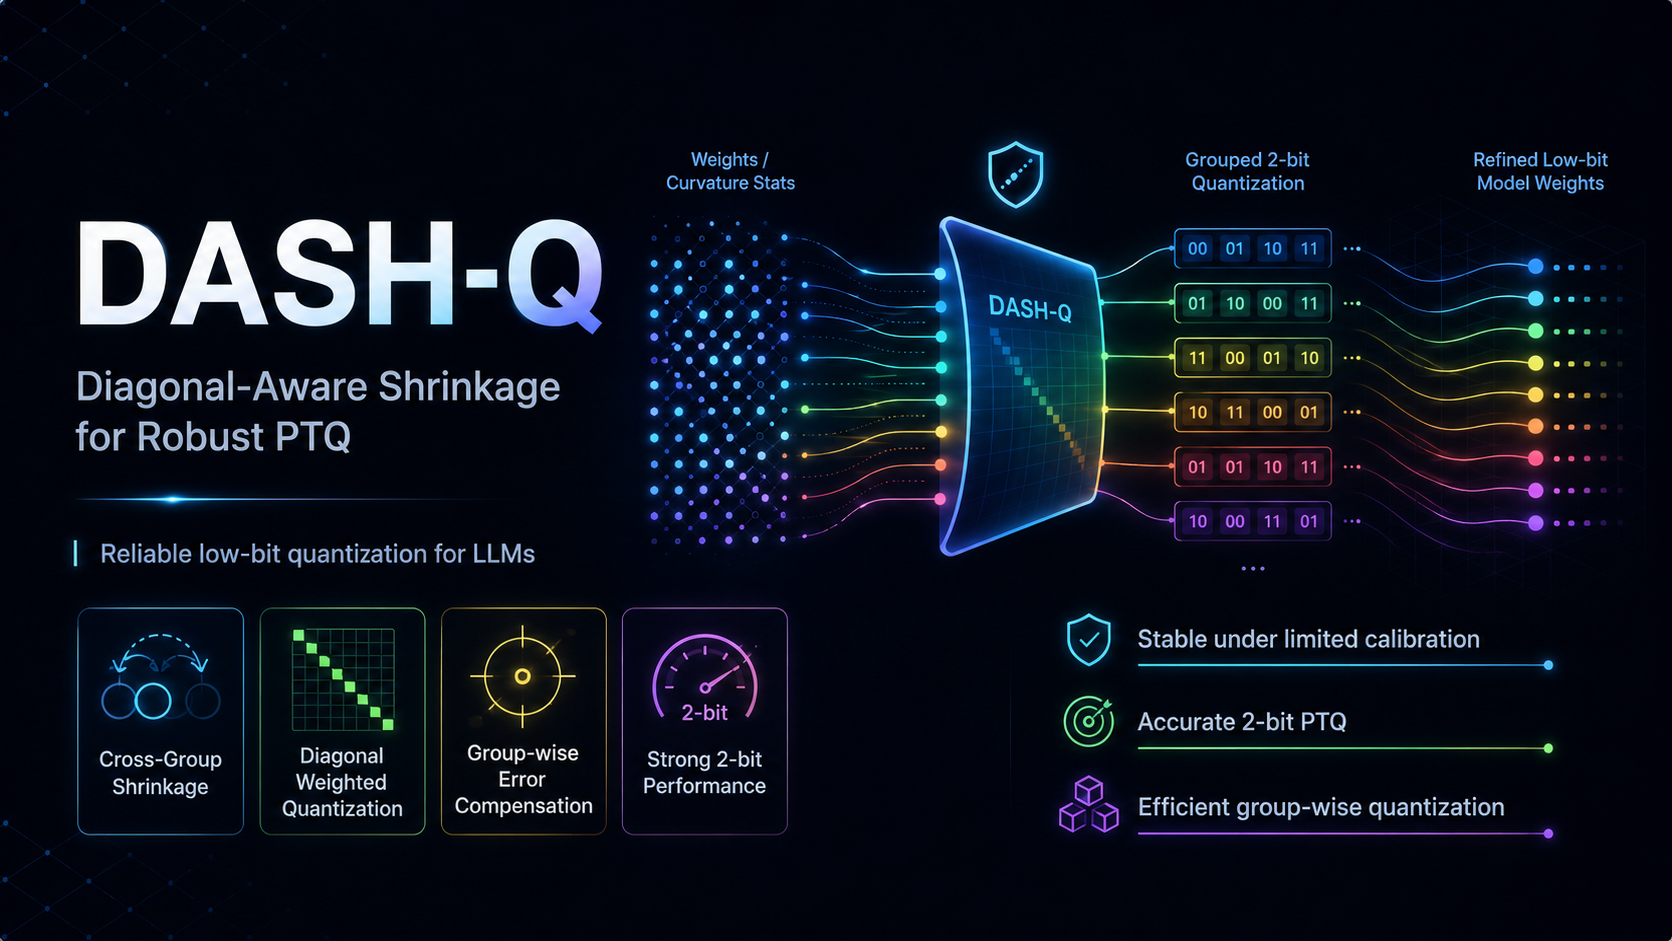
DASH-Q — Diagonal-Aware Shrinkage for Robust PTQ.
INT4· group size 128 · 8.6582 GB (from 19.3063 GB — 2.2x smaller)
from transformers import AutoModelForImageTextToText, AutoTokenizer

model = AutoModelForImageTextToText.from_pretrained(
    "jkim96/Qwen3.5-9B-DASHQ-INT4-g128", trust_remote_code=True, device_map="cuda", dtype="auto"
)
tokenizer = AutoTokenizer.from_pretrained("jkim96/Qwen3.5-9B-DASHQ-INT4-g128")

messages = [{"role": "user", "content": "Explain 2-bit quantization in one sentence."}]
text = tokenizer.apply_chat_template(messages, add_generation_prompt=True, tokenize=False)
inputs = tokenizer(text, return_tensors="pt").to(model.device)
print(tokenizer.decode(model.generate(**inputs, max_new_tokens=256)[0]))
trust_remote_code=True is required: the checkpoint ships its quantized-layer
implementation (modeling_dashq.py) and Triton kernels (dashq_kernel.py).
Without Triton, or on CPU, it falls back to dequantize-and-matmul in PyTorch.
| Package | Minimum | Verified with |
|---|---|---|
torch | 2.4 | 2.12.1+cu130 |
transformers | 5.8 | 5.9.0 |
triton | 3.0 (Linux; bundled with CUDA builds of PyTorch) | 3.7.1 |
huggingface_hub | 1.5 (pulled in by transformers) | 1.15.0 |
| Field | Value |
|---|---|
| Base model | Qwen/Qwen3.5-9B |
| Precision | INT4, group size 128 |
| Scale / zero dtype | float16 |
| Calibration | wikitext2, 128 samples x 2048 |
| Size | 8.6582 GB · original 19.3063 GB · 2.2x compression |
Full zero-shot / few-shot results for every DASH-Q checkpoint: github.com/JaeminK/dashq#benchmarks