
Downloads · 30 days
10
1% of all-time downloads
jkim96/Llama-3.1-405B-Instruct-DASHQ-INT2-g32
Llama-3.1-405B-Instruct-DASHQ-INT2-g32 is a text generation model from jkim96. Use it when you need the model to write or continue text. It is set up for transformers. The card lists the license as llama3.1.
Downloads · 30 days
10
1% of all-time downloads
All-time downloads
786
Public
Parameters
4.2B
159 GB on disk
Likes
0
Public
Click a slice to open those files.
.safetensors159 GB · 100%
How the weights are stored.
I3225.1B · 46%
From the Hugging Face model README
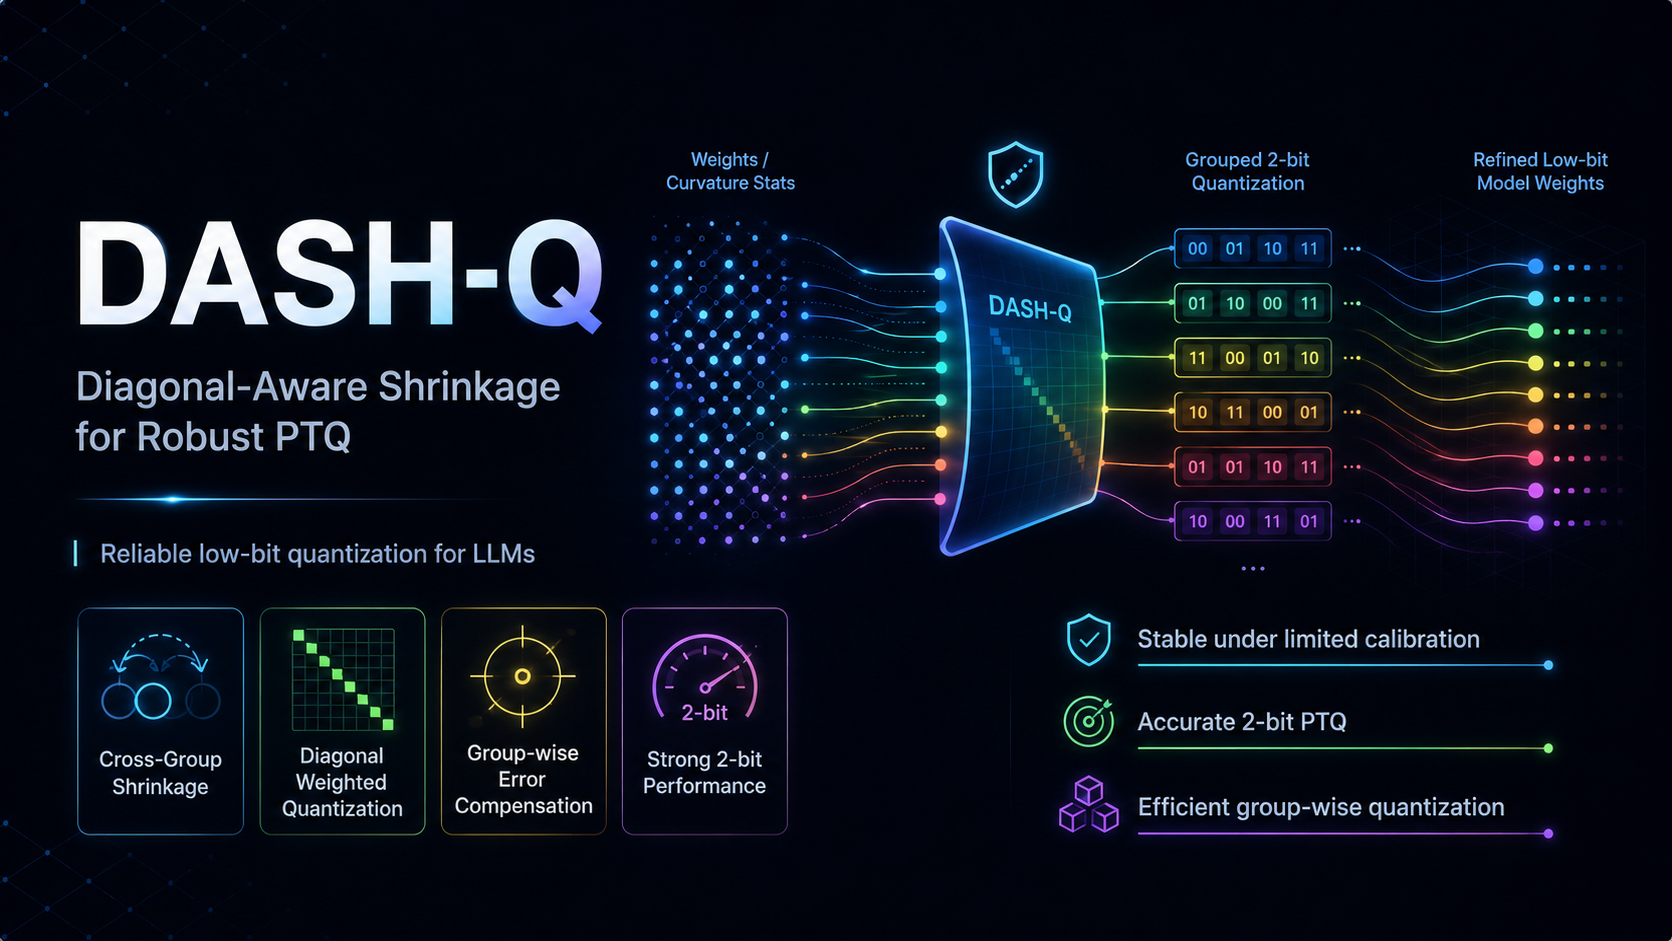
DASH-Q — Diagonal-Aware Shrinkage for Robust PTQ.
INT2· group size 32 · 159.0315 GB (from 811.7069 GB — 5.1x smaller)
from transformers import AutoModelForCausalLM, AutoTokenizer

model = AutoModelForCausalLM.from_pretrained(
    "jkim96/Llama-3.1-405B-Instruct-DASHQ-INT2-g32", trust_remote_code=True, device_map="cuda", dtype="auto"
)
tokenizer = AutoTokenizer.from_pretrained("jkim96/Llama-3.1-405B-Instruct-DASHQ-INT2-g32")

messages = [{"role": "user", "content": "Explain 2-bit quantization in one sentence."}]
text = tokenizer.apply_chat_template(messages, add_generation_prompt=True, tokenize=False)
inputs = tokenizer(text, return_tensors="pt").to(model.device)
print(tokenizer.decode(model.generate(**inputs, max_new_tokens=256)[0]))
trust_remote_code=True is required: the checkpoint ships its quantized-layer
implementation (modeling_dashq.py) and Triton kernels (dashq_kernel.py).
Without Triton, or on CPU, it falls back to dequantize-and-matmul in PyTorch.
| Package | Minimum | Verified with |
|---|---|---|
torch | 2.4 | 2.12.1+cu130 |
transformers | 5.8 | 5.9.0 |
triton | 3.0 (Linux; bundled with CUDA builds of PyTorch) | 3.7.1 |
huggingface_hub | 1.5 (pulled in by transformers) | 1.15.0 |
| Field | Value |
|---|---|
| Base model | meta-llama/Llama-3.1-405B-Instruct |
| Precision | INT2, group size 32 |
| Scale / zero dtype | float16 |
| Calibration | wikitext2, 128 samples x 2048 |
| Size | 159.0315 GB · original 811.7069 GB · 5.1x compression |
Full zero-shot / few-shot results for every DASH-Q checkpoint: github.com/JaeminK/dashq#benchmarks