Downloads · 30 days
25
0% of all-time downloads
jinhybr/OCR-Donut-CORD
OCR-Donut-CORD is a image-to-text model from jinhybr. Use it when you need a caption or text from an image. It is set up for transformers. The card lists the license as mit.
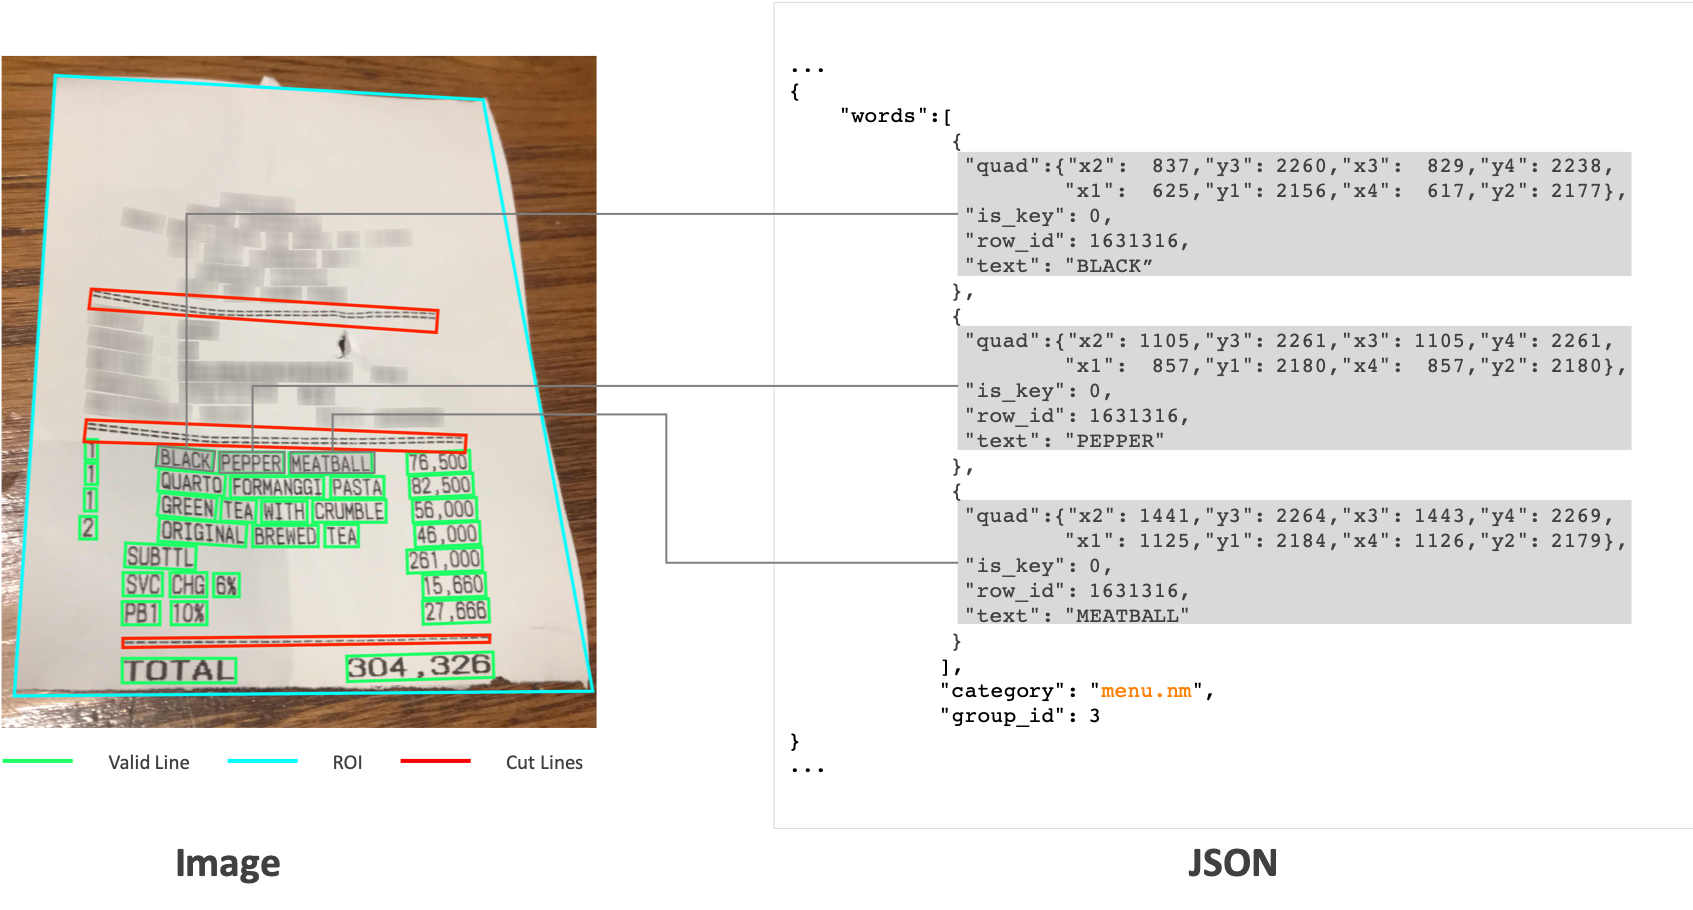
Donut model fine-tuned on CORD. It was introduced in the paper OCR-free Document Understanding Transformer by Geewok et al. and first released in this repository.
Downloads · 30 days
25
0% of all-time downloads
All-time downloads
47.9K
Public
Repo size
17 GB
Likes
207
Public
Click a slice to open those files.
.bin809 MB · 99%
From the Hugging Face model README
Donut model fine-tuned on CORD. It was introduced in the paper OCR-free Document Understanding Transformer by Geewok et al. and first released in this repository.
Disclaimer: The team releasing Donut did not write a model card for this model so this model card has been written by the Hugging Face team.
Donut consists of a vision encoder (Swin Transformer) and a text decoder (BART). Given an image, the encoder first encodes the image into a tensor of embeddings (of shape batch_size, seq_len, hidden_size), after which the decoder autoregressively generates text, conditioned on the encoding of the encoder.
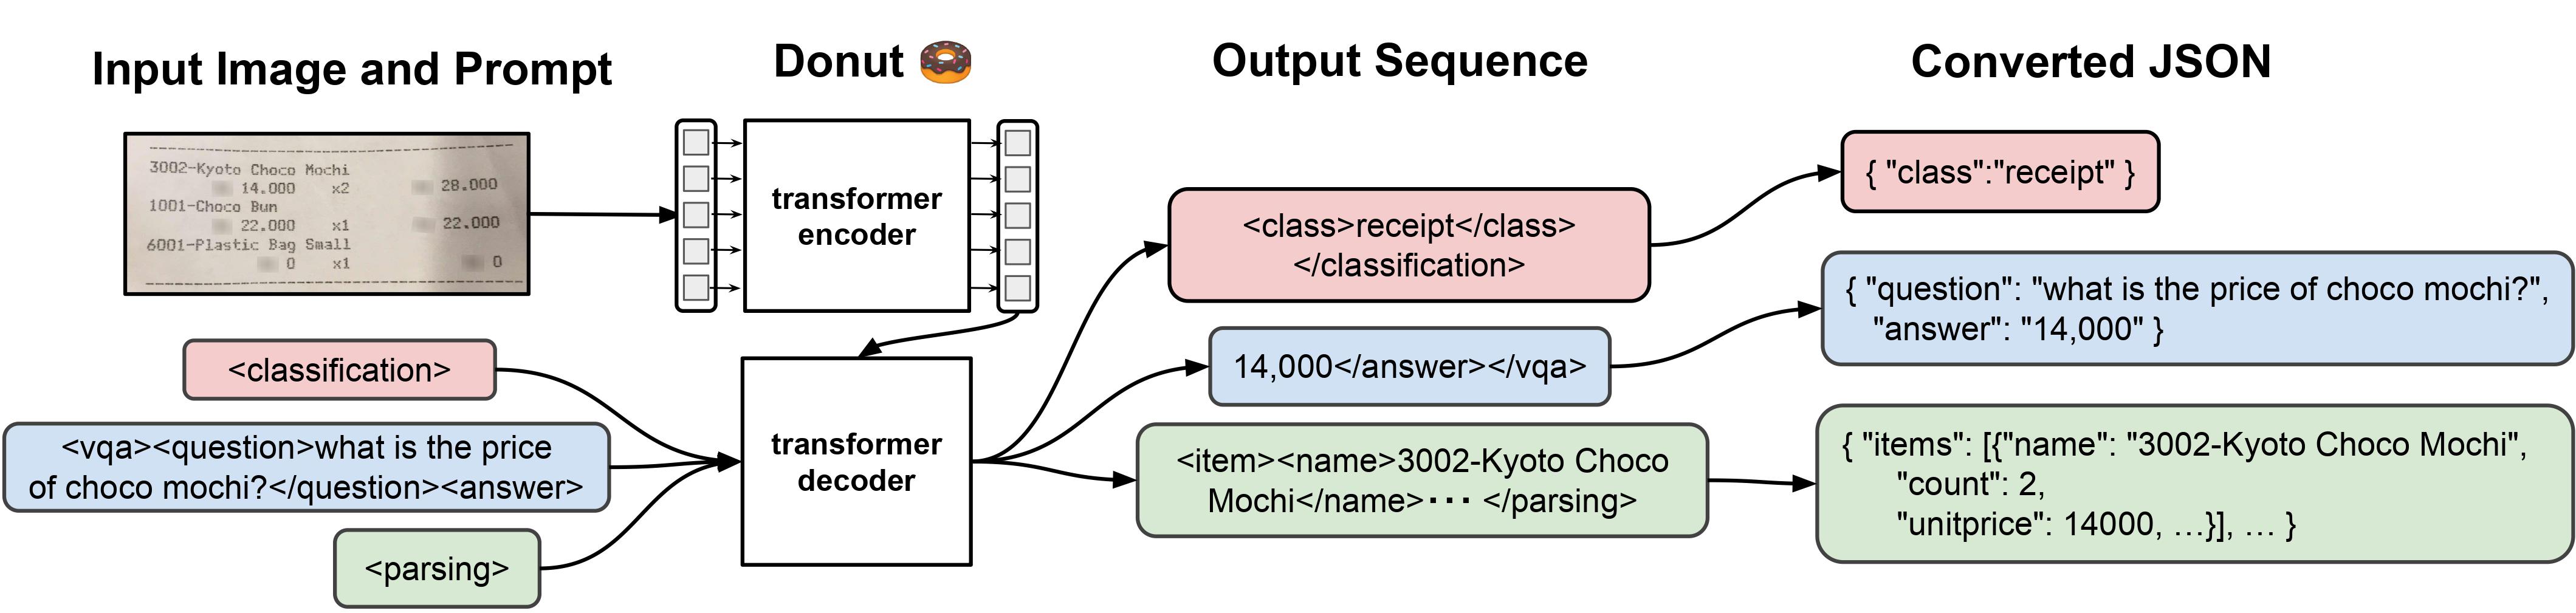
This model is fine-tuned on CORD, a document parsing dataset.
We refer to the documentation which includes code examples.
CORD: A Consolidated Receipt Dataset for Post-OCR Parsing.