
Downloads · 30 days
22
0% of all-time downloads
jinhybr/OCR-DocVQA-Donut
OCR-DocVQA-Donut is a document question answering model from jinhybr. Use it for the document question answering task on the model card, and read the license before you ship it in a product. It is set up for transformers. The card lists the license as mit.
Donut model fine-tuned on DocVQA. It was introduced in the paper OCR-free Document Understanding Transformer by Geewok et al. and first released in this repository.
Downloads · 30 days
22
0% of all-time downloads
All-time downloads
11.8K
Public
Repo size
1.6 GB
Likes
12
Public
Click a slice to open those files.
.bin809 MB · 99%
From the Hugging Face model README
Donut model fine-tuned on DocVQA. It was introduced in the paper OCR-free Document Understanding Transformer by Geewok et al. and first released in this repository.
Disclaimer: The team releasing Donut did not write a model card for this model so this model card has been written by the Hugging Face team.
Donut consists of a vision encoder (Swin Transformer) and a text decoder (BART). Given an image, the encoder first encodes the image into a tensor of embeddings (of shape batch_size, seq_len, hidden_size), after which the decoder autoregressively generates text, conditioned on the encoding of the encoder.
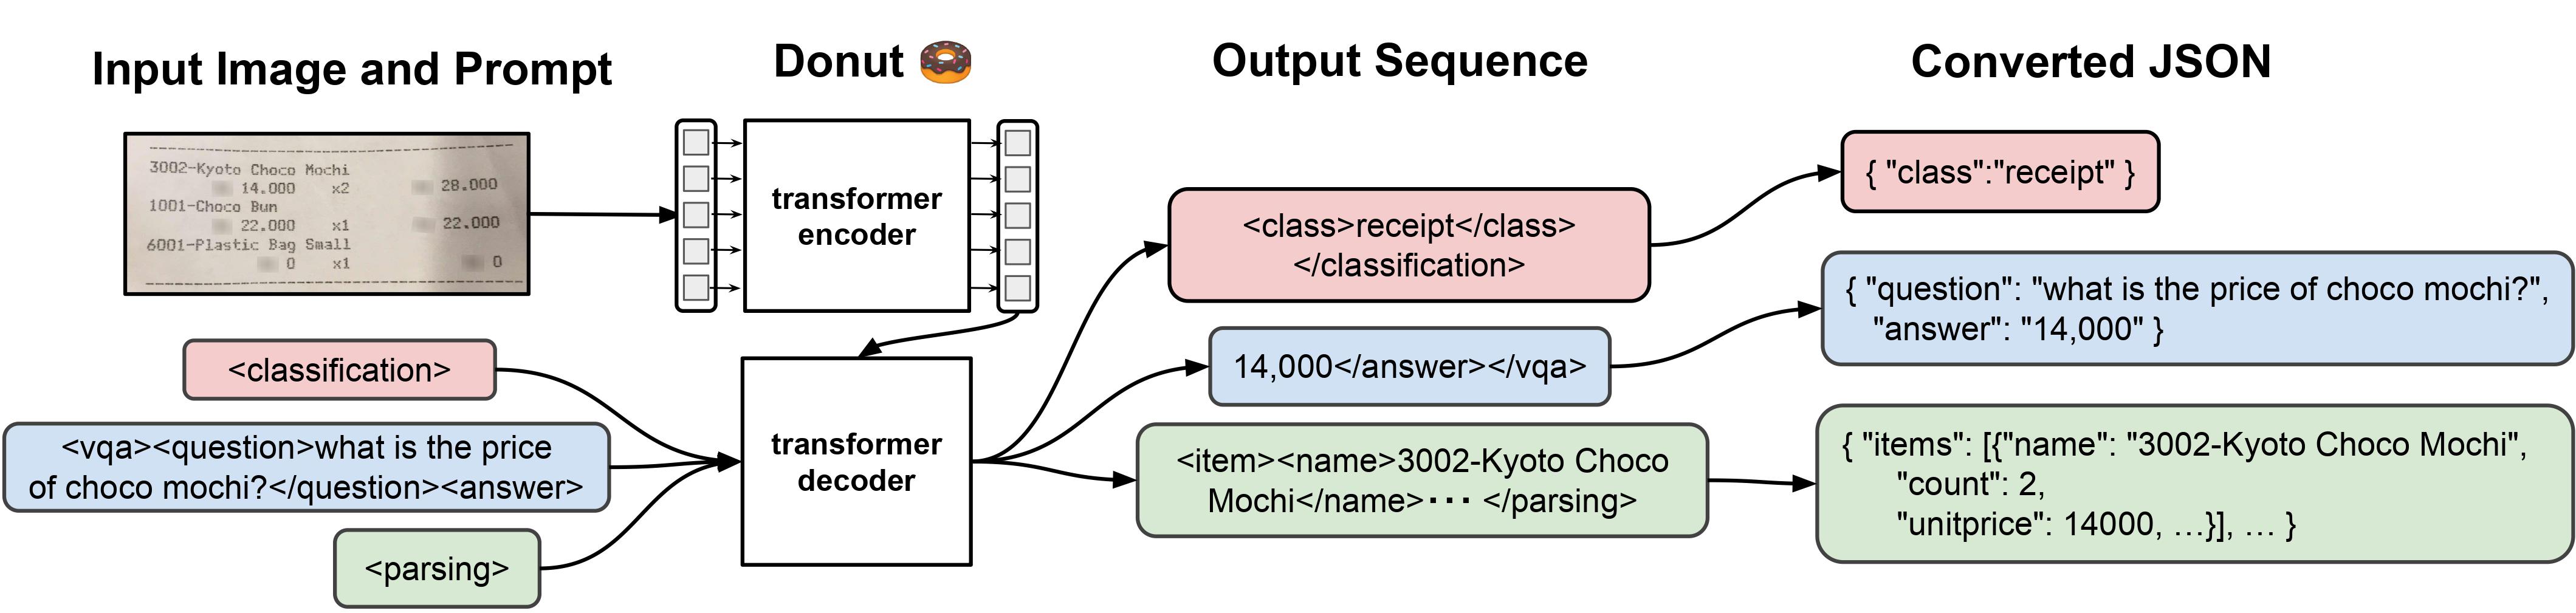
This model is fine-tuned on DocVQA, a document visual question answering dataset.
We refer to the documentation which includes code examples.