
Downloads · 30 days
927
20% of all-time downloads
jhq2250/clip_vision_h.safetensors
clip_vision_h.safetensors is a text-to-video model from jhq2250. Use it when you need video from a text prompt. The card lists the license as apache-2.0.
- drag gguf to ./ComfyUI/models/diffusionmodels - drag t5xxl-um to ./ComfyUI/models/textencoders - drag vae to ./ComfyUI/models/vae
Downloads · 30 days
927
20% of all-time downloads
All-time downloads
4.5K
Public
Repo size
1.3 TB
Likes
4
Public
Click a slice to open those files.
.gguf1.2 TB · 98%
From the Hugging Face model README
./ComfyUI/models/diffusion_models./ComfyUI/models/text_encoders./ComfyUI/models/vae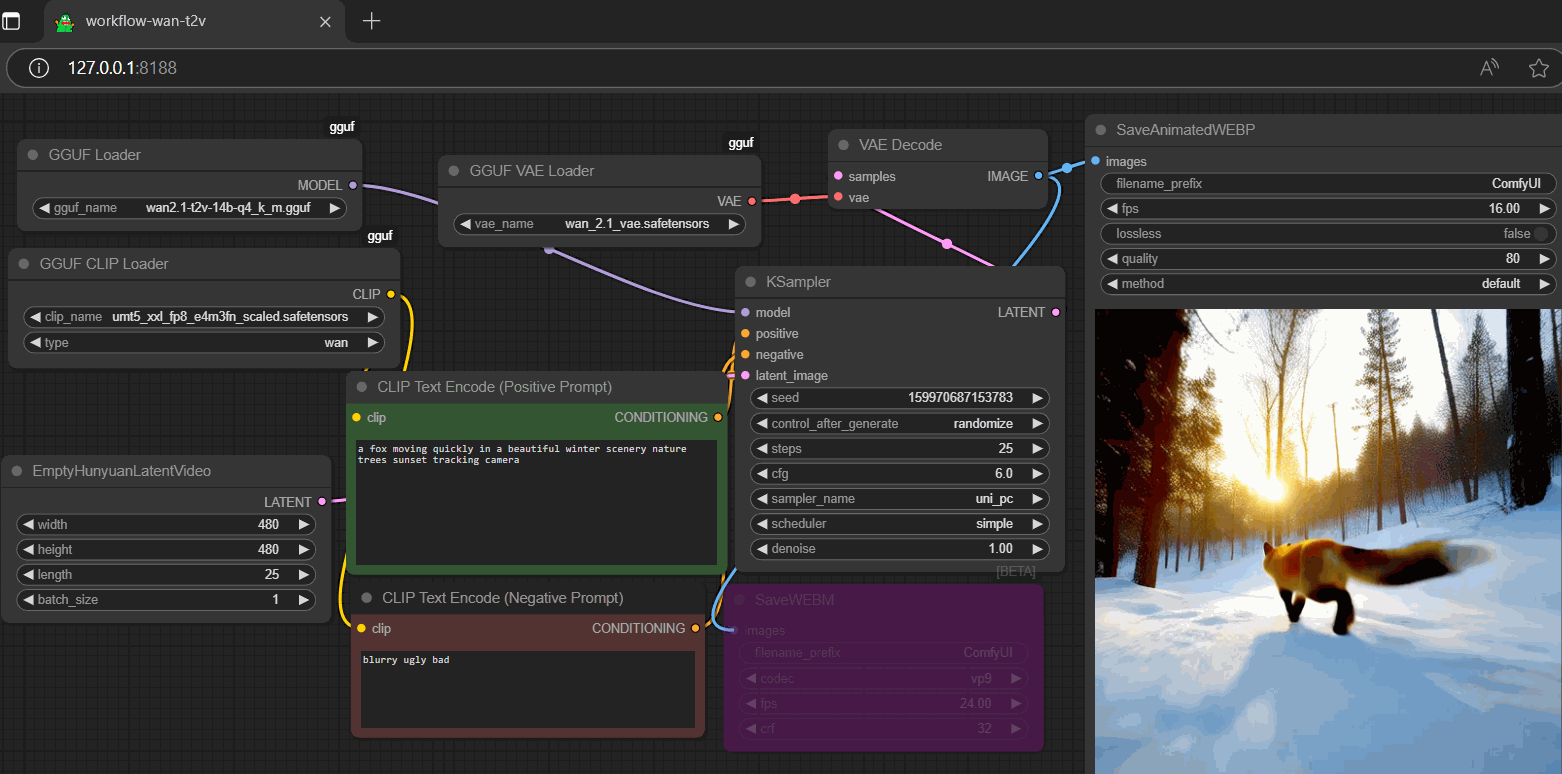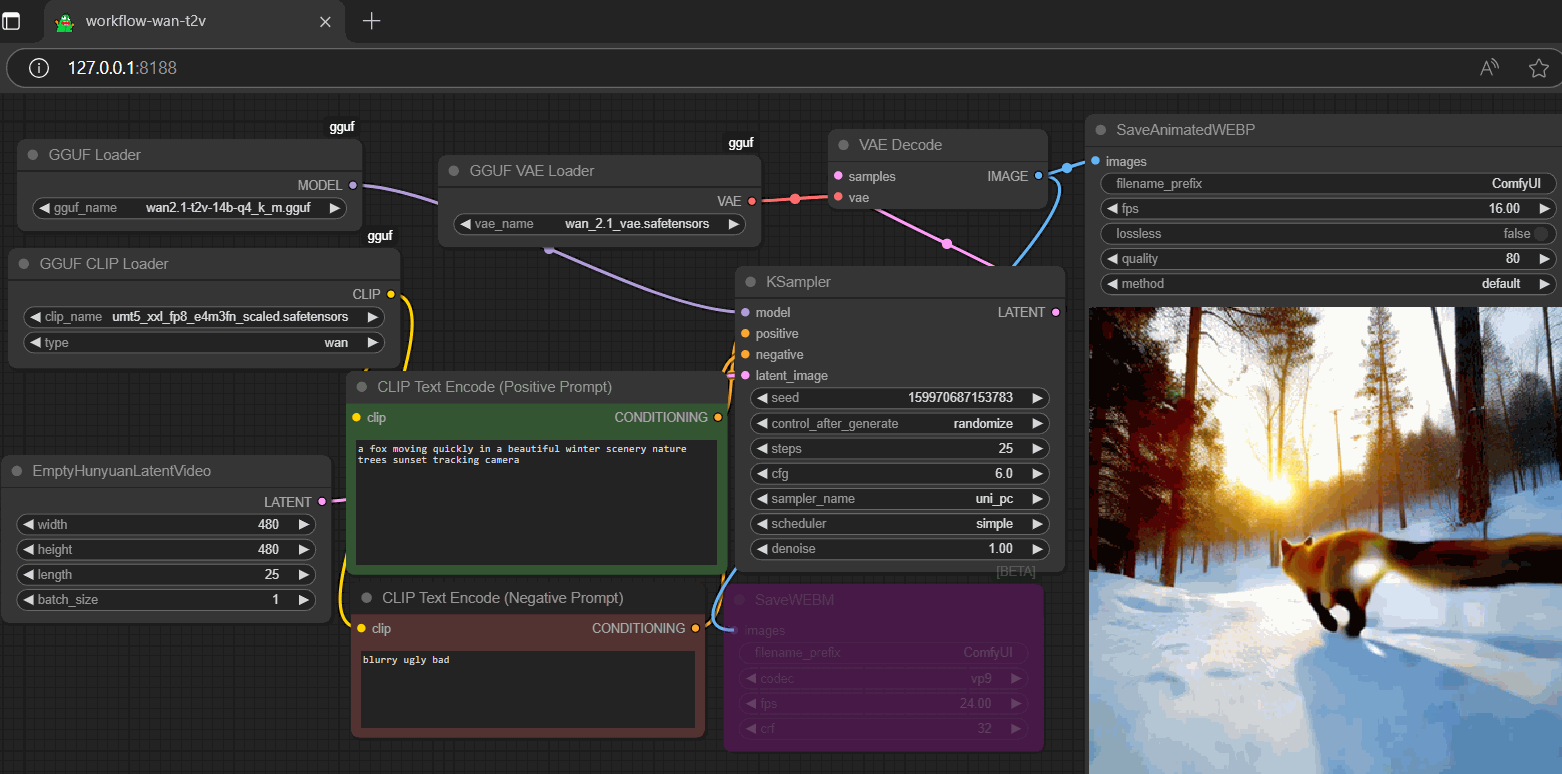
./ComfyUI/models/clip_vision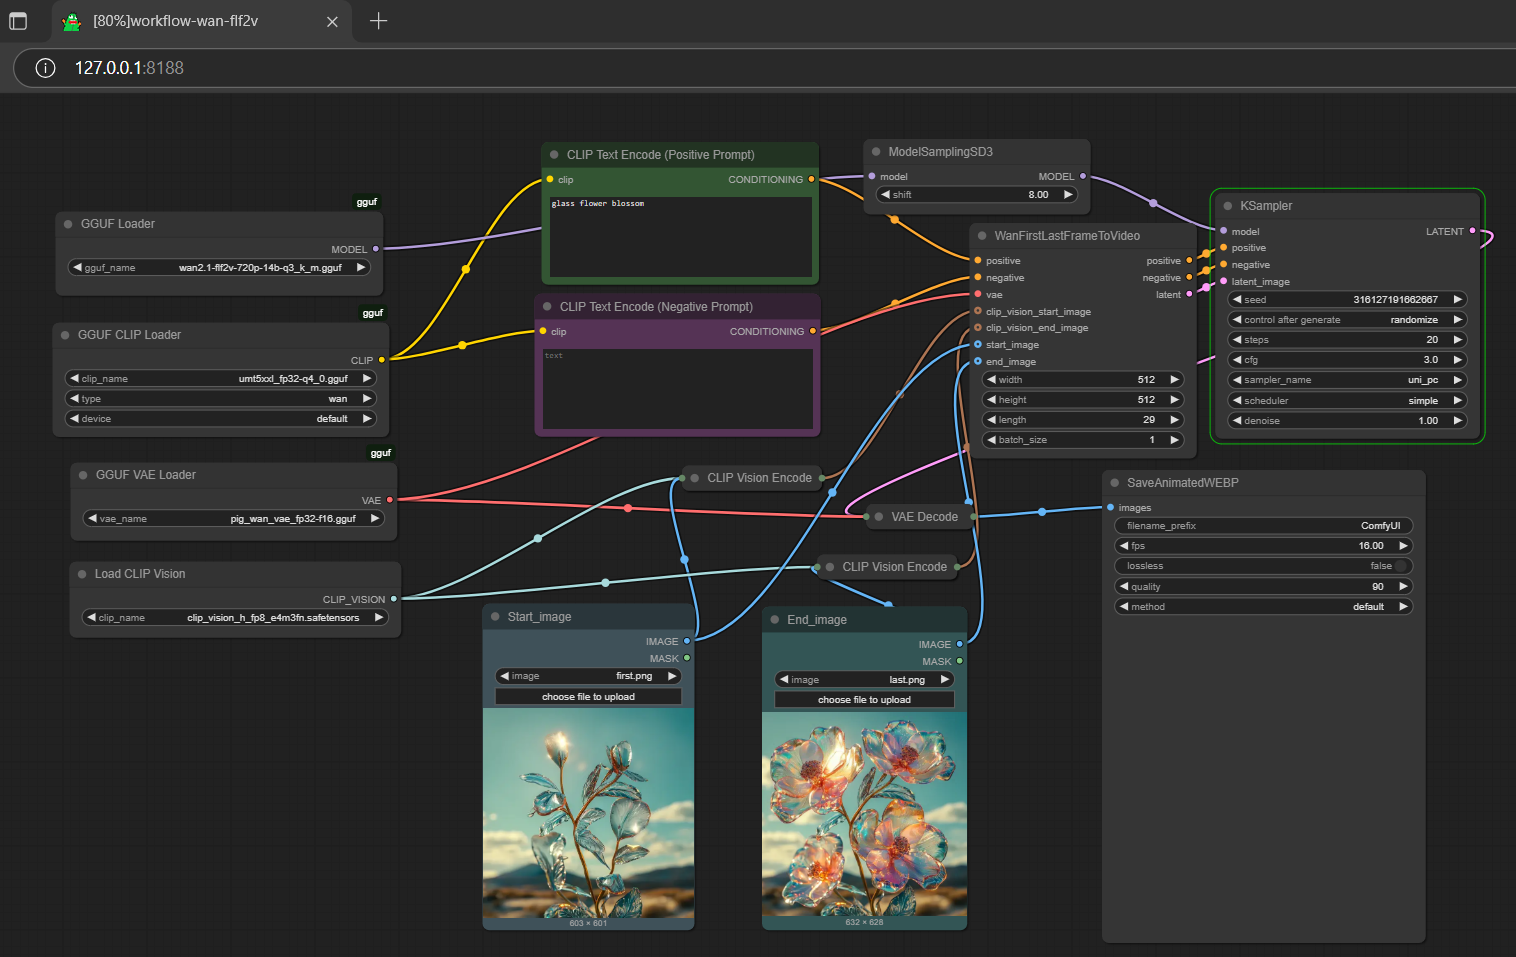
pig is a lazy architecture for gguf node; it applies to all model, encoder and vae gguf file(s); if you try to run it in comfyui-gguf node, you might need to manually add pig in it's IMG_ARCH_LIST (under loader.py); easier than you edit the gguf file itself; btw, model architecture which compatible with comfyui-gguf, including wan, should work in gguf nodeimport torch
from transformers import UMT5EncoderModel
from diffusers import AutoencoderKLWan, WanVACEPipeline, WanVACETransformer3DModel, GGUFQuantizationConfig
from diffusers.schedulers.scheduling_unipc_multistep import UniPCMultistepScheduler
from diffusers.utils import export_to_video
model_path = "https://huggingface.co/calcuis/wan-gguf/blob/main/wan2.1-v5-vace-1.3b-q4_0.gguf"
transformer = WanVACETransformer3DModel.from_single_file(
model_path,
quantization_config=GGUFQuantizationConfig(compute_dtype=torch.bfloat16),
torch_dtype=torch.bfloat16,
)
text_encoder = UMT5EncoderModel.from_pretrained(
"chatpig/umt5xxl-encoder-gguf",
gguf_file="umt5xxl-encoder-q4_0.gguf",
torch_dtype=torch.bfloat16,
)
vae = AutoencoderKLWan.from_pretrained(
"callgg/wan-decoder",
subfolder="vae",
torch_dtype=torch.float32
)
pipe = WanVACEPipeline.from_pretrained(
"callgg/wan-decoder",
transformer=transformer,
text_encoder=text_encoder,
vae=vae,
torch_dtype=torch.bfloat16
)
flow_shift = 3.0
pipe.scheduler = UniPCMultistepScheduler.from_config(pipe.scheduler.config, flow_shift=flow_shift)
pipe.enable_model_cpu_offload()
pipe.vae.enable_tiling()
prompt = "a pig moving quickly in a beautiful winter scenery nature trees sunset tracking camera"
negative_prompt = "blurry ugly bad"
output = pipe(
prompt=prompt,
negative_prompt=negative_prompt,
width=720,
height=480,
num_frames=57,
num_inference_steps=24,
guidance_scale=2.5,
conditioning_scale=0.0,
generator=torch.Generator().manual_seed(0),
).frames[0]
export_to_video(output, "output.mp4", fps=16)
ggc v2
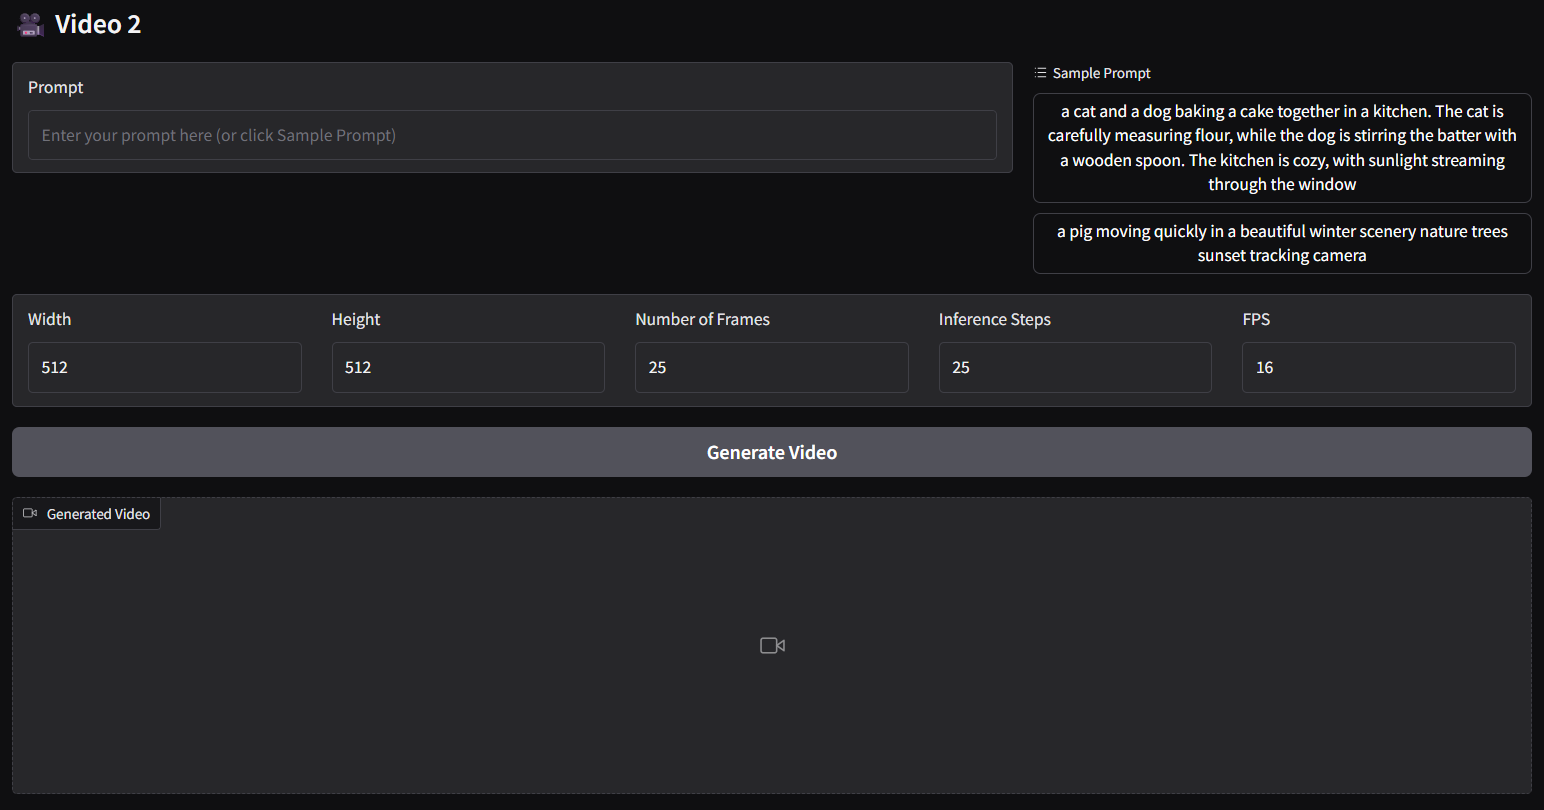
f32 status (avoid triggering time/text embedding key error for inference usage)