
Downloads · 30 days
9
3% of all-time downloads
hooman650/bge-large-en-v1.5-onnx-o4
bge-large-en-v1.5-onnx-o4 is a feature extraction model from hooman650. Use it when you need embeddings to search or compare text. It is set up for transformers. The card lists the license as mit.
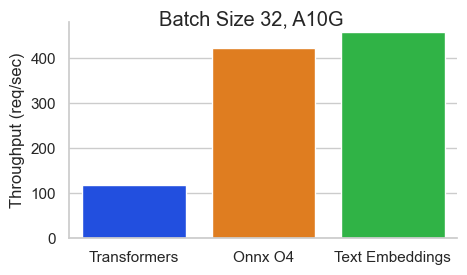
This is an ONNX O4 strategy optimized version of BAAI/bge-large-en-v1.5 optimal for Cuda. It should be much faster than the original version.
Downloads · 30 days
9
3% of all-time downloads
All-time downloads
268
Public
Repo size
668 MB
Likes
0
Public
Click a slice to open those files.
.onnx668 MB · 100%
From the Hugging Face model README
This is an ONNX O4 strategy optimized version of BAAI/bge-large-en-v1.5 optimal for Cuda. It should be much faster than the original
version.
# pip install "optimum[onnxruntime-gpu]" transformers

from optimum.onnxruntime import ORTModelForFeatureExtraction
from transformers import AutoTokenizer

tokenizer = AutoTokenizer.from_pretrained('hooman650/bge-large-en-v1.5-onnx-o4')
model = ORTModelForFeatureExtraction.from_pretrained('hooman650/bge-large-en-v1.5-onnx-o4')
model.to("cuda")

pairs = ["pandas usually live in the jungles"]
with torch.no_grad():
    inputs = tokenizer(pairs, padding=True, truncation=True, return_tensors='pt', max_length=512)
    sentence_embeddings = model(**inputs)[0][:, 0]

# normalize embeddings
sentence_embeddings = torch.nn.functional.normalize(sentence_embeddings, p=2, dim=1)