
Downloads · 30 days
254
0% of all-time downloads
h2oai/h2ogpt-research-oasst1-llama-65b
h2ogpt-research-oasst1-llama-65b is a text generation model from h2oai. Use it when you need the model to write or continue text. It is set up for transformers. The card lists the license as other.
H2O.ai's h2ogpt-research-oasst1-llama-65b is a 65 billion parameter instruction-following large language model (NOT licensed for commercial use).
Downloads · 30 days
254
0% of all-time downloads
All-time downloads
60.6K
Public
Repo size
262 GB
Likes
9
Public
Click a slice to open those files.
.bin131 GB · 99%
From the Hugging Face model README
H2O.ai's h2ogpt-research-oasst1-llama-65b is a 65 billion parameter instruction-following large language model (NOT licensed for commercial use).
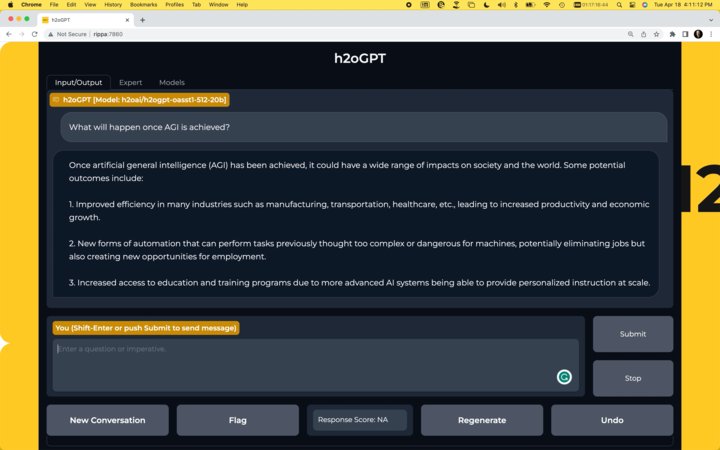
To use the model with the transformers library on a machine with GPUs, first make sure you have the following libraries installed.
pip install transformers==4.29.2
pip install accelerate==0.19.0
pip install torch==2.0.1
pip install einops==0.6.1
import torch
from transformers import pipeline, AutoTokenizer

tokenizer = AutoTokenizer.from_pretrained("h2oai/h2ogpt-research-oasst1-llama-65b", padding_side="left")
generate_text = pipeline(model="h2oai/h2ogpt-research-oasst1-llama-65b", tokenizer=tokenizer, torch_dtype=torch.bfloat16, trust_remote_code=True, device_map="auto", prompt_type="human_bot")
res = generate_text("Why is drinking water so healthy?", max_new_tokens=100)
print(res[0]["generated_text"])
Alternatively, if you prefer to not use trust_remote_code=True you can download instruct_pipeline.py,
store it alongside your notebook, and construct the pipeline yourself from the loaded model and tokenizer:
import torch
from h2oai_pipeline import H2OTextGenerationPipeline
from transformers import AutoModelForCausalLM, AutoTokenizer

tokenizer = AutoTokenizer.from_pretrained("h2oai/h2ogpt-research-oasst1-llama-65b", padding_side="left")
model = AutoModelForCausalLM.from_pretrained("h2oai/h2ogpt-research-oasst1-llama-65b", torch_dtype=torch.bfloat16, device_map="auto")
generate_text = H2OTextGenerationPipeline(model=model, tokenizer=tokenizer, prompt_type="human_bot")

res = generate_text("Why is drinking water so healthy?", max_new_tokens=100)
print(res[0]["generated_text"])
LlamaForCausalLM(
  (model): LlamaModel(
    (embed_tokens): Embedding(32000, 8192, padding_idx=31999)
    (layers): ModuleList(
      (0-79): 80 x LlamaDecoderLayer(
        (self_attn): LlamaAttention(
          (q_proj): Linear(in_features=8192, out_features=8192, bias=False)
          (k_proj): Linear(in_features=8192, out_features=8192, bias=False)
          (v_proj): Linear(in_features=8192, out_features=8192, bias=False)
          (o_proj): Linear(in_features=8192, out_features=8192, bias=False)
          (rotary_emb): LlamaRotaryEmbedding()
        )
        (mlp): LlamaMLP(
          (gate_proj): Linear(in_features=8192, out_features=22016, bias=False)
          (down_proj): Linear(in_features=22016, out_features=8192, bias=False)
          (up_proj): Linear(in_features=8192, out_features=22016, bias=False)
          (act_fn): SiLUActivation()
        )
        (input_layernorm): LlamaRMSNorm()
        (post_attention_layernorm): LlamaRMSNorm()
      )
    )
    (norm): LlamaRMSNorm()
  )
  (lm_head): Linear(in_features=8192, out_features=32000, bias=False)
)
LlamaConfig {
  "_name_or_path": "h2oai/h2ogpt-research-oasst1-llama-65b",
  "architectures": [
    "LlamaForCausalLM"
  ],
  "bos_token_id": 0,
  "custom_pipelines": {
    "text-generation": {
      "impl": "h2oai_pipeline.H2OTextGenerationPipeline",
      "pt": "AutoModelForCausalLM"
    }
  },
  "eos_token_id": 1,
  "hidden_act": "silu",
  "hidden_size": 8192,
  "initializer_range": 0.02,
  "intermediate_size": 22016,
  "max_position_embeddings": 2048,
  "max_sequence_length": 2048,
  "model_type": "llama",
  "num_attention_heads": 64,
  "num_hidden_layers": 80,
  "pad_token_id": -1,
  "rms_norm_eps": 1e-05,
  "tie_word_embeddings": false,
  "torch_dtype": "float16",
  "transformers_version": "4.30.1",
  "use_cache": true,
  "vocab_size": 32000
}
Model validation results using EleutherAI lm-evaluation-harness.
TBD
Please read this disclaimer carefully before using the large language model provided in this repository. Your use of the model signifies your agreement to the following terms and conditions.
By using the large language model provided in this repository, you agree to accept and comply with the terms and conditions outlined in this disclaimer. If you do not agree with any part of this disclaimer, you should refrain from using the model and any content generated by it.