
Downloads · 30 days
101
1% of all-time downloads
h2oai/h2ogpt-oasst1-falcon-40b
h2ogpt-oasst1-falcon-40b is a text generation model from h2oai. Use it when you need the model to write or continue text. It is set up for transformers. The card lists the license as apache-2.0.
H2O.ai's h2ogpt-oasst1-falcon-40b is a 40 billion parameter instruction-following large language model licensed for commercial use.
Downloads · 30 days
101
1% of all-time downloads
All-time downloads
16.3K
Public
Repo size
166 GB
Likes
17
Public
Click a slice to open those files.
.bin82.6 GB · 99%
From the Hugging Face model README
H2O.ai's h2ogpt-oasst1-falcon-40b is a 40 billion parameter instruction-following large language model licensed for commercial use.
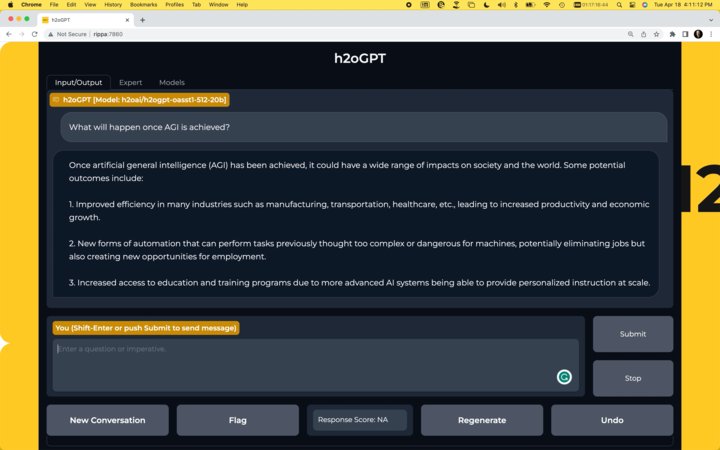
To use the model with the transformers library on a machine with GPUs, first make sure you have the following libraries installed.
pip install transformers==4.29.2
pip install accelerate==0.19.0
pip install torch==2.0.1
pip install einops==0.6.1
import torch
from transformers import pipeline, AutoTokenizer

tokenizer = AutoTokenizer.from_pretrained("h2oai/h2ogpt-oasst1-falcon-40b", padding_side="left")
generate_text = pipeline(model="h2oai/h2ogpt-oasst1-falcon-40b", tokenizer=tokenizer, torch_dtype=torch.bfloat16, trust_remote_code=True, device_map="auto", prompt_type="human_bot")
res = generate_text("Why is drinking water so healthy?", max_new_tokens=100)
print(res[0]["generated_text"])
Alternatively, if you prefer to not use trust_remote_code=True you can download instruct_pipeline.py,
store it alongside your notebook, and construct the pipeline yourself from the loaded model and tokenizer:
import torch
from h2oai_pipeline import H2OTextGenerationPipeline
from transformers import AutoModelForCausalLM, AutoTokenizer

tokenizer = AutoTokenizer.from_pretrained("h2oai/h2ogpt-oasst1-falcon-40b", padding_side="left")
model = AutoModelForCausalLM.from_pretrained("h2oai/h2ogpt-oasst1-falcon-40b", torch_dtype=torch.bfloat16, device_map="auto")
generate_text = H2OTextGenerationPipeline(model=model, tokenizer=tokenizer, prompt_type="human_bot")

res = generate_text("Why is drinking water so healthy?", max_new_tokens=100)
print(res[0]["generated_text"])
RWForCausalLM(
  (transformer): RWModel(
    (word_embeddings): Embedding(65024, 8192)
    (h): ModuleList(
      (0-59): 60 x DecoderLayer(
        (ln_attn): LayerNorm((8192,), eps=1e-05, elementwise_affine=True)
        (ln_mlp): LayerNorm((8192,), eps=1e-05, elementwise_affine=True)
        (self_attention): Attention(
          (maybe_rotary): RotaryEmbedding()
          (query_key_value): Linear(in_features=8192, out_features=9216, bias=False)
          (dense): Linear(in_features=8192, out_features=8192, bias=False)
          (attention_dropout): Dropout(p=0.0, inplace=False)
        )
        (mlp): MLP(
          (dense_h_to_4h): Linear(in_features=8192, out_features=32768, bias=False)
          (act): GELU(approximate='none')
          (dense_4h_to_h): Linear(in_features=32768, out_features=8192, bias=False)
        )
      )
    )
    (ln_f): LayerNorm((8192,), eps=1e-05, elementwise_affine=True)
  )
  (lm_head): Linear(in_features=8192, out_features=65024, bias=False)
)
RWConfig {
  "_name_or_path": "h2oai/h2ogpt-oasst1-falcon-40b",
  "alibi": false,
  "apply_residual_connection_post_layernorm": false,
  "architectures": [
    "RWForCausalLM"
  ],
  "attention_dropout": 0.0,
  "auto_map": {
    "AutoConfig": "tiiuae/falcon-40b--configuration_RW.RWConfig",
    "AutoModel": "tiiuae/falcon-40b--modelling_RW.RWModel",
    "AutoModelForCausalLM": "tiiuae/falcon-40b--modelling_RW.RWForCausalLM",
    "AutoModelForQuestionAnswering": "tiiuae/falcon-40b--modelling_RW.RWForQuestionAnswering",
    "AutoModelForSequenceClassification": "tiiuae/falcon-40b--modelling_RW.RWForSequenceClassification",
    "AutoModelForTokenClassification": "tiiuae/falcon-40b--modelling_RW.RWForTokenClassification"
  },
  "bias": false,
  "bos_token_id": 11,
  "custom_pipelines": {
    "text-generation": {
      "impl": "h2oai_pipeline.H2OTextGenerationPipeline",
      "pt": "AutoModelForCausalLM"
    }
  },
  "eos_token_id": 11,
  "hidden_dropout": 0.0,
  "hidden_size": 8192,
  "initializer_range": 0.02,
  "layer_norm_epsilon": 1e-05,
  "model_type": "RefinedWeb",
  "n_head": 128,
  "n_head_kv": 8,
  "n_layer": 60,
  "parallel_attn": true,
  "torch_dtype": "float16",
  "transformers_version": "4.30.0.dev0",
  "use_cache": true,
  "vocab_size": 65024
}
Model validation results using EleutherAI lm-evaluation-harness.
| Task | Version | Metric | Value | Stderr | |
|---|---|---|---|---|---|
| arc_challenge | 0 | acc | 0.5196 | ± | 0.0146 |
| acc_norm | 0.5461 | ± | 0.0145 | ||
| arc_easy | 0 | acc | 0.8190 | ± | 0.0079 |
| acc_norm | 0.7799 | ± | 0.0085 | ||
| boolq | 1 | acc | 0.8514 | ± | 0.0062 |
| hellaswag | 0 | acc | 0.6485 | ± | 0.0048 |
| acc_norm | 0.8314 | ± | 0.0037 | ||
| openbookqa | 0 | acc | 0.3860 | ± | 0.0218 |
| acc_norm | 0.4880 | ± | 0.0224 | ||
| piqa | 0 | acc | 0.8194 | ± | 0.0090 |
| acc_norm | 0.8335 | ± | 0.0087 | ||
| winogrande | 0 | acc | 0.7751 | ± | 0.0117 |
Please read this disclaimer carefully before using the large language model provided in this repository. Your use of the model signifies your agreement to the following terms and conditions.
By using the large language model provided in this repository, you agree to accept and comply with the terms and conditions outlined in this disclaimer. If you do not agree with any part of this disclaimer, you should refrain from using the model and any content generated by it.