
Downloads · 30 days
16
2% of all-time downloads
globuslabs/ScholarBERT_1
ScholarBERT_1 is a fill-mask model from globuslabs. Use it when you need the model to fill a missing word. It is set up for transformers. The card lists the license as apache-2.0.
This is the ScholarBERT1 variant of the ScholarBERT model family.
Downloads · 30 days
16
2% of all-time downloads
All-time downloads
841
Public
Repo size
4.3 GB
Likes
1
Public
Click a slice to open those files.
.bin1.4 GB · 100%
From the Hugging Face model README
This is the ScholarBERT_1 variant of the ScholarBERT model family.
The model is pretrained on a large collection of scientific research articles (2.2B tokens).
This is a cased (case-sensitive) model. The tokenizer will not convert all inputs to lower-case by default.
The model is based on the same architecture as BERT-large and has a total of 340M parameters.
| Hyperparameter | Value |
|---|---|
| Layers | 24 |
| Hidden Size | 1024 |
| Attention Heads | 16 |
| Total Parameters | 340M |
The vocab and the model are pertrained on 1% of the PRD scientific literature dataset.
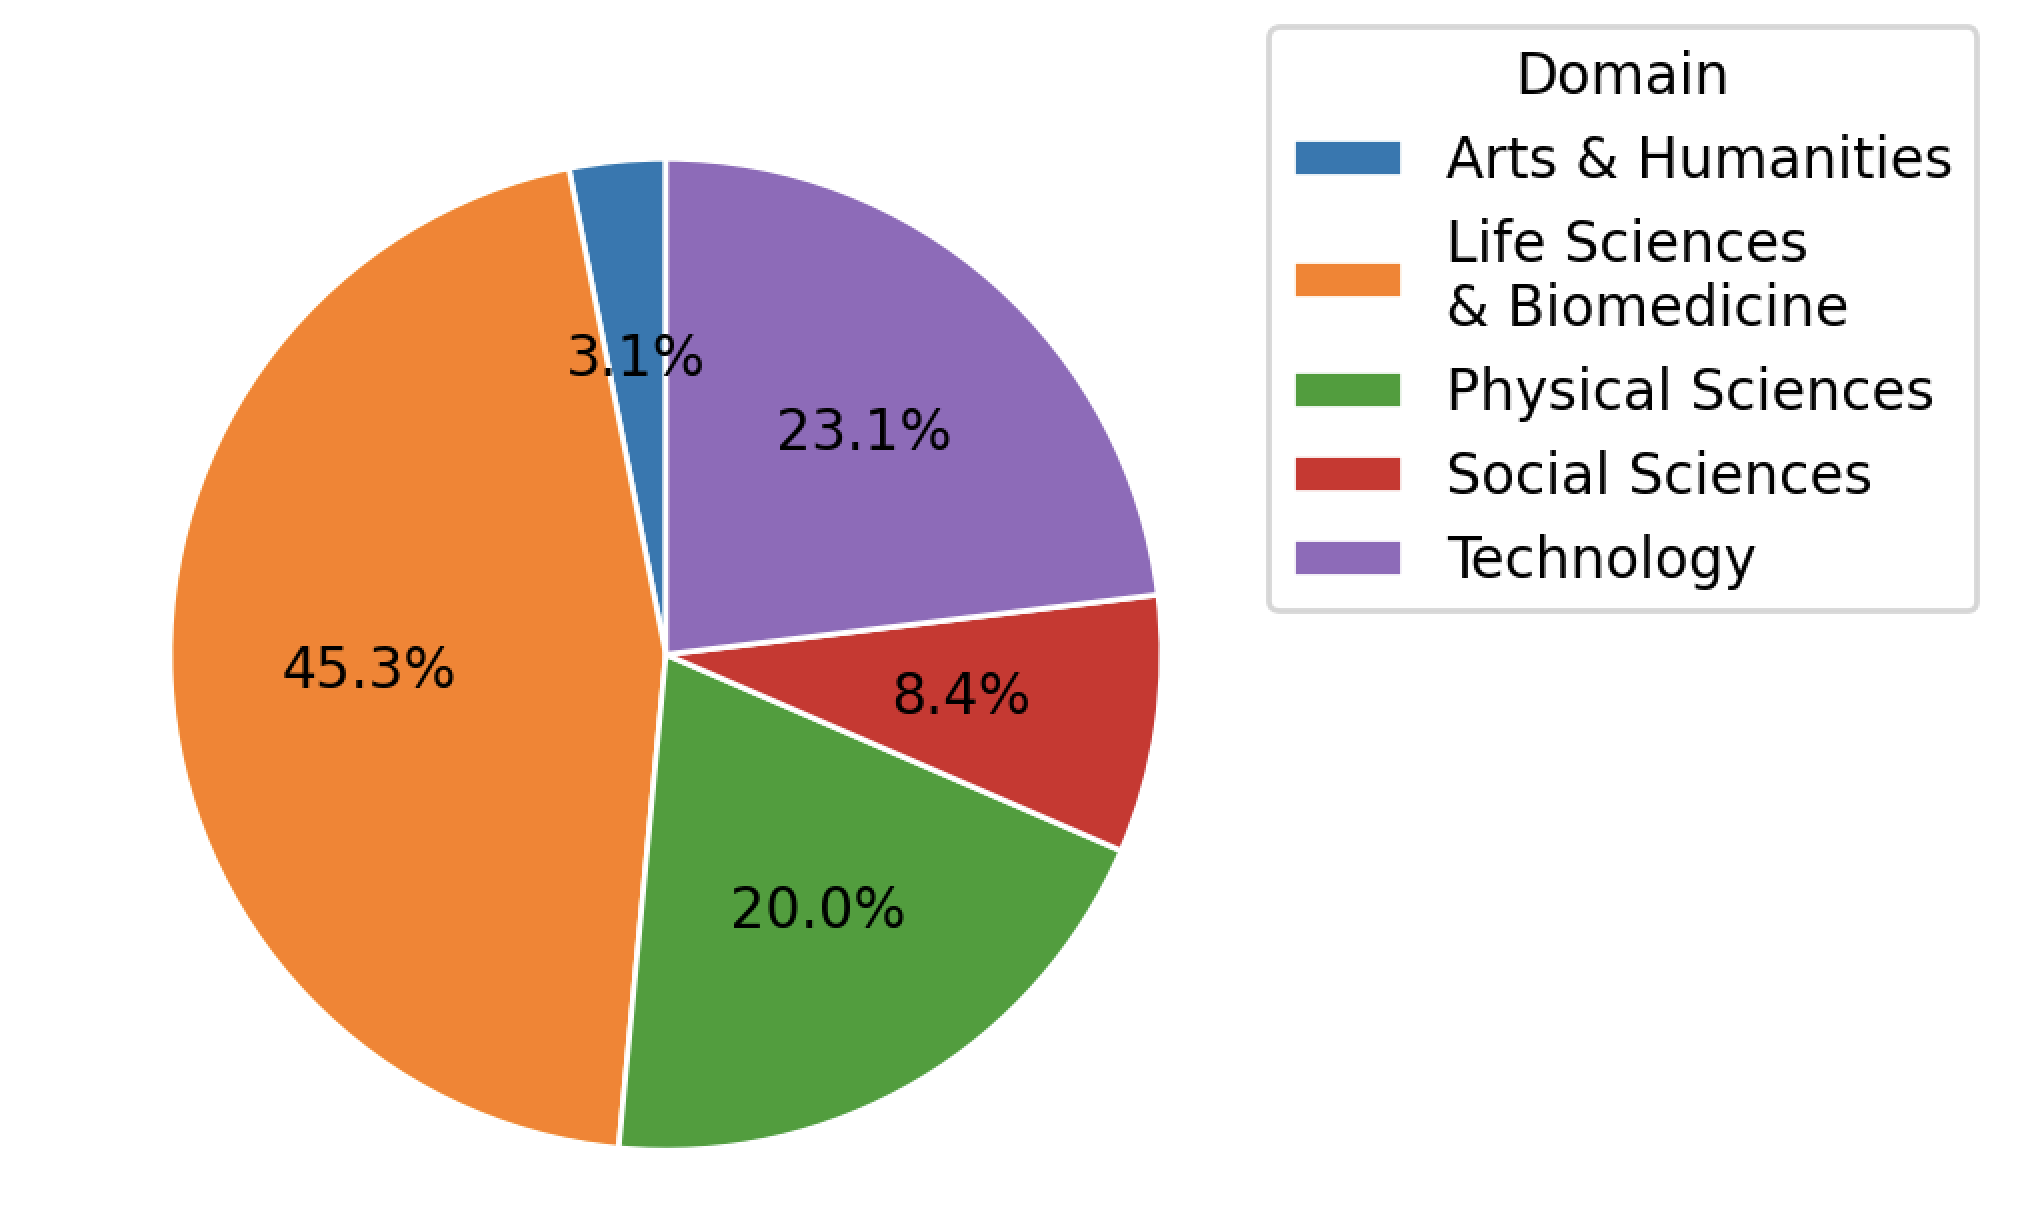
The PRD dataset is provided by Public.Resource.Org, Inc. (“Public Resource”), a nonprofit organization based in California. This dataset was constructed from a corpus of journal article files, from which We successfully extracted text from 75,496,055 articles from 178,928 journals. The articles span across Arts & Humanities, Life Sciences & Biomedicine, Physical Sciences, Social Sciences, and Technology. The distribution of articles is shown below.
If using this model, please cite this paper:
@misc{hong2023diminishing,
      title={The Diminishing Returns of Masked Language Models to Science},
      author={Zhi Hong and Aswathy Ajith and Gregory Pauloski and Eamon Duede and Kyle Chard and Ian Foster},
      year={2023},
      eprint={2205.11342},
      archivePrefix={arXiv},
      primaryClass={cs.CL}
}