
Downloads · 30 days
42
3% of all-time downloads
globuslabs/ScholarBERT-XL
ScholarBERT-XL is a fill-mask model from globuslabs. Use it when you need the model to fill a missing word. It is set up for transformers. The card lists the license as apache-2.0.
This is the ScholarBERT-XL100 variant of the ScholarBERT model family.
Downloads · 30 days
42
3% of all-time downloads
All-time downloads
1.5K
Public
Parameters
775M
6.2 GB on disk
Likes
8
Public
Click a slice to open those files.
.bin3.1 GB · 50%
How the weights are stored.
F32775M · 100%
From the Hugging Face model README
This is the ScholarBERT-XL_100 variant of the ScholarBERT model family.
The model is pretrained on a large collection of scientific research articles (221B tokens).
This is a cased (case-sensitive) model. The tokenizer will not convert all inputs to lower-case by default.
The model has a total of 770M parameters.
| Hyperparameter | Value |
|---|---|
| Layers | 36 |
| Hidden Size | 1280 |
| Attention Heads | 20 |
| Total Parameters | 770M |
The vocab and the model are pertrained on 100% of the PRD scientific literature dataset.
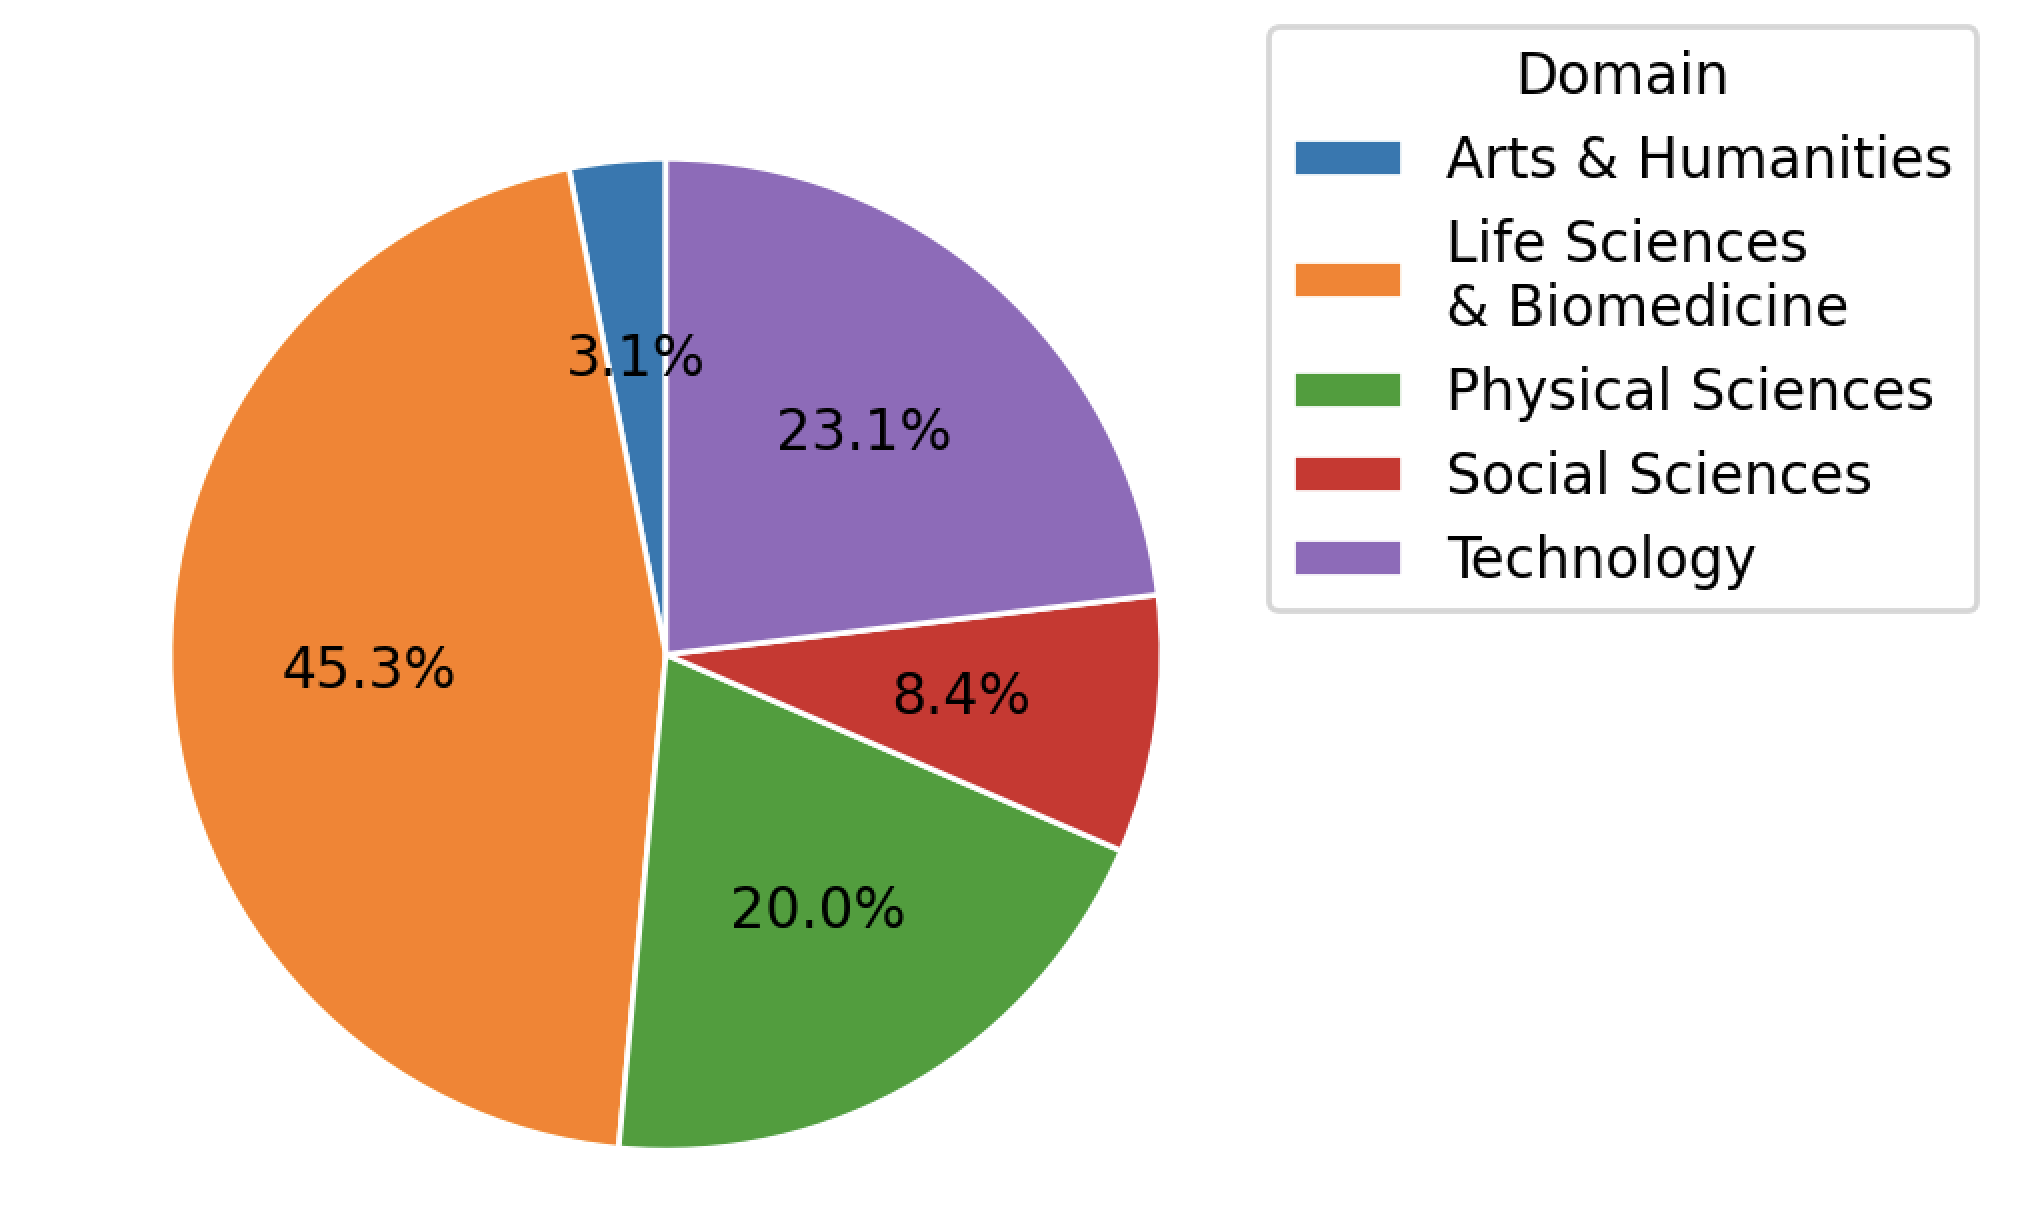
The PRD dataset is provided by Public.Resource.Org, Inc. (“Public Resource”), a nonprofit organization based in California. This dataset was constructed from a corpus of journal article files, from which We successfully extracted text from 75,496,055 articles from 178,928 journals. The articles span across Arts & Humanities, Life Sciences & Biomedicine, Physical Sciences, Social Sciences, and Technology. The distribution of articles is shown below.
If using this model, please cite this paper:
@inproceedings{hong2023diminishing,
  title={The diminishing returns of masked language models to science},
  author={Hong, Zhi and Ajith, Aswathy and Pauloski, James and Duede, Eamon and Chard, Kyle and Foster, Ian},
  booktitle={Findings of the Association for Computational Linguistics: ACL 2023},
  pages={1270--1283},
  year={2023}
}