Downloads · 30 days
9
2% of all-time downloads
fxmarty/distilbert-base-uncased-finetuned-sst-2-english-int8-static-dedicated-qdq-everywhere
distilbert-base-uncased-finetuned-sst-2-english-int8-static-dedicated-qdq-everywhere is a text classification model from fxmarty. Use it when you need a label for a piece of text. It is set up for transformers. The card lists the license as apache-2.0.
This model is a fork of https://huggingface.co/distilbert-base-uncased-finetuned-sst-2-english , quantized using static Post-Training Quantization (PTQ) with ONNX Runtime and 🤗 Optimum library.
Downloads · 30 days
9
2% of all-time downloads
All-time downloads
417
Public
Repo size
268 MB
Likes
0
Public
Click a slice to open those files.
.onnx268 MB · 100%
From the Hugging Face model README
This model is a fork of https://huggingface.co/distilbert-base-uncased-finetuned-sst-2-english , quantized using static Post-Training Quantization (PTQ) with ONNX Runtime and 🤗 Optimum library.
It achieves 0.896 accuracy on the validation set.
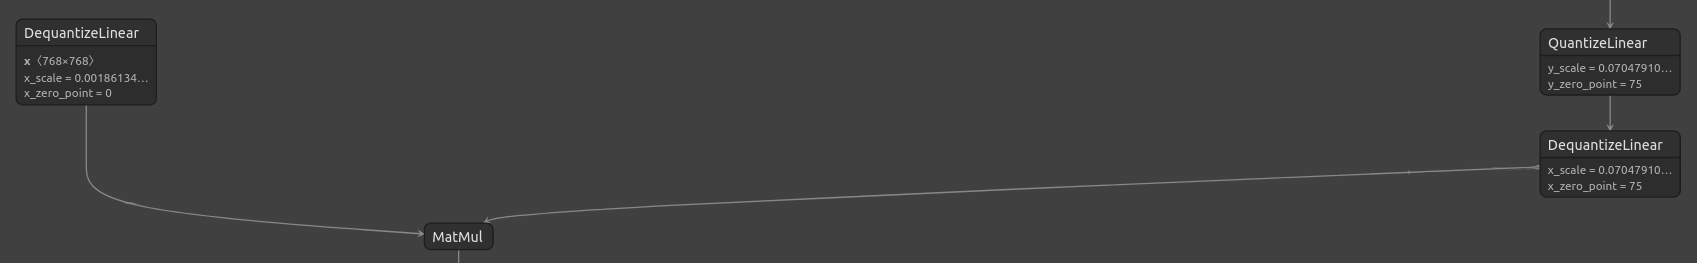
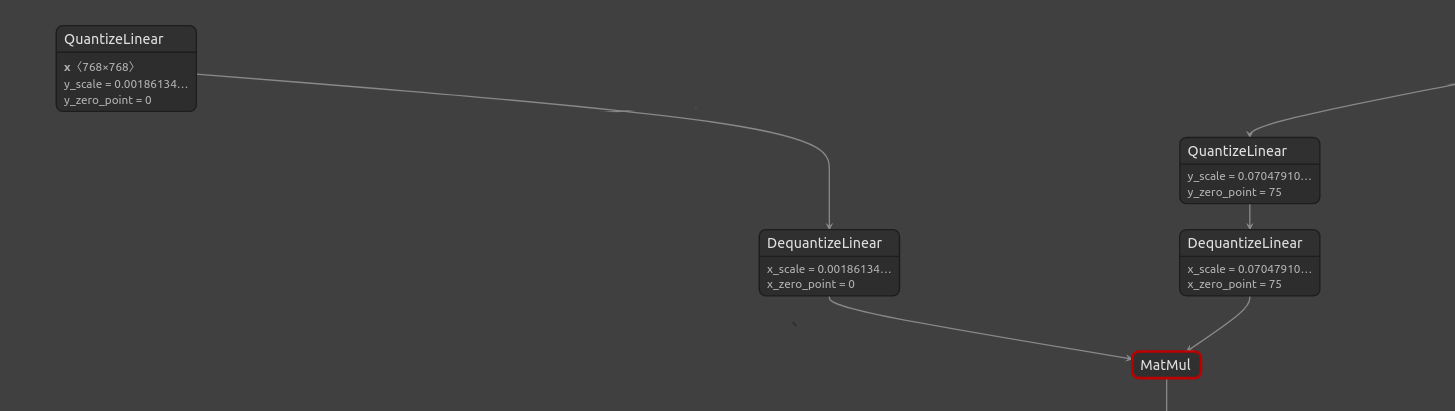
This model uses the ONNX Runtime static quantization configurations qdq_add_pair_to_weight=True and qdq_dedicated_pair=True, so that weights are stored in fp32, and full Quantize + Dequantize nodes are inserted for the weights, compared to the default where weights are stored in int8 and only a Dequantize node is inserted for weights. Moreover, here QDQ pairs have a single output. For more reference, see the documentation: https://github.com/microsoft/onnxruntime/blob/ade0d291749144e1962884a9cfa736d4e1e80ff8/onnxruntime/python/tools/quantization/quantize.py#L432-L441
This is useful to later load a static quantized model in TensorRT.
To load this model:
from optimum.onnxruntime import ORTModelForSequenceClassification
model = ORTModelForSequenceClassification.from_pretrained("fxmarty/distilbert-base-uncased-finetuned-sst-2-english-int8-static-dedicated-qdq-everywhere")