
Downloads · 30 days
11K
0% of all-time downloads
flaviagiammarino/pubmed-clip-vit-base-patch32
pubmed-clip-vit-base-patch32 is a zero-shot image classification model from flaviagiammarino. Use it for the zero-shot image classification task on the model card, and read the license before you ship it in a product. It is set up for transformers. The card lists the license as mit.
PubMedCLIP is a fine-tuned version of CLIP for the medical domain.
Downloads · 30 days
11K
0% of all-time downloads
All-time downloads
3.1M
Public
Repo size
2.4 GB
Likes
23
Public
Click a slice to open those files.
.h5606 MB · 33%
From the Hugging Face model README
PubMedCLIP is a fine-tuned version of CLIP for the medical domain.
PubMedCLIP was trained on the Radiology Objects in COntext (ROCO) dataset, a large-scale multimodal medical imaging dataset. The ROCO dataset includes diverse imaging modalities (such as X-Ray, MRI, ultrasound, fluoroscopy, etc.) from various human body regions (such as head, spine, chest, abdomen, etc.) captured from open-access PubMed articles.<br>
PubMedCLIP was trained for 50 epochs with a batch size of 64 using the Adam optimizer with a learning rate of 10−5. The authors have released three different pre-trained models at this link which use ResNet-50, ResNet-50x4 and ViT32 as image encoders. This repository includes only the ViT32 variant of the PubMedCLIP model.<br>
import requests
from PIL import Image
import matplotlib.pyplot as plt

from transformers import CLIPProcessor, CLIPModel

model = CLIPModel.from_pretrained("flaviagiammarino/pubmed-clip-vit-base-patch32")
processor = CLIPProcessor.from_pretrained("flaviagiammarino/pubmed-clip-vit-base-patch32")

url = "https://huggingface.co/flaviagiammarino/pubmed-clip-vit-base-patch32/resolve/main/scripts/input.jpeg"
image = Image.open(requests.get(url, stream=True).raw)
text = ["Chest X-Ray", "Brain MRI", "Abdominal CT Scan"]

inputs = processor(text=text, images=image, return_tensors="pt", padding=True)
probs = model(**inputs).logits_per_image.softmax(dim=1).squeeze()

plt.subplots()
plt.imshow(image)
plt.title("".join([x[0] + ": " + x[1] + "\n" for x in zip(text, [format(prob, ".4%") for prob in probs])]))
plt.axis("off")
plt.tight_layout()
plt.show()
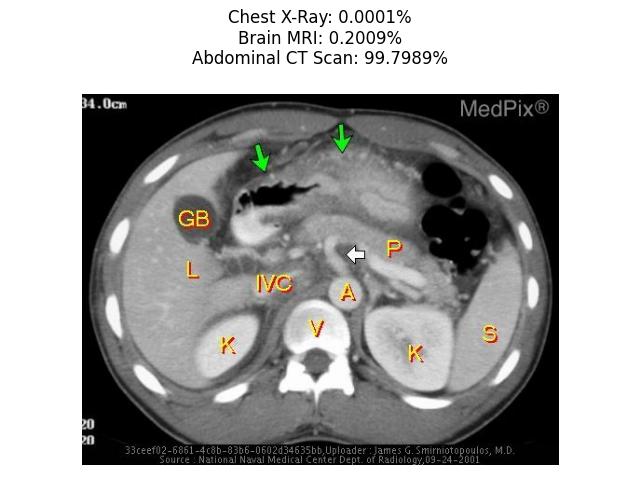
The authors have released the model code and pre-trained checkpoints under the MIT License.
@article{eslami2021does,
  title={Does clip benefit visual question answering in the medical domain as much as it does in the general domain?},
  author={Eslami, Sedigheh and de Melo, Gerard and Meinel, Christoph},
  journal={arXiv preprint arXiv:2112.13906},
  year={2021}
}