
Downloads · 30 days
17
0% of all-time downloads
emilianJR/RealisticVision_V2
RealisticVision_V2 is a text-to-image model from emilianJR. Use it when you need an image from a text prompt. It is set up for diffusers. The card lists the license as creativeml-openrail-m.
Diffuser model for this SD checkpoint: https://civitai.com/models/4201?modelVersionId=29460
Downloads · 30 days
17
0% of all-time downloads
All-time downloads
23K
Public
Repo size
5.5 GB
Likes
7
Public
Click a slice to open those files.
.bin5.5 GB · 100%
From the Hugging Face model README
Diffuser model for this SD checkpoint: https://civitai.com/models/4201?modelVersionId=29460
emilianJR/RealisticVision_V2 is the HuggingFace diffuser that you can use with diffusers.StableDiffusionPipeline().
| Examples | Examples | Examples |
|---|---|---|
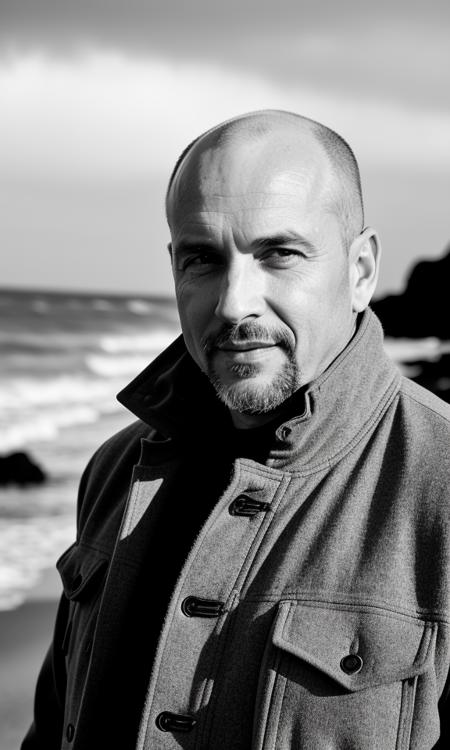 | 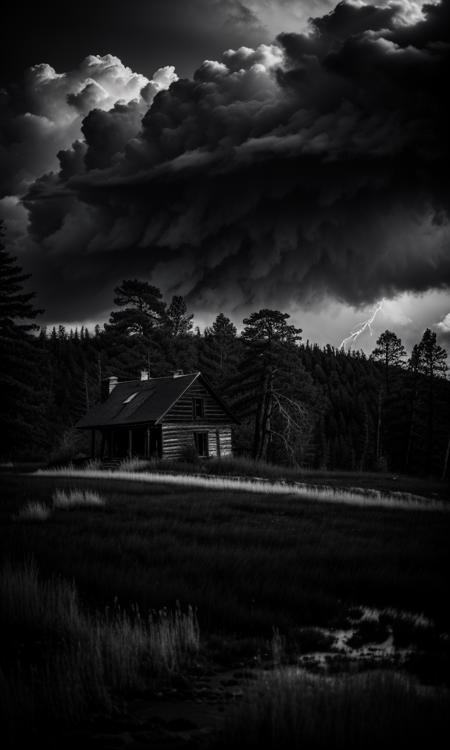 | 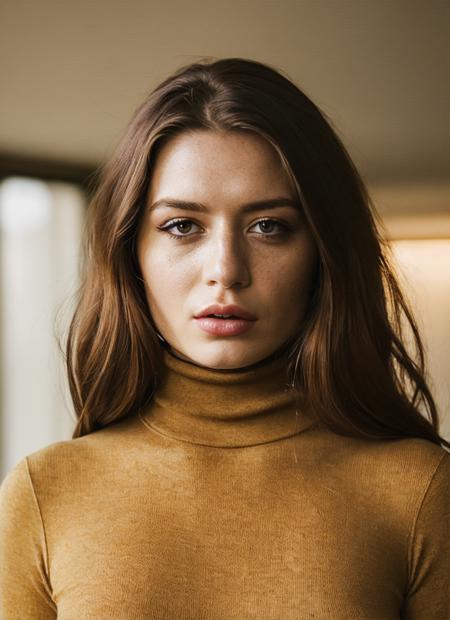 |
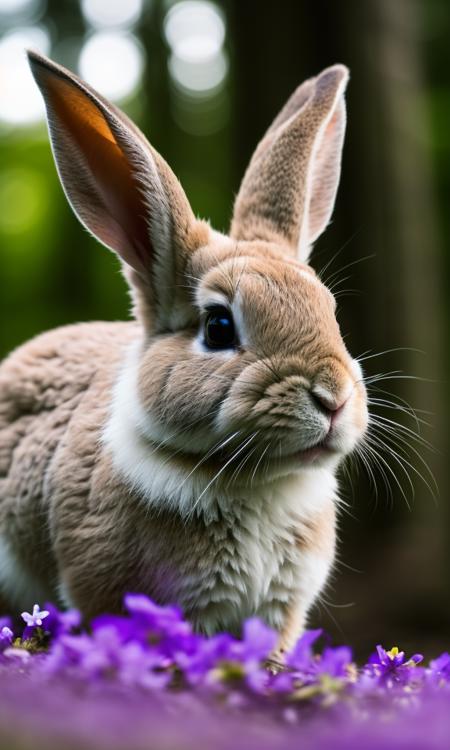 | 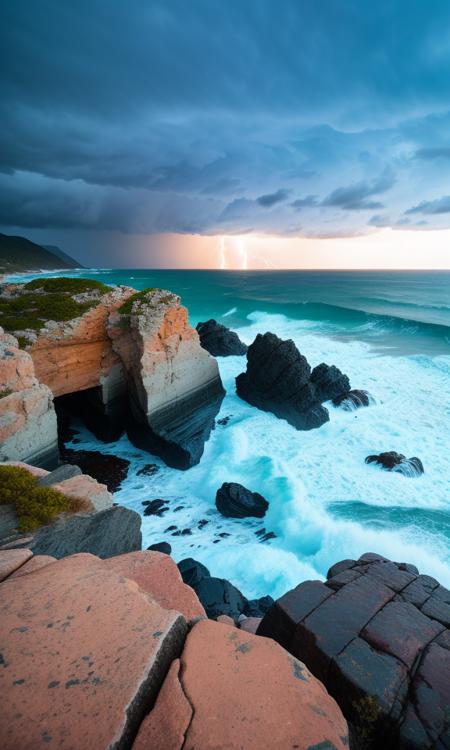 | 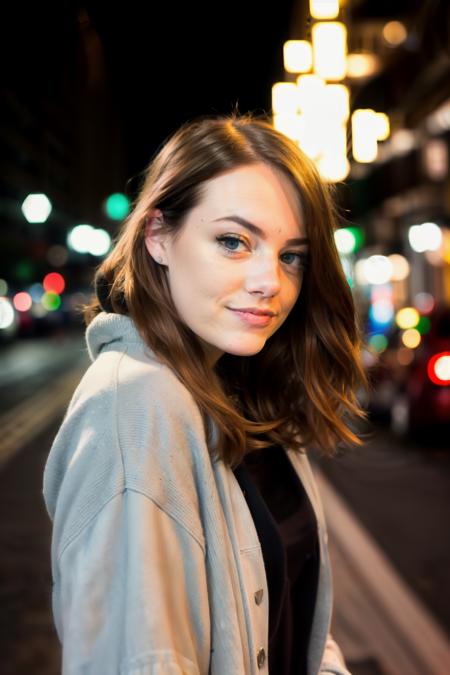 |
This model can be used just like any other Stable Diffusion model. For more information, please have a look at the Stable Diffusion.
from diffusers import StableDiffusionPipeline
import torch

model_id = "emilianJR/RealisticVision_V2"
pipe = StableDiffusionPipeline.from_pretrained(model_id, torch_dtype=torch.float16)
pipe = pipe.to("cuda")

prompt = "YOUR PROMPT"
image = pipe(prompt).images[0]

image.save("image.png")
This model is open access and available to all, with a CreativeML OpenRAIL-M license further specifying rights and usage. The CreativeML OpenRAIL License specifies: Please read the full license here