
Downloads · 30 days
94.8K
1% of all-time downloads
diffusers/stable-diffusion-xl-1.0-inpainting-0.1
stable-diffusion-xl-1.0-inpainting-0.1 is a text-to-image model from diffusers. Use it when you need an image from a text prompt. It is set up for diffusers. The card lists the license as openrail++.
Downloads · 30 days
94.8K
1% of all-time downloads
All-time downloads
14.1M
Public
Parameters
2.6B
20.8 GB on disk
Likes
388
Trending 1
Click a slice to open those files.
.safetensors20.8 GB · 100%
From the Hugging Face model README
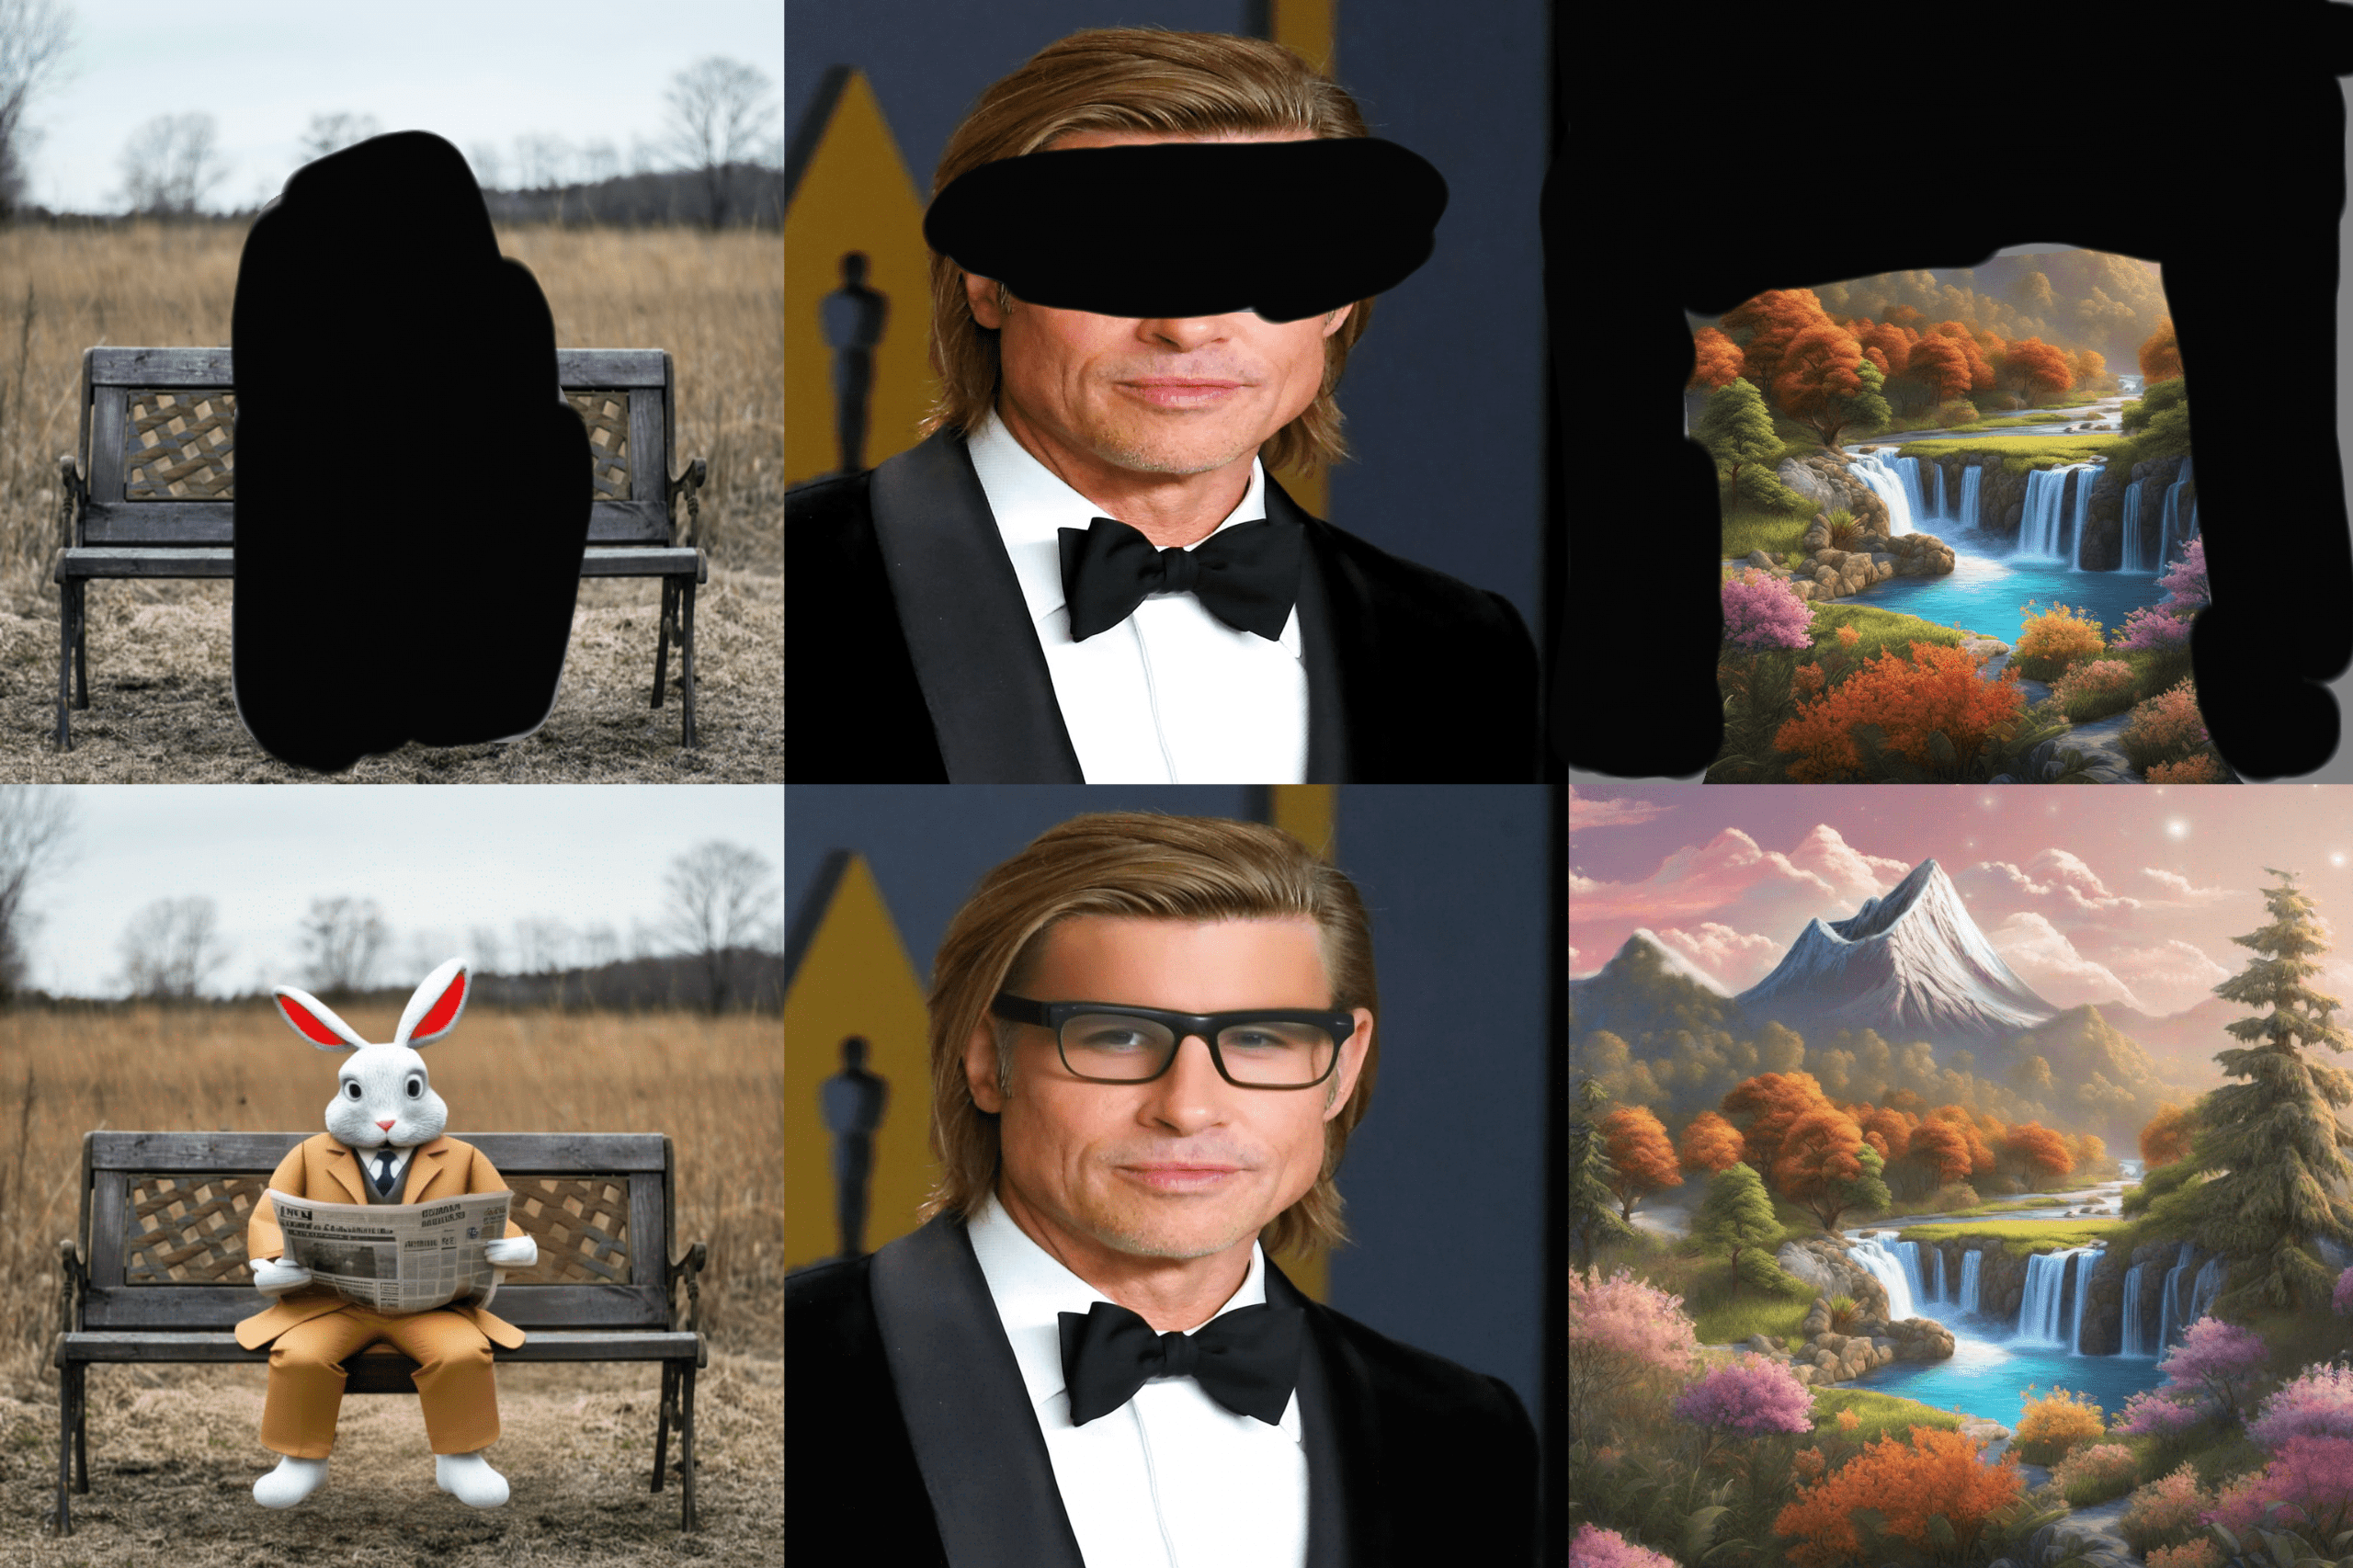
SD-XL Inpainting 0.1 is a latent text-to-image diffusion model capable of generating photo-realistic images given any text input, with the extra capability of inpainting the pictures by using a mask.
The SD-XL Inpainting 0.1 was initialized with the stable-diffusion-xl-base-1.0 weights. The model is trained for 40k steps at resolution 1024x1024 and 5% dropping of the text-conditioning to improve classifier-free classifier-free guidance sampling. For inpainting, the UNet has 5 additional input channels (4 for the encoded masked-image and 1 for the mask itself) whose weights were zero-initialized after restoring the non-inpainting checkpoint. During training, we generate synthetic masks and, in 25% mask everything.
from diffusers import AutoPipelineForInpainting
from diffusers.utils import load_image
import torch

pipe = AutoPipelineForInpainting.from_pretrained("diffusers/stable-diffusion-xl-1.0-inpainting-0.1", torch_dtype=torch.float16, variant="fp16").to("cuda")

img_url = "https://raw.githubusercontent.com/CompVis/latent-diffusion/main/data/inpainting_examples/overture-creations-5sI6fQgYIuo.png"
mask_url = "https://raw.githubusercontent.com/CompVis/latent-diffusion/main/data/inpainting_examples/overture-creations-5sI6fQgYIuo_mask.png"

image = load_image(img_url).resize((1024, 1024))
mask_image = load_image(mask_url).resize((1024, 1024))

prompt = "a tiger sitting on a park bench"
generator = torch.Generator(device="cuda").manual_seed(0)

image = pipe(
  prompt=prompt,
  image=image,
  mask_image=mask_image,
  guidance_scale=8.0,
  num_inference_steps=20,  # steps between 15 and 30 work well for us
  strength=0.99,  # make sure to use `strength` below 1.0
  generator=generator,
).images[0]
How it works:
image | mask_image |
|---|---|
| <img src="https://raw.githubusercontent.com/CompVis/latent-diffusion/main/data/inpainting_examples/overture-creations-5sI6fQgYIuo.png" alt="drawing" width="300"/> | <img src="https://raw.githubusercontent.com/CompVis/latent-diffusion/main/data/inpainting_examples/overture-creations-5sI6fQgYIuo_mask.png" alt="drawing" width="300"/> |
prompt | Output |
|---|---|
| <span style="position: relative;bottom: 150px;">a tiger sitting on a park bench</span> | <img src="https://huggingface.co/datasets/valhalla/images/resolve/main/tiger.png" alt="drawing" width="300"/> |
The model is intended for research purposes only. Possible research areas and tasks include
Excluded uses are described below.
The model was not trained to be factual or true representations of people or events, and therefore using the model to generate such content is out-of-scope for the abilities of this model.
While the capabilities of image generation models are impressive, they can also reinforce or exacerbate social biases.